<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom">
    <title>softminus</title>
    <link href="https://softminus.org/atom.xml" rel="self" />
    <link href="https://softminus.org" />
    <id>https://softminus.org/atom.xml</id>
    <author>
        <name>sasha</name>
        <email>softminus@gmail.com</email>
    </author>
    <updated>2023-05-05T00:00:00Z</updated>
    <entry>
    <title>GSM receiver blocks: timing synchronization (part 3: less talk, more fight)</title>
    <link href="https://softminus.org/posts/time-sync-part-3.html" />
    <id>https://softminus.org/posts/time-sync-part-3.html</id>
    <published>2023-05-05</published>
    <updated>2023-05-05T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-timing-synchronization-part-3-less-talk-more-fight">GSM receiver blocks: timing synchronization (part 3: less talk, more fight)</h1>
<p>In the last <a href="time-sync-part-2.html">post</a>, we had thought up of some ideas for how to do timing synchronization. We note that this is not exactly how GSM works – with GSM you have special bursts that are used for timing synchronization, and the receiver uses those to keep its clock in sync with the transmitter. Since we’re not actually implementing a GSM receiver (how many GSM networks remain?), we’re going to look at the generic case of doing timing synchronization with a known training sequence in the presence of severe multipath (mostly for training purposes. I think this stuff is neat and I want to get better at it).</p>
<h2 id="more-samples-better-peak-less-sidelobes">More samples, better peak, less sidelobes <a href="#more-samples-better-peak-less-sidelobes" class="section">#</a></h2>
<p>We try out various correlations and see what happens (literally, we’re eyeballing stuff here):</p>
<div class="sourceCode" id="cb1"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb1-1"><a href="#cb1-1" aria-hidden="true" tabindex="-1"></a><span class="va">tiledlayout</span>(<span class="fl">2</span><span class="op">,</span><span class="fl">2</span>)</span>
<span id="cb1-2"><a href="#cb1-2" aria-hidden="true" tabindex="-1"></a><span class="va">nexttile</span></span>
<span id="cb1-3"><a href="#cb1-3" aria-hidden="true" tabindex="-1"></a>[<span class="va">c</span><span class="op">,</span> <span class="va">lagz</span>] <span class="op">=</span> <span class="va">xcorr</span>(<span class="va">received</span><span class="op">,</span> <span class="va">modulated_training_sequence</span>(<span class="fl">1</span><span class="op">:</span><span class="kw">end</span>))<span class="op">;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">c</span>(<span class="fl">200</span><span class="op">:</span><span class="kw">end</span>)))</span>
<span id="cb1-4"><a href="#cb1-4" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;correlation with full training sequence&quot;</span>)</span>
<span id="cb1-5"><a href="#cb1-5" aria-hidden="true" tabindex="-1"></a><span class="va">nexttile</span></span>
<span id="cb1-6"><a href="#cb1-6" aria-hidden="true" tabindex="-1"></a>[<span class="va">c</span><span class="op">,</span> <span class="va">lagz</span>] <span class="op">=</span> <span class="va">xcorr</span>(<span class="va">received</span><span class="op">,</span> <span class="va">modulated_training_sequence</span>(<span class="fl">9</span><span class="op">:</span><span class="kw">end</span>))<span class="op">;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">c</span>(<span class="fl">200</span><span class="op">:</span><span class="kw">end</span>)))</span>
<span id="cb1-7"><a href="#cb1-7" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;correlation with TS(9:end)&quot;</span>)</span>
<span id="cb1-8"><a href="#cb1-8" aria-hidden="true" tabindex="-1"></a><span class="va">nexttile</span></span>
<span id="cb1-9"><a href="#cb1-9" aria-hidden="true" tabindex="-1"></a>[<span class="va">c</span><span class="op">,</span> <span class="va">lagz</span>] <span class="op">=</span> <span class="va">xcorr</span>(<span class="va">received</span><span class="op">,</span> <span class="va">modulated_training_sequence</span>(<span class="fl">1</span><span class="op">:</span><span class="kw">end</span><span class="op">-</span><span class="fl">8</span>))<span class="op">;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">c</span>(<span class="fl">200</span><span class="op">:</span><span class="kw">end</span>)))</span>
<span id="cb1-10"><a href="#cb1-10" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;correlation with TS(1:end-8)&quot;</span>)</span>
<span id="cb1-11"><a href="#cb1-11" aria-hidden="true" tabindex="-1"></a><span class="va">nexttile</span></span>
<span id="cb1-12"><a href="#cb1-12" aria-hidden="true" tabindex="-1"></a>[<span class="va">c</span><span class="op">,</span> <span class="va">lagz</span>] <span class="op">=</span> <span class="va">xcorr</span>(<span class="va">received</span><span class="op">,</span> <span class="va">modulated_training_sequence</span>(<span class="fl">9</span><span class="op">:</span><span class="kw">end</span><span class="op">-</span><span class="fl">8</span>))<span class="op">;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">c</span>(<span class="fl">200</span><span class="op">:</span><span class="kw">end</span>)))</span>
<span id="cb1-13"><a href="#cb1-13" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;correlation with TS(9:end-8)&quot;</span>)</span>
<span id="cb1-14"><a href="#cb1-14" aria-hidden="true" tabindex="-1"></a><span class="va">copygraphics</span>(<span class="va">gcf</span>)</span></code></pre></div>
<p>and we get the following plot. Note that the vertical scale is different for each of the subplots.
<img src="../images/time-sync-part-3/comparison_trimming.png" alt="Correlation outputs with MATLAB’s xcorr; click for full size" /></p>
<p>OK, so as we kinda suspected in the previous post, using a longer correlation template leads to less sidelobe amplitude without obvious widening of the true correlation peak.</p>
<h2 id="writing-an-estimator">Writing an estimator <a href="#writing-an-estimator" class="section">#</a></h2>
<p>Now that we’ve decided to use the full training sequence for doing correlation in time, let’s write out an estimator. First of all, we correlate the received signal with the training sequence:</p>
<div class="sourceCode" id="cb2"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb2-1"><a href="#cb2-1" aria-hidden="true" tabindex="-1"></a><span class="va">correlation_output</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">signal</span><span class="op">,</span> <span class="va">conj</span>(<span class="va">flip</span>(<span class="va">modulated_training_sequence</span>)))<span class="op">;</span></span>
<span id="cb2-2"><a href="#cb2-2" aria-hidden="true" tabindex="-1"></a>[<span class="va">val</span><span class="op">,</span> <span class="va">uncorrected_offset</span>] <span class="op">=</span> <span class="va">max</span>(<span class="va">correlation_output</span>)<span class="op">;</span></span></code></pre></div>
<h2 id="running-it">Running it <a href="#running-it" class="section">#</a></h2>
<p>We use the same channel (otherwise the shape of the correlation peak will be different across runs), and we run it a bunch of times with the same training sequence and random data:</p>
<div class="sourceCode" id="cb3"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb3-1"><a href="#cb3-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-2"><a href="#cb3-2" aria-hidden="true" tabindex="-1"></a><span class="co">% signal creation</span></span>
<span id="cb3-3"><a href="#cb3-3" aria-hidden="true" tabindex="-1"></a><span class="va">training_sequence</span> <span class="op">=</span> <span class="va">randi</span>([<span class="fl">0</span> <span class="fl">1</span>]<span class="op">,</span> <span class="fl">32</span><span class="op">,</span><span class="fl">1</span>) <span class="co">%[0,1,0,0,0,1,1,1,1,0,1,1,0,1,0,0,0,1,0,0,0,1,1,1,1,0]&#39;;</span></span>
<span id="cb3-4"><a href="#cb3-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-5"><a href="#cb3-5" aria-hidden="true" tabindex="-1"></a><span class="co">% channel creation</span></span>
<span id="cb3-6"><a href="#cb3-6" aria-hidden="true" tabindex="-1"></a><span class="va">nominal_sample_rate</span> <span class="op">=</span> <span class="fl">1e6</span> <span class="op">*</span> (<span class="fl">13</span><span class="op">/</span><span class="fl">48</span>)<span class="op">;</span></span>
<span id="cb3-7"><a href="#cb3-7" aria-hidden="true" tabindex="-1"></a><span class="va">signal_channel</span> <span class="op">=</span> <span class="va">stdchan</span>(<span class="st">&quot;gsmEQx6&quot;</span><span class="op">,</span> <span class="va">nominal_sample_rate</span><span class="op">,</span> <span class="fl">0</span>)<span class="op">;</span></span>
<span id="cb3-8"><a href="#cb3-8" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-9"><a href="#cb3-9" aria-hidden="true" tabindex="-1"></a><span class="va">modulated_training_sequence</span> <span class="op">=</span> <span class="va">minimal_modulation</span>(<span class="va">training_sequence</span>)<span class="op">;</span></span>
<span id="cb3-10"><a href="#cb3-10" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-11"><a href="#cb3-11" aria-hidden="true" tabindex="-1"></a><span class="va">average_convolution</span> <span class="op">=</span> <span class="va">zeros</span>(<span class="fl">319</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span></span>
<span id="cb3-12"><a href="#cb3-12" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-13"><a href="#cb3-13" aria-hidden="true" tabindex="-1"></a><span class="va">average_convolution_energy</span> <span class="op">=</span> <span class="va">zeros</span>(<span class="fl">319</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span></span>
<span id="cb3-14"><a href="#cb3-14" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-15"><a href="#cb3-15" aria-hidden="true" tabindex="-1"></a><span class="kw">for</span> <span class="va">i</span> <span class="op">=</span> <span class="fl">1</span><span class="op">:</span><span class="fl">1024</span></span>
<span id="cb3-16"><a href="#cb3-16" aria-hidden="true" tabindex="-1"></a>	<span class="va">data</span> <span class="op">=</span> [<span class="va">randi</span>([<span class="fl">0</span> <span class="fl">1</span>]<span class="op">,</span><span class="fl">128</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span> <span class="va">training_sequence</span><span class="op">;</span> <span class="va">randi</span>([<span class="fl">0</span> <span class="fl">1</span>]<span class="op">,</span> <span class="fl">128</span><span class="op">,</span><span class="fl">1</span>)]<span class="op">;</span></span>
<span id="cb3-17"><a href="#cb3-17" aria-hidden="true" tabindex="-1"></a>	<span class="va">modulated</span> <span class="op">=</span> <span class="va">minimal_modulation</span>(<span class="va">data</span>)<span class="op">;</span></span>
<span id="cb3-18"><a href="#cb3-18" aria-hidden="true" tabindex="-1"></a>	<span class="va">signal_channel</span>(<span class="va">complex</span>(<span class="va">zeros</span>(<span class="fl">30</span><span class="op">,</span><span class="fl">1</span>)))<span class="op">;</span></span>
<span id="cb3-19"><a href="#cb3-19" aria-hidden="true" tabindex="-1"></a>	<span class="va">received</span> <span class="op">=</span> <span class="va">signal_channel</span>(<span class="va">modulated</span>)<span class="op">;</span></span>
<span id="cb3-20"><a href="#cb3-20" aria-hidden="true" tabindex="-1"></a>	<span class="va">awgned</span> <span class="op">=</span> <span class="va">awgn</span>(<span class="va">received</span><span class="op">,</span><span class="fl">80</span>)<span class="op">;</span></span>
<span id="cb3-21"><a href="#cb3-21" aria-hidden="true" tabindex="-1"></a>    <span class="va">first_convolution</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">awgned</span><span class="op">,</span> <span class="va">conj</span>(<span class="va">flip</span>(<span class="va">modulated_training_sequence</span>)))<span class="op">;</span></span>
<span id="cb3-22"><a href="#cb3-22" aria-hidden="true" tabindex="-1"></a>    <span class="va">average_convolution_energy</span> <span class="op">=</span> <span class="va">average_convolution_energy</span> <span class="op">+</span> <span class="va">abs</span>(<span class="va">first_convolution</span>)<span class="op">;</span></span>
<span id="cb3-23"><a href="#cb3-23" aria-hidden="true" tabindex="-1"></a>    <span class="va">average_convolution</span> <span class="op">=</span> <span class="va">average_convolution</span> <span class="op">+</span> <span class="va">first_convolution</span><span class="op">;</span></span>
<span id="cb3-24"><a href="#cb3-24" aria-hidden="true" tabindex="-1"></a><span class="kw">end</span></span>
<span id="cb3-25"><a href="#cb3-25" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-26"><a href="#cb3-26" aria-hidden="true" tabindex="-1"></a><span class="va">figure</span><span class="op">;</span></span>
<span id="cb3-27"><a href="#cb3-27" aria-hidden="true" tabindex="-1"></a><span class="va">plot</span>(<span class="va">abs</span>(<span class="va">average_convolution</span>))<span class="op">;</span></span>
<span id="cb3-28"><a href="#cb3-28" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;average convolution output&quot;</span>)<span class="op">;</span></span>
<span id="cb3-29"><a href="#cb3-29" aria-hidden="true" tabindex="-1"></a><span class="va">figure</span><span class="op">;</span> </span>
<span id="cb3-30"><a href="#cb3-30" aria-hidden="true" tabindex="-1"></a><span class="va">plot</span>(<span class="va">abs</span>(<span class="va">average_convolution_energy</span>))<span class="op">;</span></span>
<span id="cb3-31"><a href="#cb3-31" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;average convolution energy output&quot;</span>)<span class="op">;</span></span>
<span id="cb3-32"><a href="#cb3-32" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-33"><a href="#cb3-33" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-34"><a href="#cb3-34" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb3-35"><a href="#cb3-35" aria-hidden="true" tabindex="-1"></a><span class="kw">function</span> <span class="va">not_really_filtered</span> <span class="op">=</span> <span class="va">minimal_modulation</span>(<span class="va">data</span>) </span>
<span id="cb3-36"><a href="#cb3-36" aria-hidden="true" tabindex="-1"></a>	<span class="va">not_really_filtered</span> <span class="op">=</span> <span class="va">pammod</span>(<span class="va">data</span><span class="op">,</span><span class="fl">2</span>)<span class="op">;</span></span>
<span id="cb3-37"><a href="#cb3-37" aria-hidden="true" tabindex="-1"></a><span class="kw">end</span></span></code></pre></div>
<p>Output from a single run looks like this:</p>
<figure>
<img src="../images/time-sync-part-3/first_correlation.png" alt="first_convolution = conv(awgned, conj(flip(modulated_training_sequence))); click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/first_correlation.png"><code>first_convolution = conv(awgned, conj(flip(modulated_training_sequence)))</code></a>; click for full size</figcaption>
</figure>
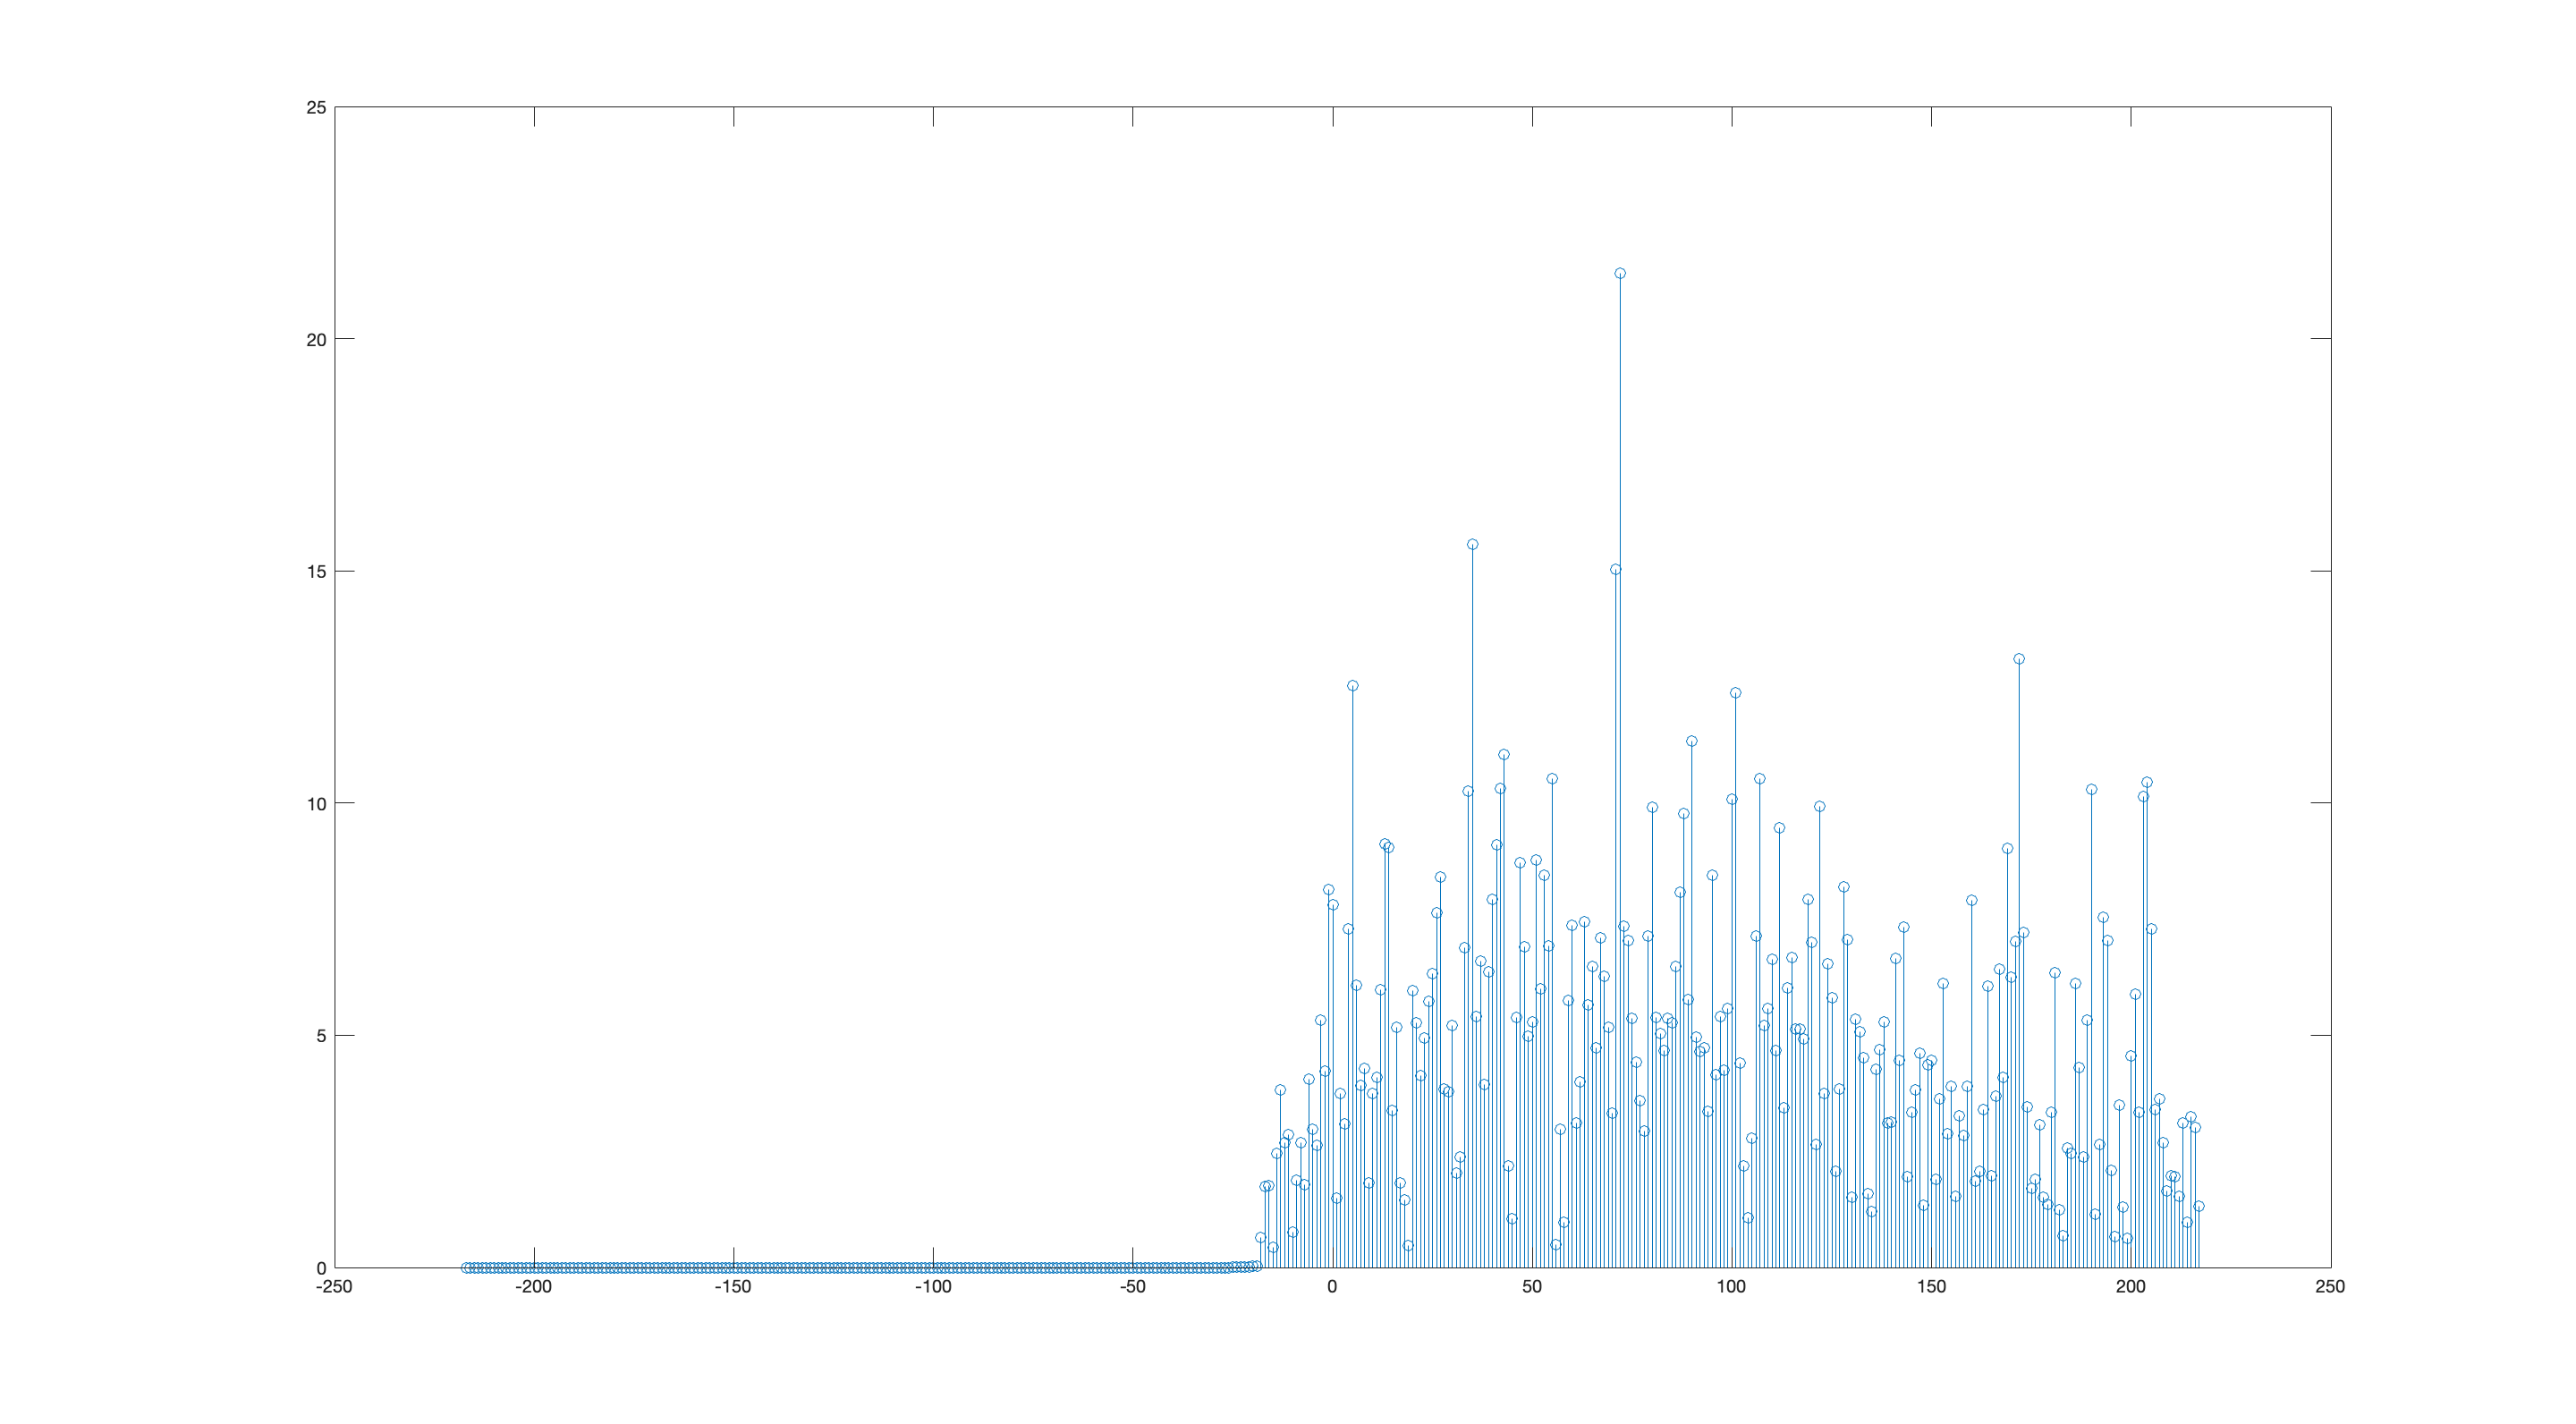
<p>And on average, we get something like this: the first image is the average of the outputs, the second image is the average of the <em>energy</em> of the outputs:</p>
<figure>
<img src="../images/time-sync-part-3/average_convolution_output.png" alt="average convolution output; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/average_convolution_output.png">average convolution output</a>; click for full size</figcaption>
</figure>
<figure>
<img src="../images/time-sync-part-3/average_convolution_energy.png" alt="average convolution energy; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/average_convolution_energy.png">average convolution energy</a>; click for full size</figcaption>
</figure>
<h2 id="eyeball-based-analysis">Eyeball-based analysis <a href="#eyeball-based-analysis" class="section">#</a></h2>
<p>We observe two things:</p>
<ol type="1">
<li><p>There isn’t a single sharp correlation peak – it has lots of structure, even when averaged over 1024 runs. Even more disquieting, the structure seems <em>constant</em> across runs on the same channel, even though the data is random.</p></li>
<li><p>For a single run, there’s a lot of sidelobe energy. It gets averaged away over many runs, but our estimator needs to work on a single run only.</p></li>
</ol>
<h2 id="dont-worry-too-much-about-the-sidelobes">Don’t worry too much about the sidelobes <a href="#dont-worry-too-much-about-the-sidelobes" class="section">#</a></h2>
<p>In an actual system, we almost always have additional information about our signal:</p>
<ul>
<li>when the signal started (energy detector)</li>
<li>when we expect it to start (local timing reference)</li>
<li>where the training sequence lives in the signal (hopefully the implementer has read the standard)</li>
</ul>
<p>Even if this information is somewhat coarse/inaccurate, it lets us remove some of the irrelevant bits (or rather, samples,) of the received signal before feeding it to the timing estimator, which will reduce how many sidelobes appear.</p>
<p>If the sidelobes are sufficiently far away from the main peak such that we can ignore them without too much additional information about signal structure, <strong>what truly matters is the shape and position of the intended correlation peak, and what’s immediately around it</strong>.</p>
<h2 id="channel-shape-influences-correlation-peak-structure">Channel shape influences correlation peak structure <a href="#channel-shape-influences-correlation-peak-structure" class="section">#</a></h2>
<p>Even if we avoid the sidelobes, it’s unclear <em>which part</em> of the correlation peak we should use as our timing estimate. The highest peak? The first peak above a significant threshold? It’s not unambiguous.</p>
<p>Training/synchronization sequences are generally selected to have negligible autocorrelation at non-zero delays – to improve, well, correlating against them. This means that when we correlate the received signal against the training sequence, we’ll get something that looks like the channel impulse response estimate – and the “sharper” the autocorrelation of the training sequence, the better that channel impulse response estimate will be.</p>
<p>If you think of the channel as a tapped delay line, then the <strong>peak</strong> of the correlation output corresponds to the “tap” (delay) with the highest magnitude. This doesn’t necessarily correspond to the first/“earliest” tap with a significant coefficient, nor does it generally correspond to the best timing for the least-squares channel estimation.</p>
<p>Naturally, if we only have a single big tap in our channel, this is probably fine: as long as the single big tap is in the window for the least-squares, we’re home free. However, if we have multiple significant taps – especially if they aren’t all bunched together – and want to do a good job, things get more complicated.</p>
<p>We need a better way to process this hedgehog-looking correlation peak.</p>
<h2 id="sliding-energy-window-heuristic">Sliding energy window heuristic <a href="#sliding-energy-window-heuristic" class="section">#</a></h2>
<p>Morally, to minimize bit error, we want to find the channel taps that give us the most energy. The more energy, the less the noise can perturb your decisions – that’s the extreme tl;dr of the whole Shannon thing. You don’t care about super-attenuated paths (their contributions are barely distinguishable from noise), and if you have a single path that’s much stronger than the others, you can ignore the others to pretend you don’t have a dispersive channel at all!</p>
<p>With Viterbi detection it’s a tad nontrivial to reason about it, but imagine a <a href="https://en.wikipedia.org/wiki/Rake_receiver">rake receiver</a>: if you want to get the most <strong>signal energy</strong> into your decision device, you need to identify the <strong>channel taps</strong> with the most energy. The rake receiver can pick out a finite but arbitrary set of paths, but with Viterbi, we need to decide on a <em>window</em> of the channel to use – everything within that window gets used, nothing outside gets used. That window tends to be fairly small: trellis-based detection is a controlled combinatorial explosion.</p>
<p>Since that window is precious, we need to cram as much energy into it as possible, and <strong>this</strong> is precisely why the timing estimator matters here. If our timing is suboptimal, we’re dropping valuable signal energy on the floor. This inspires a timing estimator design: run a window of appropriate size over the coarse channel impulse response (which is generated by the correlation we previously looked at) and pick the offset with the highest <strong>total energy in that window</strong>.</p>
<h3 id="aside-timing-error-in-the-non-isi-case">Aside: timing error in the non-ISI case <a href="#aside-timing-error-in-the-non-isi-case" class="section">#</a></h3>
<p>Note that with a more usual non-ISI case, timing matters because we want to sample the signal at the best time, otherwise the eye diagram closes and we get more bit errors. In this receiver architecture, channel estimation + Viterbi take care of that consideration: the fine timing estimate is, in effect, “baked into” the channel estimate.</p>
<h3 id="creating-the-estimator">Creating the estimator <a href="#creating-the-estimator" class="section">#</a></h3>
<p>To find the size of the window, we ask whoever designed our channel estimator / trellis detector what’s the biggest channel they can handle, which as usual, we call <span class="math inline">\(L\)</span>. Here, we’ve decided <span class="math inline">\(L=8\)</span>. Mathematically, we’re taking the absolute value of the first convolution, and convolving that with an <span class="math inline">\(L\)</span>-long vector <span class="math inline">\([1,\cdots,1]\)</span>:</p>
<div class="sourceCode" id="cb4"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb4-1"><a href="#cb4-1" aria-hidden="true" tabindex="-1"></a><span class="va">first_convolution</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">signal</span><span class="op">,</span> <span class="va">conj</span>(<span class="va">flip</span>(<span class="va">template</span>)))<span class="op">;</span></span>
<span id="cb4-2"><a href="#cb4-2" aria-hidden="true" tabindex="-1"></a><span class="va">second_convolution</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">abs</span>(<span class="va">first_convolution</span>)<span class="op">,</span> <span class="va">ones</span>(<span class="fl">1</span><span class="op">,</span><span class="fl">8</span>))<span class="op">;</span></span>
<span id="cb4-3"><a href="#cb4-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb4-4"><a href="#cb4-4" aria-hidden="true" tabindex="-1"></a>[<span class="va">val</span><span class="op">,</span> <span class="va">uncorrected_offset</span>] <span class="op">=</span> <span class="va">max</span>(<span class="va">second_convolution</span>)<span class="op">;</span></span></code></pre></div>
<p>Note the <strong><code>abs</code></strong><code>(first_convolution)</code>. This is <em>critical</em>, and omitting it caused me a lot of sadness and confusion. We want the total <em>energy</em> in that window, and if there’s cancellation across channel coefficients/taps then we’re…not getting a total energy.</p>
<p>If we change our code:</p>
<div class="sourceCode" id="cb5"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb5-1"><a href="#cb5-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-2"><a href="#cb5-2" aria-hidden="true" tabindex="-1"></a><span class="va">average_second_convolution</span> <span class="op">=</span> <span class="va">zeros</span>(<span class="fl">326</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span></span>
<span id="cb5-3"><a href="#cb5-3" aria-hidden="true" tabindex="-1"></a><span class="co">% ...</span></span>
<span id="cb5-4"><a href="#cb5-4" aria-hidden="true" tabindex="-1"></a>    <span class="va">second_convolution</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">abs</span>(<span class="va">first_convolution</span>)<span class="op">,</span> <span class="va">ones</span>(<span class="fl">1</span><span class="op">,</span><span class="fl">8</span>))<span class="op">;</span></span>
<span id="cb5-5"><a href="#cb5-5" aria-hidden="true" tabindex="-1"></a>    <span class="va">average_second_convolution</span> <span class="op">=</span> <span class="va">average_second_convolution</span> <span class="op">+</span> <span class="va">second_convolution</span><span class="op">;</span></span>
<span id="cb5-6"><a href="#cb5-6" aria-hidden="true" tabindex="-1"></a><span class="co">% ...</span></span>
<span id="cb5-7"><a href="#cb5-7" aria-hidden="true" tabindex="-1"></a><span class="va">plot</span>(<span class="va">abs</span>(<span class="va">average_second_convolution</span>))<span class="op">;</span></span>
<span id="cb5-8"><a href="#cb5-8" aria-hidden="true" tabindex="-1"></a><span class="va">title</span>(<span class="st">&quot;average second convolution output&quot;</span>)<span class="op">;</span></span></code></pre></div>
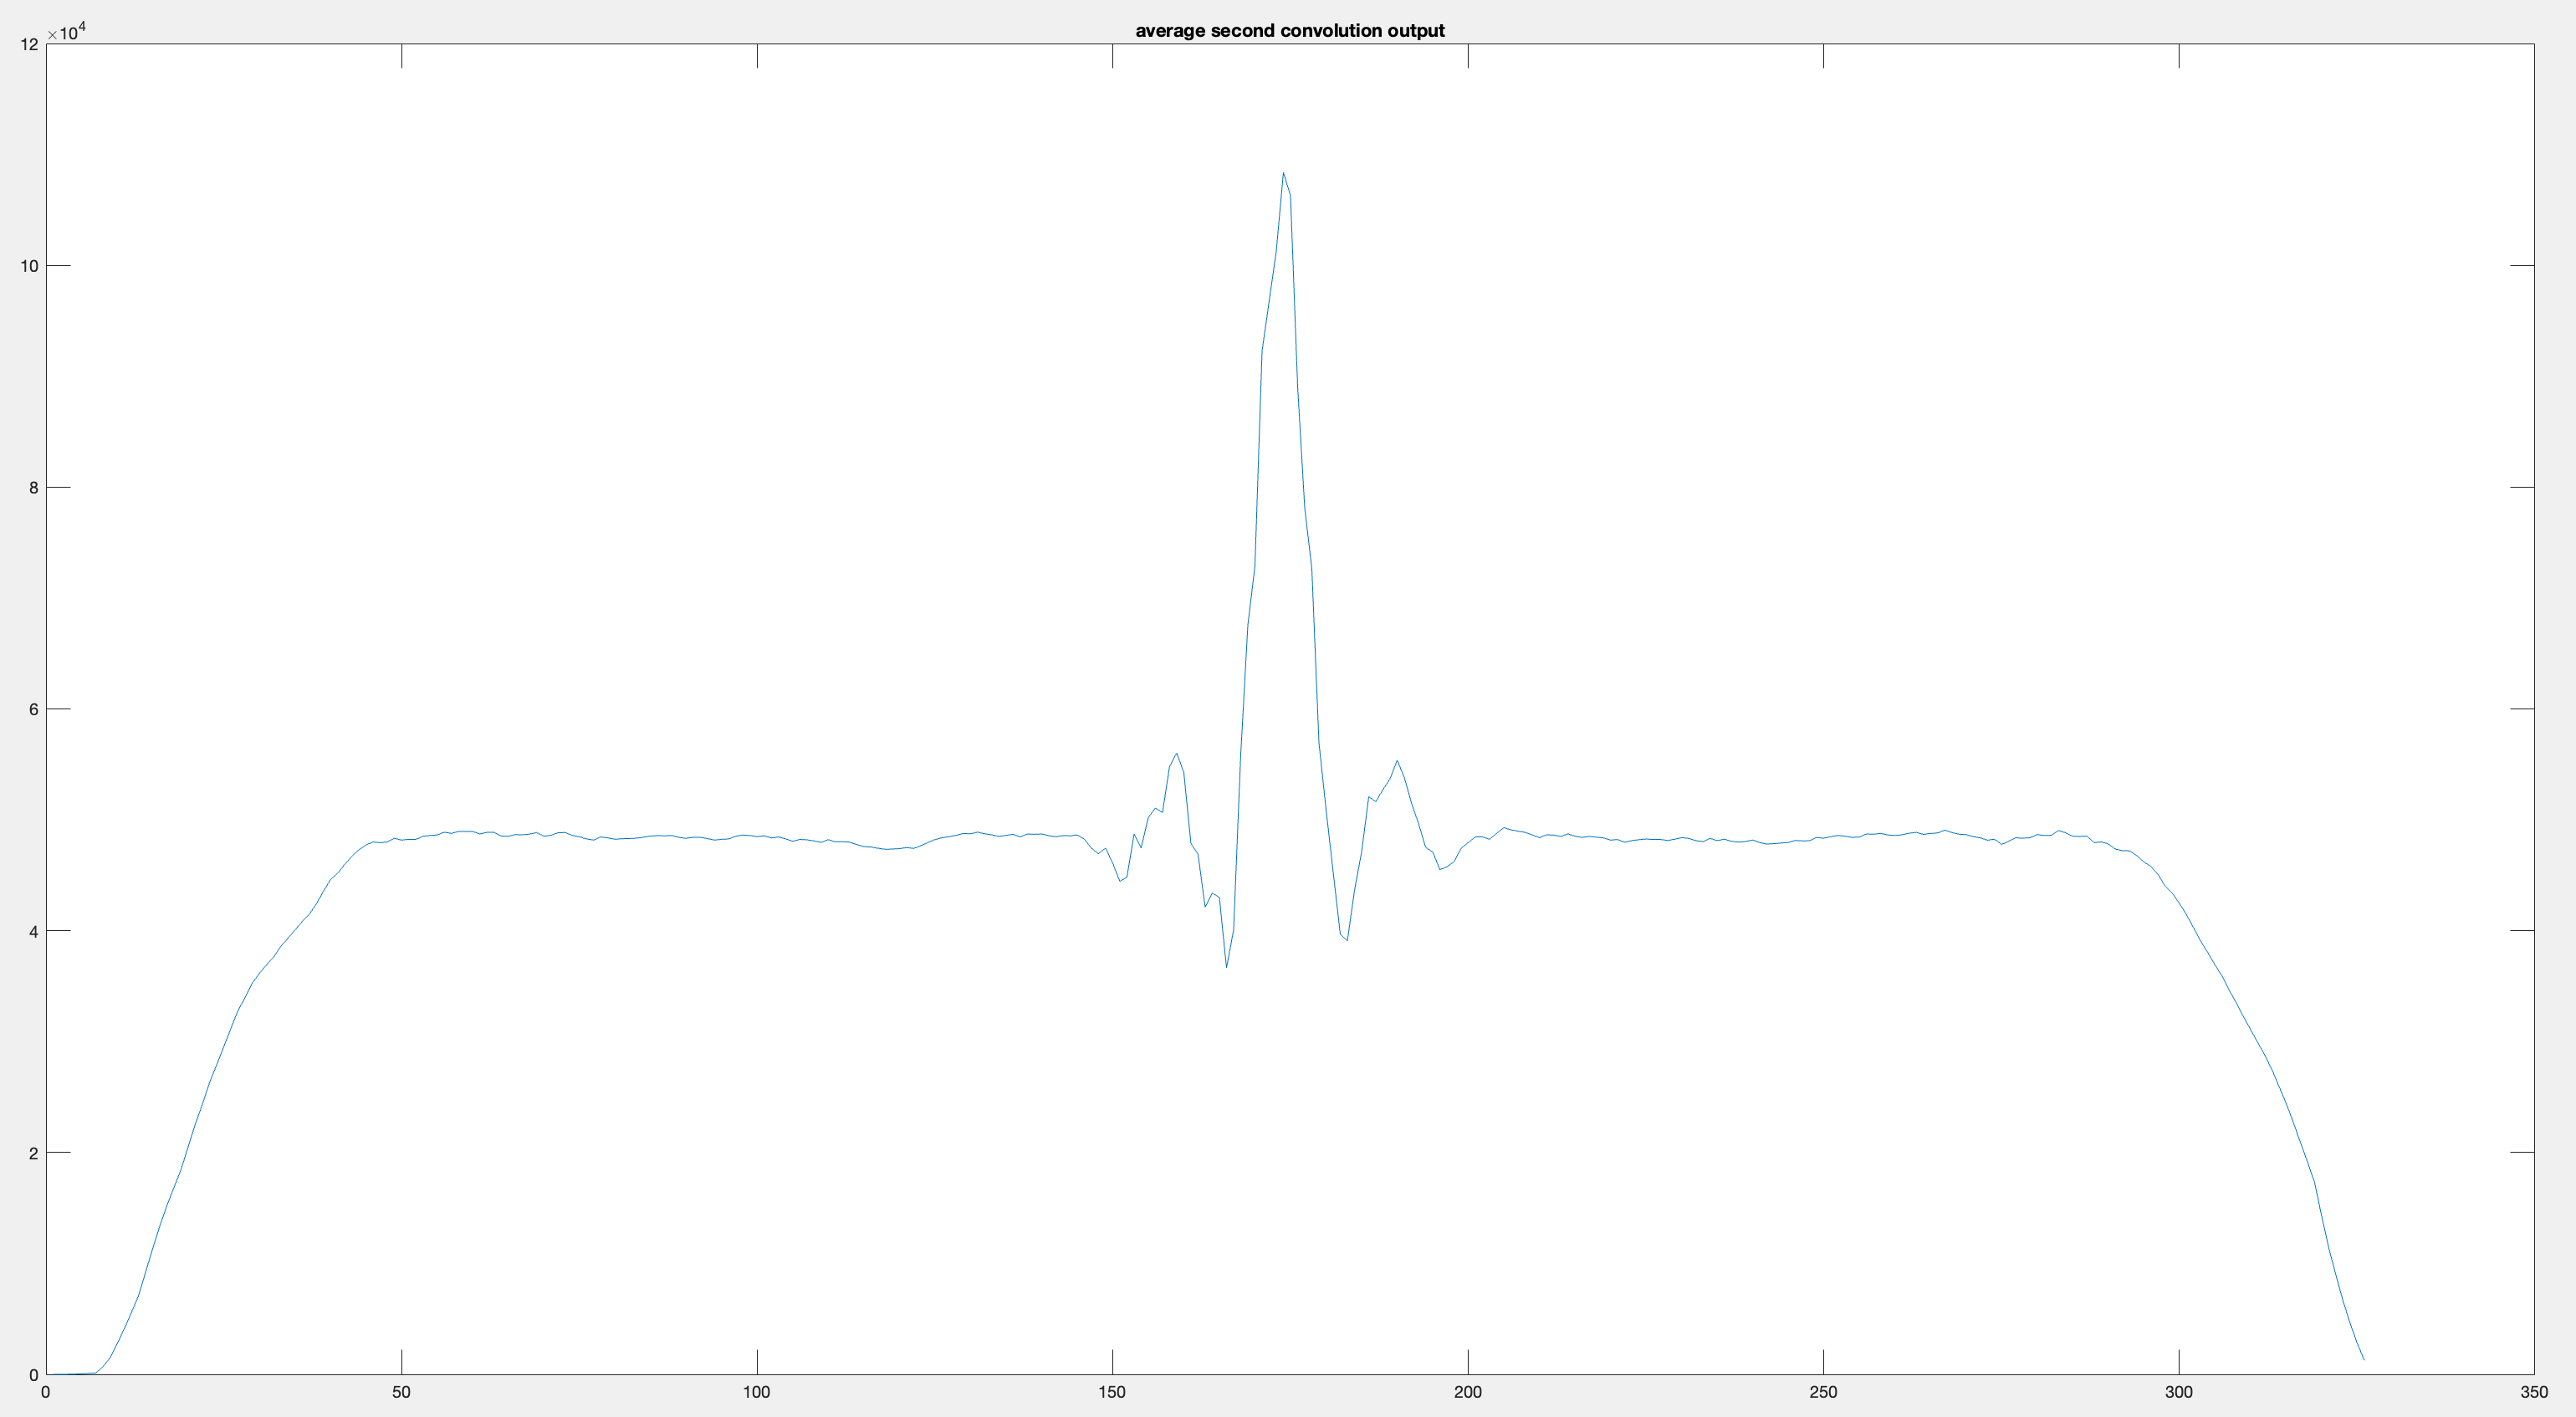
<p>We get something that looks remarkably better. While a single run looks like this:</p>
<figure>
<img src="../images/time-sync-part-3/single_run_second_convolution.png" alt="Single run of the second convolution output; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/single_run_second_convolution.png">Single run of the second convolution output</a>; click for full size</figcaption>
</figure>
<p>This looks pretty bad sidelobe-wise, but sidelobes don’t doom us.</p>
<p>When we average over multiple runs (which effectively “averages out” the sidelobes), we see that our new correlation erased the structure in our correlation peak. Note that it’s <strong>not</strong> the averaging over multiple runs that’s done this!</p>
<figure>
<img src="../images/time-sync-part-3/really_good.png" alt="Average second convolution output; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/really_good.png">Average second convolution output</a>; click for full size</figcaption>
</figure>
<p>Sometimes a little structure does show up, but it’s not nearly as bad as before:</p>
<figure>
<img src="../images/time-sync-part-3/not_quite_perfect.png" alt="Average second convolution output; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/not_quite_perfect.png">Average second convolution output</a>; click for full size</figcaption>
</figure>
<p>We try it with a different channel (<code>gsmTUx12c1</code>) to make sure that it’s not a peculiarity of the channel model we had been using:</p>
<figure>
<img src="../images/time-sync-part-3/works_with_TU_also.png" alt="Average second convolution output with gsmTUx12c1; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/works_with_TU_also.png">Average second convolution output with gsmTUx12c1</a>; click for full size</figcaption>
</figure>
<h2 id="validation">Validation <a href="#validation" class="section">#</a></h2>
<p>Convolving once against the training sequence, calculating the energy, then convolving again with a largest-supported-channel-length vector of ones certainly generates extremely aesthetic plots, but we’ve yet to make sure that it actually matches up against the ground truth.</p>
<p>Without any subtlety, we simply generate a loss vector (how much least-square loss for each offset) for each run, sum them all up, and plot them alongside the second convolution output:</p>
<pre><code>average_ts_losses = zeros(1,264);

% ...
    ts_losses = least_squares_offset(awgned, training_sequence);
    average_ts_losses = average_ts_losses + ts_losses;
% ...

average_second_convolution = average_second_convolution / norm(average_second_convolution);
average_ts_losses = average_ts_losses / norm(average_ts_losses);

figure;
plot(abs(average_second_convolution));
hold on;
plot(average_ts_losses);
title(&quot;peak = second convolution, dip = least squares loss&quot;);</code></pre>
<p>And the comparison is <em>incredibly</em> encouraging. Note that these are averages, so the sidelobes from the data get averaged away. We see that the convolution-based estimator has more sidelobes, but the main peak is sharp:</p>
<figure>
<img src="../images/time-sync-part-3/comparison_1.png" alt="AVERAGE convolution estimator vs. least squares loss; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/comparison_1.png"><strong>AVERAGE</strong> convolution estimator vs. least squares loss</a>; click for full size</figcaption>
</figure>
<p>To show it’s not a fluke, we show a comparison for a single run:</p>
<figure>
<img src="../images/time-sync-part-3/single_run_comparison.png" alt="Single run: convolution estimator vs. least squares loss; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/single_run_comparison.png">Single run: convolution estimator vs. least squares loss</a>; click for full size</figcaption>
</figure>
<p>There’s still the eternal question of the indices, which decidedly do not line up. We investigate:</p>
<div class="sourceCode" id="cb7"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb7-1"><a href="#cb7-1" aria-hidden="true" tabindex="-1"></a><span class="va">correlation_indices</span> <span class="op">=</span> []<span class="op">;</span></span>
<span id="cb7-2"><a href="#cb7-2" aria-hidden="true" tabindex="-1"></a><span class="va">least_squares_indices</span> <span class="op">=</span> []<span class="op">;</span></span>
<span id="cb7-3"><a href="#cb7-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb7-4"><a href="#cb7-4" aria-hidden="true" tabindex="-1"></a><span class="co">% ...</span></span>
<span id="cb7-5"><a href="#cb7-5" aria-hidden="true" tabindex="-1"></a>    [<span class="va">val</span><span class="op">,</span> <span class="va">correlation_index</span>] <span class="op">=</span> <span class="va">max</span>(<span class="va">second_convolution</span>)<span class="op">;</span></span>
<span id="cb7-6"><a href="#cb7-6" aria-hidden="true" tabindex="-1"></a>    <span class="va">correlation_indices</span> <span class="op">=</span> [<span class="va">correlation_indices</span> <span class="va">correlation_index</span>]<span class="op">;</span></span>
<span id="cb7-7"><a href="#cb7-7" aria-hidden="true" tabindex="-1"></a>    [<span class="va">val</span><span class="op">,</span> <span class="va">least_squares_index</span>] <span class="op">=</span> <span class="va">min</span>(<span class="va">ts_losses</span>)<span class="op">;</span></span>
<span id="cb7-8"><a href="#cb7-8" aria-hidden="true" tabindex="-1"></a>    <span class="va">least_squares_indices</span> <span class="op">=</span> [<span class="va">least_squares_indices</span> <span class="va">least_squares_index</span>]<span class="op">;</span></span>
<span id="cb7-9"><a href="#cb7-9" aria-hidden="true" tabindex="-1"></a><span class="co">% ...</span></span></code></pre></div>
<p>And in the command window we run:</p>
<div class="sourceCode" id="cb8"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb8-1"><a href="#cb8-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">sum</span>(<span class="va">least_squares_indices</span><span class="op">-</span><span class="va">correlation_indices</span>)<span class="op">/</span><span class="va">length</span>(<span class="va">least_squares_indices</span>)</span>
<span id="cb8-2"><a href="#cb8-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb8-3"><a href="#cb8-3" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb8-4"><a href="#cb8-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb8-5"><a href="#cb8-5" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">29.9922</span></span>
<span id="cb8-6"><a href="#cb8-6" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb8-7"><a href="#cb8-7" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> </span></code></pre></div>
<p>The almost-integral offset does seem to be a fluke, but we run it a few more times and see it’s not – it seems to vary a little bit:</p>
<div class="sourceCode" id="cb9"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb9-1"><a href="#cb9-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-2"><a href="#cb9-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">clear</span><span class="op">;</span> <span class="va">average_convolution_output</span></span>
<span id="cb9-3"><a href="#cb9-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-4"><a href="#cb9-4" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb9-5"><a href="#cb9-5" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-6"><a href="#cb9-6" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">33.7109</span></span>
<span id="cb9-7"><a href="#cb9-7" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-8"><a href="#cb9-8" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">clear</span><span class="op">;</span> <span class="va">average_convolution_output</span></span>
<span id="cb9-9"><a href="#cb9-9" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-10"><a href="#cb9-10" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb9-11"><a href="#cb9-11" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-12"><a href="#cb9-12" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">29.7305</span></span>
<span id="cb9-13"><a href="#cb9-13" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-14"><a href="#cb9-14" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">clear</span><span class="op">;</span> <span class="va">average_convolution_output</span></span>
<span id="cb9-15"><a href="#cb9-15" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-16"><a href="#cb9-16" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb9-17"><a href="#cb9-17" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-18"><a href="#cb9-18" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">27.7578</span></span>
<span id="cb9-19"><a href="#cb9-19" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-20"><a href="#cb9-20" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">clear</span><span class="op">;</span> <span class="va">average_convolution_output</span></span>
<span id="cb9-21"><a href="#cb9-21" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-22"><a href="#cb9-22" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb9-23"><a href="#cb9-23" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-24"><a href="#cb9-24" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">30.9141</span></span>
<span id="cb9-25"><a href="#cb9-25" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb9-26"><a href="#cb9-26" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> </span></code></pre></div>
<p>The <span class="math inline">\(\sim30\)</span>-ness was a bit concerning, since the GSM training sequence is <span class="math inline">\(26\)</span> syms long and our channel/window is <span class="math inline">\(8\)</span> long and there’s no obvious and morally-upstanding way to get <span class="math inline">\(\sim30\)</span> out of that, but looking at our source code we see that we indeed did choose a <span class="math inline">\(32\)</span>-long training sequence (the <code>%</code> is the comment character in MATLAB):</p>
<div class="sourceCode" id="cb10"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb10-1"><a href="#cb10-1" aria-hidden="true" tabindex="-1"></a><span class="va">training_sequence</span> <span class="op">=</span> <span class="va">randi</span>([<span class="fl">0</span> <span class="fl">1</span>]<span class="op">,</span> <span class="fl">32</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span> <span class="co">%[0,1,0,0,0,1,1,1,1,0,1,1,0,1,0,0,0,1,0,0,0,1,1,1,1,0]&#39;;</span></span></code></pre></div>
<h2 id="residual-processing">Residual processing <a href="#residual-processing" class="section">#</a></h2>
<p>We seem to have a little error between the least-squares timing estimator (which we’re using as a reference) and our two-correlation-based estimator, which is a bit concerning. We try to figure out what’s going on, and we start off simple:</p>
<div class="sourceCode" id="cb11"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb11-1"><a href="#cb11-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">min</span>(<span class="va">least_squares_indices</span>)<span class="op">-</span><span class="va">max</span>(<span class="va">least_squares_indices</span>)</span>
<span id="cb11-2"><a href="#cb11-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-3"><a href="#cb11-3" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb11-4"><a href="#cb11-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-5"><a href="#cb11-5" aria-hidden="true" tabindex="-1"></a>     <span class="fl">0</span></span>
<span id="cb11-6"><a href="#cb11-6" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-7"><a href="#cb11-7" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">least_squares_indices</span>(<span class="fl">1</span>)</span>
<span id="cb11-8"><a href="#cb11-8" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-9"><a href="#cb11-9" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb11-10"><a href="#cb11-10" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-11"><a href="#cb11-11" aria-hidden="true" tabindex="-1"></a>   <span class="fl">142</span></span>
<span id="cb11-12"><a href="#cb11-12" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-13"><a href="#cb11-13" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> </span></code></pre></div>
<p>We notice that the least-squares estimator always gives the same index (<span class="math inline">\(142\)</span>), so whatever is going on, it’s in the correlation-based estimator, and uh, there’s definitely something going on:</p>
<div class="sourceCode" id="cb12"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb12-1"><a href="#cb12-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">hold</span> <span class="va">on</span></span>
<span id="cb12-2"><a href="#cb12-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">least_squares_indices</span>)</span>
<span id="cb12-3"><a href="#cb12-3" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">correlation_indices</span>)</span></code></pre></div>
<figure>
<img src="../images/time-sync-part-3/index_distribution.png" alt="Estimator indices over 256 runs; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/index_distribution.png">Estimator indices over 256 runs</a>; click for full size</figcaption>
</figure>
<p>That outlier is what’s skewing the average! While our code didn’t save the raw data for each run (only the outputs of the estimators), it’s clear what happened: most of the time, this estimator doesn’t get tricked by the sidelobes, but when it does, it gets tricked <em>hard</em>.</p>
<p>We plot a histogram of the indices:</p>
<div class="sourceCode" id="cb13"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb13-1"><a href="#cb13-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">histogram</span>(<span class="va">correlation_indices</span><span class="op">,</span> <span class="ss">&#39;BinMethod&#39;</span><span class="op">,</span> <span class="ss">&#39;integers&#39;</span>)</span></code></pre></div>
<figure>
<img src="../images/time-sync-part-3/histogram.png" alt="Correlation estimator indices; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/histogram.png">Correlation estimator indices</a>; click for full size</figcaption>
</figure>
<p>The most common (by far) value is <span class="math inline">\(174\)</span>, which indeed is <span class="math inline">\(142+32\)</span>:</p>
<div class="sourceCode" id="cb14"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb14-1"><a href="#cb14-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-2"><a href="#cb14-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="fl">174</span><span class="op">-</span><span class="fl">32</span></span>
<span id="cb14-3"><a href="#cb14-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-4"><a href="#cb14-4" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb14-5"><a href="#cb14-5" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-6"><a href="#cb14-6" aria-hidden="true" tabindex="-1"></a>   <span class="fl">142</span></span>
<span id="cb14-7"><a href="#cb14-7" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-8"><a href="#cb14-8" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">least_squares_indices</span>(<span class="fl">1</span>) <span class="co">% remember least_squares_indices(n)=142 for all n</span></span>
<span id="cb14-9"><a href="#cb14-9" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-10"><a href="#cb14-10" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb14-11"><a href="#cb14-11" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-12"><a href="#cb14-12" aria-hidden="true" tabindex="-1"></a>   <span class="fl">142</span></span>
<span id="cb14-13"><a href="#cb14-13" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb14-14"><a href="#cb14-14" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> </span></code></pre></div>
<h2 id="noise">Noise <a href="#noise" class="section">#</a></h2>
<p><strong>We have not tested this estimator in the presence of noise</strong>. Not to sound like a excerpt from a statistical signal processing textbook, but it is essential to test how good your estimators perform in the presence of noise. Graphs with <span class="math inline">\(E_{b}/N_{0}\)</span> on the x-axis are, strictly speaking, optional, but they <em>do</em> look very nice.</p>
<p>We won’t do a full examination of how these estimators work in noise, but we’ll take a quick look.</p>
<p>I ran the same code, except modified with <code>awgned = awgn(received,4);</code>. This adds AWGN such that the signal to noise ratio is <span class="math inline">\(4\text{dB}\)</span>. From cursory inspection of the plot below, we see that both estimators (the correlation-based one more so than the LS one) are more likely to be tricked by sidelobes in higher-noise conditions. Even if we ignore the sidelobe-caused indices, we see some variation/wobble and not a straight line. This represents error which won’t be eliminated by running the estimators on a smaller section of the signal.</p>
<figure>
<img src="../images/time-sync-part-3/noise.png" alt="Indices of the two estimators in 4\text{dB} SNR; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/noise.png">Indices of the two estimators in <span class="math inline">\(4\text{dB}\)</span> SNR</a>; click for full size</figcaption>
</figure>
<p>Here’s the histograms for the two indices. We definitely see that the huge errors are from sidelobes and not from the correlation peak spreading out because of noise:</p>
<figure>
<img src="../images/time-sync-part-3/ls_noise_hist.png" alt="Histogram for least-squares timing estimator in 4\text{dB} SNR; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/ls_noise_hist.png">Histogram for least-squares timing estimator in <span class="math inline">\(4\text{dB}\)</span> SNR</a>; click for full size</figcaption>
</figure>
<figure>
<img src="../images/time-sync-part-3/corr_noise_hist.png" alt="Histogram for correlation-based timing estimator in 4\text{dB} SNR; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/corr_noise_hist.png">Histogram for correlation-based timing estimator in <span class="math inline">\(4\text{dB}\)</span> SNR</a>; click for full size</figcaption>
</figure>
<p>If we zoom in to eliminate the sidelobes, we see that the correlation peaks indeed spread out, but approximately the same amount for both estimators:</p>
<figure>
<img src="../images/time-sync-part-3/ls_noise_hist_trimmed.png" alt="Histogram for least-squares timing estimator in 4\text{dB} SNR, sidelobes removed; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/ls_noise_hist_trimmed.png">Histogram for least-squares timing estimator in <span class="math inline">\(4\text{dB}\)</span> SNR, sidelobes removed</a>; click for full size</figcaption>
</figure>
<figure>
<img src="../images/time-sync-part-3/corr_noise_hist_trimmed.png" alt="Histogram for correlation-based timing estimator in 4\text{dB} SNR, sidelobes removed; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-3/corr_noise_hist_trimmed.png">Histogram for correlation-based timing estimator in <span class="math inline">\(4\text{dB}\)</span> SNR, sidelobes removed</a>; click for full size</figcaption>
</figure>
<h2 id="conclusion">Conclusion <a href="#conclusion" class="section">#</a></h2>
<p>The least-squares timing estimator we had been using as a reference is excellent, but it’s <em>incredibly</em> compute-intensive. Here, we derived and tested an alternate correlation-based estimator which only requires a convolution, a squaring operation, and a second convolution – and the second convolution doesn’t even require any multiplies!</p>
<p>To reduce computational effort and avoid getting tricked by sidelobes, if at all practical, we should use a priori information (a fancy way of saying “when we started receiving it” and/or “when we expect to receive it” alongside “where the training sequence lives in the signal”) about the signal to slice a section of the signal and only run the estimator on that section.</p>
<p>While <a href="time-sync-part-2.html#the-dark-forest-downstream">previously</a> we had wanted to concoct a measure for the “goodness” of a timing estimator that’d make sense for this context (trellis-based detection in an ISI channel, we’ll be looking at Viterbi itself in the next few posts.</p>
<p>Why try and fake it when we’ll learn and use the real thing?</p>]]></summary>
</entry>
<entry>
    <title>GSM receiver blocks: timing synchronization (part 2: correlation edition)</title>
    <link href="https://softminus.org/posts/time-sync-part-2.html" />
    <id>https://softminus.org/posts/time-sync-part-2.html</id>
    <published>2023-04-18</published>
    <updated>2023-04-18T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-timing-synchronization-part-2-correlation-edition">GSM receiver blocks: timing synchronization (part 2: correlation edition)</h1>
<p>In the last <a href="time-sync-part-1.html">post</a>, we ran a least-squares on <em>every possible time offset</em>, calculated the loss, and declared the optimal timing offset to be the one with the lowest loss. This approach is incredibly inefficient, but critically, we know it handles the dispersive channel correctly. In this and the next post, we’ll use it as a gold standard to validate a more efficient approach.</p>
<h2 id="cut-to-the-chase-its-a-correlation-right">cut to the chase: it’s a correlation, right? <a href="#cut-to-the-chase-its-a-correlation-right" class="section">#</a></h2>
<p>Yep. It’s a correlation. Our intuition indeed tells us to correlate the received signal against the modulated training sequence, and look for the correlation peak. If we <em>didn’t</em> have a dispersive channel, the story ends here.</p>
<p>The dispersive channel makes things a bit more subtle! Remember, what’s <em>received</em> is not going to look like what’s transmitted, so we have to be careful in our analysis. When we ran the least-squares, we were careful to run it only on the slice of <em>received</em> training sequence that was <em>unaffected</em> by unknown data. It’s possible we might have to do something similar here – use a subset of the training sequence, and not the whole thing.</p>
<h2 id="index-reckoning">index reckoning <a href="#index-reckoning" class="section">#</a></h2>
<p>If the channel’s delay spread is <span class="math inline">\(L\)</span> symbol intervals long, we have a couple reasonable choices for the correlation “template”:</p>
<ul>
<li>the full training sequence</li>
<li>the training sequence with <span class="math inline">\(L\)</span> symbols removed from the beginning</li>
<li>the training sequence with <span class="math inline">\(L\)</span> symbols removed from the end</li>
<li>the training sequence with <span class="math inline">\(L\)</span> symbols removed from both ends</li>
</ul>
<p>I learned enough SAGE to calculate the symbolic expressions for the first two cases (with a channel length of 4, a training sequence length of 10, and 10 symbols before and after the training sequence) to see if there was some insight attainable by looking at the output:</p>
<div class="sourceCode" id="cb1"><pre class="sourceCode python"><code class="sourceCode python"><span id="cb1-1"><a href="#cb1-1" aria-hidden="true" tabindex="-1"></a>sage: prepend_data <span class="op">=</span> <span class="bu">list</span>(var(<span class="st">&#39;XXXXXXXXXX_</span><span class="sc">%d</span><span class="st">&#39;</span> <span class="op">%</span> (i)) <span class="cf">for</span> i <span class="kw">in</span> <span class="bu">range</span>(<span class="dv">10</span>))</span>
<span id="cb1-2"><a href="#cb1-2" aria-hidden="true" tabindex="-1"></a>sage: TS <span class="op">=</span> <span class="bu">list</span>(var(<span class="st">&#39;TS_</span><span class="sc">%d</span><span class="st">&#39;</span> <span class="op">%</span> (i<span class="op">+</span><span class="dv">10</span>)) <span class="cf">for</span> i <span class="kw">in</span> <span class="bu">range</span>(<span class="dv">10</span>))</span>
<span id="cb1-3"><a href="#cb1-3" aria-hidden="true" tabindex="-1"></a>sage: append_data <span class="op">=</span> <span class="bu">list</span>(var(<span class="st">&#39;XXXXXXXXXX_</span><span class="sc">%d</span><span class="st">&#39;</span> <span class="op">%</span> (i<span class="op">+</span><span class="dv">20</span>)) <span class="cf">for</span> i <span class="kw">in</span> <span class="bu">range</span>(<span class="dv">10</span>))</span>
<span id="cb1-4"><a href="#cb1-4" aria-hidden="true" tabindex="-1"></a>sage: burst <span class="op">=</span> prepend_data <span class="op">+</span> TS <span class="op">+</span> append_data</span>
<span id="cb1-5"><a href="#cb1-5" aria-hidden="true" tabindex="-1"></a>sage: chan <span class="op">=</span> <span class="bu">list</span>(var(<span class="st">&#39;CHAN_</span><span class="sc">%d</span><span class="st">&#39;</span> <span class="op">%</span> (i<span class="op">+</span><span class="dv">1</span>)) <span class="cf">for</span> i <span class="kw">in</span> <span class="bu">range</span>(<span class="dv">4</span>))</span>
<span id="cb1-6"><a href="#cb1-6" aria-hidden="true" tabindex="-1"></a>sage: received <span class="op">=</span> convolution(burst, chan)</span>
<span id="cb1-7"><a href="#cb1-7" aria-hidden="true" tabindex="-1"></a>sage: convolution(received, <span class="bu">list</span>(<span class="bu">reversed</span>(TS)))</span>
<span id="cb1-8"><a href="#cb1-8" aria-hidden="true" tabindex="-1"></a>sage: convolution(received, <span class="bu">list</span>(<span class="bu">reversed</span>(TS[<span class="dv">4</span>:<span class="dv">10</span>])))</span></code></pre></div>
<p>We can see that for instance, the correlation has zero outputs unaffected by unknown data (run it yourself if you want to check, i’m not including the output here), but correlating with <code>TS[4:10]</code> – removing the first 4 symbols from the training sequence – has two outputs unaffected by unknown data:</p>
<div class="sourceCode" id="cb2"><pre class="sourceCode python"><code class="sourceCode python"><span id="cb2-1"><a href="#cb2-1" aria-hidden="true" tabindex="-1"></a>(CHAN_4<span class="op">*</span>TS_10 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_11 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_12 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_13)<span class="op">*</span>TS_14 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_11 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_12 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_13 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_14)<span class="op">*</span>TS_15 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_12 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_13 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_14 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_15)<span class="op">*</span>TS_16 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_13 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_14 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_15 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_16)<span class="op">*</span>TS_17 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_14 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_15 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_16 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_17)<span class="op">*</span>TS_18 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_15 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_16 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_17 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_18)<span class="op">*</span>TS_19,</span>
<span id="cb2-2"><a href="#cb2-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-3"><a href="#cb2-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-4"><a href="#cb2-4" aria-hidden="true" tabindex="-1"></a>(CHAN_4<span class="op">*</span>TS_11 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_12 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_13 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_14)<span class="op">*</span>TS_14 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_12 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_13 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_14 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_15)<span class="op">*</span>TS_15 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_13 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_14 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_15 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_16)<span class="op">*</span>TS_16 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_14 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_15 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_16 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_17)<span class="op">*</span>TS_17 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_15 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_16 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_17 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_18)<span class="op">*</span>TS_18 <span class="op">+</span> (CHAN_4<span class="op">*</span>TS_16 <span class="op">+</span> CHAN_3<span class="op">*</span>TS_17 <span class="op">+</span> CHAN_2<span class="op">*</span>TS_18 <span class="op">+</span> CHAN_1<span class="op">*</span>TS_19)<span class="op">*</span>TS_19</span></code></pre></div>
<p>This is a curious phenomenon: chopping off symbols from the training sequence – causing the correlation template to have <strong>fewer</strong> symbols – causes <em>more</em> output values that don’t depend on unknown data. This makes total sense, since if you have a tiny little template then it’ll have more “alignments” in the un-tainted section of the received signal.</p>
<p>Unfortunately, this goes in the opposite direction of traditional wisdom about correlation: use the <em>largest</em> template you can. So we’re left to wonder, is there a “happy medium” between too much contribution from unknown data, and too few symbols in the correlation template?</p>
<p>There is a saving grace: the standard assumption (and in fact, <strong>standard<a href="#fn1" class="footnote-ref" id="fnref1" role="doc-noteref"><sup>1</sup></a> practice!</strong>) is that modulators <em>are fed data sufficiently<a href="#fn2" class="footnote-ref" id="fnref2" role="doc-noteref"><sup>2</sup></a> indistinguishable from random</em> – so maybe “contribution from unknown data” is not as bad as it seems.</p>
<p>There’s only so much thinking about it can do. It seems like we’re going to have to figure out some ways to judge our estimators, and do some simulations.</p>
<h2 id="estimator-quality">estimator quality <a href="#estimator-quality" class="section">#</a></h2>
<p>Let’s think of some criteria we can use to evaluate our estimators:</p>
<h3 id="error">Error <a href="#error" class="section">#</a></h3>
<p>The estimator gives us an estimated timing offset, and the closer it is to the “true” (determined by least-squares offset sweep) timing offset, the happier we are.</p>
<p>For each trial, we will compute an estimated timing offset, a true timing offset, and an error – and we can accumulate the error over multiple trials (for instance, by calculating a mean squared error). We can then generate a graph of how the error changes as a function of signal-to-noise ratios, since it’s possible that noise affects each estimator differently.</p>
<h3 id="what-about-the-bits">what about the bits? <a href="#what-about-the-bits" class="section">#</a></h3>
<p>The purpose of most<a href="#fn3" class="footnote-ref" id="fnref3" role="doc-noteref"><sup>3</sup></a> receivers is to ingest RF (or baseband) and output the best possible estimate of the bits the transmitter ingested, and it’s unclear how these timing errors affect downstream signal processing.</p>
<p>If this were a receiver for a nondispersive channel, we’d make the argument that symbol timing error straightforwardly translates into symbol decisions happening at the wrong times. This leads to the RRC condition being violated causing symbol errors from ISI, and presumably more influence from noise, since we’re not capturing the signal at its peak. We could look at the pulse shape and filter responses and try and eyeball how much timing errors affects bit error rate.</p>
<p>However, we fully intend to tackle the nastiest of dispersive channels, and therefore what lies downstream of the synchronization blocks is a channel estimator and a trellis detector. Timing errors will affect both of these in more complicated ways.</p>
<p>We can try and handwave and say that small enough timing errors will be compensated for by the channel estimator and so we shouldn’t worry much, but I am interested in trying to see if we can find a somewhat reasonable way to quantify timing errors.</p>
<h3 id="the-dark-forest-downstream">the dark forest downstream <a href="#the-dark-forest-downstream" class="section">#</a></h3>
<p>We haven’t got to trellis detection yet, and there are lots of subtleties and design choices which I don’t yet<a href="#fn4" class="footnote-ref" id="fnref4" role="doc-noteref"><sup>4</sup></a> understand, but from what I know, the high level operating principle of trellis detection looks like this:</p>
<ul>
<li>we do not try and find a sufficiently-magical<a href="#fn5" class="footnote-ref" id="fnref5" role="doc-noteref"><sup>5</sup></a> filter that lets us “undo” the effect of the channel and feed it into a normal decision device</li>
<li>instead, we determine which symbols were sent by seeing how well the received signal matches <strong>what we would expect to receive</strong> for various transmitted symbol sequences</li>
<li>we do this with a local modulator<a href="#fn6" class="footnote-ref" id="fnref6" role="doc-noteref"><sup>6</sup></a> that generates a “template” transmitted signal <strong>before the channel</strong>, for any given symbol sequence</li>
<li>the channel estimator told us what the channel looks like, so we can convolve the “template” signal against the channel to see what we’d expect <strong>to have received</strong> – if it the transmitter had sent that sequence of symbols</li>
<li>we choose the sequence of symbols that matches best</li>
</ul>
<p>The error in the demodulation process is probably going to be vaguely of the form (with <span class="math inline">\(\ast\)</span> convolution):</p>
<p><span class="math display">\[(\text{hypothetical transmitted signal}) \ast (\text{estimated channel}) - (\text{actual received signal})\]</span></p>
<p>Morally we should want to minimize this error, and we can compare how good our timing estimator is by comparing it to an “ideal” timing estimator, with something that looks like this:</p>
<ol type="1">
<li>Run the incredibly slow least-squares estimator over all possible offsets (ok we can cheat and cue it to where we know the training sequence lives), obtain an estimated channel with the lowest possible loss.</li>
<li>Calculate the magnitude of this over the <em>whole signal</em>: <span class="math display">\[(\text{original transmitted signal}) \ast (\text{estimated channel with best offset}) - (\text{actual received signal})\]</span></li>
<li>Run the timing estimator, obtain a timing offset</li>
<li>Run a least-squares at the estimated timing offset, obtain an estimated channel</li>
<li>Calculate the magnitude of <span class="math display">\[(\text{original transmitted signal}) \ast (\text{estimated channel}) - (\text{actual received signal})\]</span></li>
<li>The error of the timing estimator is the difference between the two magnitudes</li>
</ol>
<p>I haven’t written code for this yet! But it seems reasonable?</p>
<h3 id="shape-of-the-true-correlation-peak">Shape of the true correlation peak <a href="#shape-of-the-true-correlation-peak" class="section">#</a></h3>
<p>Is it narrow/wide? are there multiple sub-peaks? If there’s a single narrow peak (like when we slid the least-squares along the signal), then everything is happy, if the peak has multiple sub-peaks or is wider then we need to be more careful about what’s going on, and figure out how to go from a vector of correlation outputs to a single timing offset.</p>
<h3 id="sidelobe-levels">Sidelobe levels <a href="#sidelobe-levels" class="section">#</a></h3>
<p>How high are the other peaks? If they’re high, the likelihood of the estimator choosing the wrong peak increases. To be clear, it’s often reasonable to accept higher sidelobe levels as a tradeoff for a narrower true peak / less errors, but we should be sure that our timing detector won’t accidentally lock on the wrong peak. Common methods of doing this would look like “having a local clock telling us approximately when we’re expecting to receive a burst” (like actual GSM receivers do) or an energy detector that tells us when a burst is starting.</p>
<h2 id="next-steps">next steps <a href="#next-steps" class="section">#</a></h2>
<p>I’m going to write some code to implement a correlation-based timing estimator (parametrizable with how much of the training sequence we’re using as the “template”), along with code to test it against the “ideal” timing estimator.</p>
<p>And most critically, there will be plenty of graphs – of correlation peaks, sidelobes, and most critically, graphs with <span class="math inline">\(E_{b}/N_{0}\)</span> on the x-axis!</p>
<section id="footnotes" class="footnotes footnotes-end-of-document" role="doc-endnotes">
<hr />
<ol>
<li id="fn1"><p>If the transmitted data is trivially distinguishable from random, then the transmitter pays <a href="https://en.wikipedia.org/wiki/Shannon–Hartley_theorem#Statement_of_the_theorem">Shannon</a> for energy (joules for feeding the power amplifier) and bandwidth (how many MHz we splatter our signal over) it doesn’t need. Motivating example without calculations: you are sending a hundred bits of data, with each of those bits generated by a random process with <span class="math inline">\(p(0) = 0.99\)</span> and <span class="math inline">\(p(1) = 0.01\)</span>. This bitstring is quite distinguishable from random (even a low-pass filter can distinguish it). We can transmit the <em>same information</em> in the bitstring with much less energy and bandwidth by compressing it: <a href="https://en.wikipedia.org/wiki/Run-length_encoding">Run-length</a> encoding converts it into a much smaller bitstring. The compressed bitstring will look a lot closer to random data (and if there’s still obvious ways it differs, then we can compress it further :).<a href="#fnref1" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn2"><p>Only a certain amount of statistical indistinguishability. We don’t need full statistical indistinguishability here (error correction schemes necessarily introduce deterministic relationships between transmitted bits) and certainly not something like cryptographic indistinguishability.<a href="#fnref2" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn3"><p>There are, in fact, receivers where accurate channel and/or timing estimation is the primary goal, and the data is of secondary importance. For instance, a GPS receiver designer is mighty concerned about getting timing <em>incredibly</em> right, and an air-defense radar designer is in the business of estimating a channel – where one of the taps might be an enemy aircraft.<a href="#fnref3" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn4"><p>Ungerboeck vs Forney observation models is the most salient but there’s lots of other stuff.<a href="#fnref4" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn5"><p>The “sufficiently-magical filter” approach in fact works for well-behaved dispersive channels! Zero-forcing equalization (use a filter that’s the inverse of the channel) can lead to suffering really quick since if you have a null in your channel, you’ll have infinite noise amplification in your equalizer, which is bad. MMSE equalization strikes a balance between noise enhancement and ISI suppression based on the SNR, but with GSM channels we can’t get away with only MMSE. There are ways to design prefilters without introducing much noise to transmogrify the channel’s impulse response to have more of its energy towards the beginning, and this can help make the trellis detector less compute-intensive. Channel-shortening will be a different story, and one we will look at in a later post!<a href="#fnref5" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn6"><p>Usually just lookup tables, sorry to ruin the mystique.<a href="#fnref6" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
</ol>
</section>]]></summary>
</entry>
<entry>
    <title>GSM receiver blocks: synchronization in time (part 1: the gold standard)</title>
    <link href="https://softminus.org/posts/time-sync-part-1.html" />
    <id>https://softminus.org/posts/time-sync-part-1.html</id>
    <published>2023-04-15</published>
    <updated>2023-04-15T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-synchronization-in-time-part-1-the-gold-standard">GSM receiver blocks: synchronization in time (part 1: the gold standard)</h1>
<p>So now that we have a good enough channel estimation mechanism, we need to figure out how to apply it to something that vaguely looks like a real-world problem. This means no hard coding indices! We’re not going to get away with that in the real world, unless maybe we’ve got a sync cable between the transmitter and receiver…</p>
<p>This means we need to handle a few things:</p>
<ul>
<li>Timing offsets: we don’t know exactly when the training sequence starts</li>
<li>Frequency offsets: local oscillators aren’t perfect</li>
<li>Phase offsets: transmitter and receiver local oscillators aren’t perfectly in phase</li>
</ul>
<h2 id="unfazed-about-the-phase">unfazed about the phase <a href="#unfazed-about-the-phase" class="section">#</a></h2>
<p>Phase offsets are the easiest to handle, since those get “baked into” the channel estimate. Adding a phase offset <span class="math inline">\(\phi_{1}\)</span> before the channel and a phase offset <span class="math inline">\(\phi_{2}\)</span> after the channel is equivalent to multiplying the channel estimate by a complex number with magnitude 1 and phase <span class="math inline">\(\phi_{1}+\phi_{2}\)</span>. With as <span class="math inline">\(\ast\)</span> convolution:</p>
<p><span class="math display">\[((\phi_{1} \cdot \text{transmitted}) \ast \text{channel})\cdot \phi_{2} = \text{transmitted} \ast ([\phi_{1} + \phi_{2}] \cdot \text{channel})\]</span></p>
<p>So we don’t even need to estimate a phase offset – the channel estimation handles it.</p>
<h3 id="but-what-about-the-phase-noise">but what about the phase noise? <a href="#but-what-about-the-phase-noise" class="section">#</a></h3>
<p>We handle phase noise with the time-honored tradition of ignoring it. Seriously though, I’m not sure how much it’s a problem. I think if we have a way to update the channel estimate as it’s being used to estimate bits (“per survivor processing”), we should be able to handle it, but I’m nowhere near that yet.</p>
<h2 id="well-fret-about-the-freqs-later">we’ll fret about the freqs later <a href="#well-fret-about-the-freqs-later" class="section">#</a></h2>
<p>A frequency offset will show up as a changing phase offset, and this won’t be handled by the channel estimation – unless, again, if we have a way to update the channel estimate as it’s being used in the actual demodulation.</p>
<p>Fortunately, we can estimate and compensate for frequency offsets earlier in the receiver and without needing the ability to estimate/update the channel estimate. In fact, we likely can get better results by compensating for frequency error with a mechanism designed for that purpose, that can operate over the entire received burst at once.</p>
<p>In actual GSM, coarse frequency synchronization is handled by the “frequency burst”; which carries no data but is designed to allow easy recovery of the carrier frequency at the mobile station. We’ll look at how to handle frequency offsets in a future post.</p>
<h2 id="time-for-timing">time for timing <a href="#time-for-timing" class="section">#</a></h2>
<p>Similarly, in actual GSM, coarse time synchronization is handled by the “synchronization burst” – which has an extra-long training sequence and information that identifies the base station.</p>
<p>We will look at how to handle time offsets in this post. The synchronization burst is a special case of a normal burst, and we can use the same methods to handle both.</p>
<h2 id="let-the-loss-be-your-guide">let the loss be your guide <a href="#let-the-loss-be-your-guide" class="section">#</a></h2>
<p>I spent some time guessing various indices for the least squares and eyeballing “how good” (with a channel generated by <code>conv(modulated, [1,2,3,4,5,4,3,2]);</code> ) the channel estimate was, which was kind of elucidating but not very principled.</p>
<p>Fortunately, we have a better tool: the least squares loss function.</p>
<p>We stop using the hardcoded channel <code>[1,2,3,4,5,4,3,2]</code> with its mysteriously-integer-valued coefficients, and use <code>interference_channel = stdchan("gsmEQx6", nominal_sample_rate, 0);</code> instead, and we add some AWGN: <code>awgned = awgn(received,10);</code>. Here’s the code:</p>
<h2 id="entire-example-code">entire example code <a href="#entire-example-code" class="section">#</a></h2>
<div class="sourceCode" id="cb1"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb1-1"><a href="#cb1-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-2"><a href="#cb1-2" aria-hidden="true" tabindex="-1"></a><span class="va">training_sequence</span> <span class="op">=</span> [<span class="fl">0</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">0</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">1</span><span class="op">,</span><span class="fl">0</span>]<span class="op">&#39;;</span></span>
<span id="cb1-3"><a href="#cb1-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-4"><a href="#cb1-4" aria-hidden="true" tabindex="-1"></a><span class="va">data</span> <span class="op">=</span> [<span class="va">randi</span>([<span class="fl">0</span> <span class="fl">1</span>]<span class="op">,</span><span class="fl">64</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span> <span class="va">training_sequence</span><span class="op">;</span> <span class="va">randi</span>([<span class="fl">0</span> <span class="fl">1</span>]<span class="op">,</span> <span class="fl">128</span><span class="op">,</span><span class="fl">1</span>)]<span class="op">;</span></span>
<span id="cb1-5"><a href="#cb1-5" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-6"><a href="#cb1-6" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-7"><a href="#cb1-7" aria-hidden="true" tabindex="-1"></a><span class="va">modulated</span> <span class="op">=</span> <span class="va">minimal_modulation</span>(<span class="va">data</span>)<span class="op">;</span></span>
<span id="cb1-8"><a href="#cb1-8" aria-hidden="true" tabindex="-1"></a><span class="va">nominal_sample_rate</span> <span class="op">=</span> <span class="fl">1e6</span> <span class="op">*</span> (<span class="fl">13</span><span class="op">/</span><span class="fl">48</span>)<span class="op">;</span></span>
<span id="cb1-9"><a href="#cb1-9" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-10"><a href="#cb1-10" aria-hidden="true" tabindex="-1"></a><span class="va">interference_channel</span> <span class="op">=</span> <span class="va">stdchan</span>(<span class="st">&quot;gsmEQx6&quot;</span><span class="op">,</span> <span class="va">nominal_sample_rate</span><span class="op">,</span> <span class="fl">0</span>)<span class="op">;</span></span>
<span id="cb1-11"><a href="#cb1-11" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-12"><a href="#cb1-12" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-13"><a href="#cb1-13" aria-hidden="true" tabindex="-1"></a><span class="co">%received =  conv(modulated, [1,2,3,4,5,4,3,2]);</span></span>
<span id="cb1-14"><a href="#cb1-14" aria-hidden="true" tabindex="-1"></a><span class="co">%received = conv(modulated, [1,1,0,0,0,0,0,0]); </span></span>
<span id="cb1-15"><a href="#cb1-15" aria-hidden="true" tabindex="-1"></a><span class="va">received</span> <span class="op">=</span> <span class="va">interference_channel</span>(<span class="va">modulated</span>)<span class="op">;</span></span>
<span id="cb1-16"><a href="#cb1-16" aria-hidden="true" tabindex="-1"></a><span class="va">nominal_channel_length</span> <span class="op">=</span> <span class="fl">8</span></span>
<span id="cb1-17"><a href="#cb1-17" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-18"><a href="#cb1-18" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-19"><a href="#cb1-19" aria-hidden="true" tabindex="-1"></a><span class="va">modulated_training_sequence</span> <span class="op">=</span> <span class="va">minimal_modulation</span>(<span class="va">training_sequence</span>)<span class="op">;</span></span>
<span id="cb1-20"><a href="#cb1-20" aria-hidden="true" tabindex="-1"></a><span class="va">training_sequence_length</span> <span class="op">=</span> <span class="va">length</span>(<span class="va">training_sequence</span>)</span>
<span id="cb1-21"><a href="#cb1-21" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-22"><a href="#cb1-22" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-23"><a href="#cb1-23" aria-hidden="true" tabindex="-1"></a><span class="va">toeplitz_column</span> <span class="op">=</span> <span class="va">modulated_training_sequence</span>(<span class="va">nominal_channel_length</span><span class="op">:</span><span class="va">training_sequence_length</span>)<span class="op">;</span></span>
<span id="cb1-24"><a href="#cb1-24" aria-hidden="true" tabindex="-1"></a><span class="va">toeplitz_row</span> <span class="op">=</span> <span class="va">flip</span>(<span class="va">modulated_training_sequence</span>(<span class="fl">1</span><span class="op">:</span><span class="va">nominal_channel_length</span>))<span class="op">;</span></span>
<span id="cb1-25"><a href="#cb1-25" aria-hidden="true" tabindex="-1"></a><span class="va">T</span> <span class="op">=</span> <span class="va">toeplitz</span>(<span class="va">toeplitz_column</span><span class="op">,</span> <span class="va">toeplitz_row</span>)<span class="op">;</span></span>
<span id="cb1-26"><a href="#cb1-26" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-27"><a href="#cb1-27" aria-hidden="true" tabindex="-1"></a><span class="va">awgned</span> <span class="op">=</span> <span class="va">received</span> <span class="co">% awgn(received,10);</span></span>
<span id="cb1-28"><a href="#cb1-28" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-29"><a href="#cb1-29" aria-hidden="true" tabindex="-1"></a><span class="va">clean_part_of_training_sequence</span> <span class="op">=</span> <span class="va">training_sequence_length</span> <span class="op">-</span> <span class="va">nominal_channel_length</span><span class="op">;</span></span>
<span id="cb1-30"><a href="#cb1-30" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-31"><a href="#cb1-31" aria-hidden="true" tabindex="-1"></a><span class="va">losses</span> <span class="op">=</span> <span class="va">ones</span>(<span class="fl">1</span><span class="op">,</span> <span class="va">length</span>(<span class="va">received</span>)<span class="op">-</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb1-32"><a href="#cb1-32" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-33"><a href="#cb1-33" aria-hidden="true" tabindex="-1"></a><span class="kw">for</span> <span class="va">offset</span> <span class="op">=</span> <span class="fl">1</span><span class="op">:</span>(<span class="va">length</span>(<span class="va">received</span>)<span class="op">-</span><span class="va">clean_part_of_training_sequence</span>)</span>
<span id="cb1-34"><a href="#cb1-34" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-35"><a href="#cb1-35" aria-hidden="true" tabindex="-1"></a>	<span class="va">interesting_part_of_received_signal</span> <span class="op">=</span> <span class="va">awgned</span>(<span class="va">offset</span><span class="op">:</span><span class="va">offset</span><span class="op">+</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb1-36"><a href="#cb1-36" aria-hidden="true" tabindex="-1"></a>	<span class="va">estimated_chan</span> <span class="op">=</span> <span class="va">lsqminnorm</span>(<span class="va">T</span><span class="op">,</span> <span class="va">interesting_part_of_received_signal</span>)</span>
<span id="cb1-37"><a href="#cb1-37" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-38"><a href="#cb1-38" aria-hidden="true" tabindex="-1"></a>	<span class="va">loss_vector</span> <span class="op">=</span> <span class="va">T</span><span class="op">*</span> <span class="va">estimated_chan</span> <span class="op">-</span> <span class="va">interesting_part_of_received_signal</span><span class="op">;</span></span>
<span id="cb1-39"><a href="#cb1-39" aria-hidden="true" tabindex="-1"></a>	<span class="va">TS_losses</span>(<span class="va">offset</span>) <span class="op">=</span> <span class="va">norm</span>(<span class="va">loss_vector</span>)<span class="op">;</span></span>
<span id="cb1-40"><a href="#cb1-40" aria-hidden="true" tabindex="-1"></a><span class="kw">end</span></span>
<span id="cb1-41"><a href="#cb1-41" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-42"><a href="#cb1-42" aria-hidden="true" tabindex="-1"></a>[<span class="va">val</span><span class="op">,</span> <span class="va">best_offset</span>] <span class="op">=</span> <span class="va">min</span>(<span class="va">TS_losses</span>)<span class="op">;</span></span>
<span id="cb1-43"><a href="#cb1-43" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-44"><a href="#cb1-44" aria-hidden="true" tabindex="-1"></a><span class="va">interesting_part_of_received_signal</span> <span class="op">=</span> <span class="va">awgned</span>(<span class="va">offset</span><span class="op">:</span><span class="va">offset</span><span class="op">+</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb1-45"><a href="#cb1-45" aria-hidden="true" tabindex="-1"></a><span class="va">best_estimated_chan</span> <span class="op">=</span> <span class="va">lsqminnorm</span>(<span class="va">T</span><span class="op">,</span> <span class="va">interesting_part_of_received_signal</span>)</span>
<span id="cb1-46"><a href="#cb1-46" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-47"><a href="#cb1-47" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-48"><a href="#cb1-48" aria-hidden="true" tabindex="-1"></a><span class="kw">function</span> <span class="va">not_really_filtered</span> <span class="op">=</span> <span class="va">minimal_modulation</span>(<span class="va">data</span>) </span>
<span id="cb1-49"><a href="#cb1-49" aria-hidden="true" tabindex="-1"></a>	<span class="va">not_really_filtered</span> <span class="op">=</span> <span class="va">pammod</span>(<span class="va">data</span><span class="op">,</span><span class="fl">2</span>)<span class="op">;</span></span>
<span id="cb1-50"><a href="#cb1-50" aria-hidden="true" tabindex="-1"></a><span class="kw">end</span></span></code></pre></div>
<h2 id="brute-force-timing-estimation">brute force timing estimation <a href="#brute-force-timing-estimation" class="section">#</a></h2>
<p>The relevant section for what we’re doing today is below. We try every possible offset, and we see which one gives us the smallest loss:</p>
<div class="sourceCode" id="cb2"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb2-1"><a href="#cb2-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-2"><a href="#cb2-2" aria-hidden="true" tabindex="-1"></a><span class="va">losses</span> <span class="op">=</span> <span class="va">ones</span>(<span class="fl">1</span><span class="op">,</span> <span class="va">length</span>(<span class="va">received</span>)<span class="op">-</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb2-3"><a href="#cb2-3" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-4"><a href="#cb2-4" aria-hidden="true" tabindex="-1"></a><span class="kw">for</span> <span class="va">offset</span> <span class="op">=</span> <span class="fl">1</span><span class="op">:</span>(<span class="va">length</span>(<span class="va">received</span>)<span class="op">-</span><span class="va">clean_part_of_training_sequence</span>)</span>
<span id="cb2-5"><a href="#cb2-5" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-6"><a href="#cb2-6" aria-hidden="true" tabindex="-1"></a>	<span class="va">interesting_part_of_received_signal</span> <span class="op">=</span> <span class="va">awgned</span>(<span class="va">offset</span><span class="op">:</span><span class="va">offset</span><span class="op">+</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb2-7"><a href="#cb2-7" aria-hidden="true" tabindex="-1"></a>	<span class="va">estimated_chan</span> <span class="op">=</span> <span class="va">lsqminnorm</span>(<span class="va">T</span><span class="op">,</span> <span class="va">interesting_part_of_received_signal</span>)</span>
<span id="cb2-8"><a href="#cb2-8" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-9"><a href="#cb2-9" aria-hidden="true" tabindex="-1"></a>	<span class="va">loss_vector</span> <span class="op">=</span> <span class="va">T</span><span class="op">*</span> <span class="va">estimated_chan</span> <span class="op">-</span> <span class="va">interesting_part_of_received_signal</span><span class="op">;</span></span>
<span id="cb2-10"><a href="#cb2-10" aria-hidden="true" tabindex="-1"></a>	<span class="va">TS_losses</span>(<span class="va">offset</span>) <span class="op">=</span> <span class="va">norm</span>(<span class="va">loss_vector</span>)<span class="op">;</span></span>
<span id="cb2-11"><a href="#cb2-11" aria-hidden="true" tabindex="-1"></a><span class="kw">end</span></span>
<span id="cb2-12"><a href="#cb2-12" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-13"><a href="#cb2-13" aria-hidden="true" tabindex="-1"></a>[<span class="va">val</span><span class="op">,</span> <span class="va">best_offset</span>] <span class="op">=</span> <span class="va">min</span>(<span class="va">TS_losses</span>)<span class="op">;</span></span>
<span id="cb2-14"><a href="#cb2-14" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb2-15"><a href="#cb2-15" aria-hidden="true" tabindex="-1"></a><span class="va">interesting_part_of_received_signal</span> <span class="op">=</span> <span class="va">awgned</span>(<span class="va">offset</span><span class="op">:</span><span class="va">offset</span><span class="op">+</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb2-16"><a href="#cb2-16" aria-hidden="true" tabindex="-1"></a><span class="va">best_estimated_chan</span> <span class="op">=</span> <span class="va">lsqminnorm</span>(<span class="va">T</span><span class="op">,</span> <span class="va">interesting_part_of_received_signal</span>)</span></code></pre></div>
<p>Yeah, we redo the least squares calculation, but it’s not a big deal. This is a terribly slow way to do timing synchronization anyway, but it’s excellent to figure out what is going on.</p>
<h2 id="this-is-loss">this is loss <a href="#this-is-loss" class="section">#</a></h2>
<p>We <code>plot(TS_losses)</code> and get an unambigous and deep correlation dip:</p>
<figure>
<img src="../images/time-sync-part-1/loss.png" alt="loss.png; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/loss.png">loss.png</a>; click for full size</figcaption>
</figure>
<p>Looking at how we calculated <code>TS_losses</code>, we see that it’s <em>only</em> calculated over the training sequence, not over the whole burst. We are curious to see what happens if we calculate the “error” over the whole burst. We’ll do this by convolving the <em>transmitted</em> signal (before the channel) with the estimated channel, and then subtracting the received signal:</p>
<div class="sourceCode" id="cb3"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb3-1"><a href="#cb3-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">tiledlayout</span>(<span class="fl">2</span><span class="op">,</span><span class="fl">1</span>)</span>
<span id="cb3-2"><a href="#cb3-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb3-3"><a href="#cb3-3" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">received</span>))</span>
<span id="cb3-4"><a href="#cb3-4" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;actual received signal&quot;</span>)</span>
<span id="cb3-5"><a href="#cb3-5" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">fake_received_signal</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">best_estimated_chan</span><span class="op">,</span> <span class="va">modulated</span>)<span class="op">;</span></span>
<span id="cb3-6"><a href="#cb3-6" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb3-7"><a href="#cb3-7" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">fake_received_signal</span>))</span>
<span id="cb3-8"><a href="#cb3-8" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;fake received signal&quot;</span>)</span>
<span id="cb3-9"><a href="#cb3-9" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">copygraphics</span>(<span class="va">gcf</span>)</span></code></pre></div>
<p>and they don’t look very similar at all :(</p>
<figure>
<img src="../images/time-sync-part-1/fake_vs_real.png" alt="fake_vs_real.png; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/fake_vs_real.png">fake_vs_real.png</a>; click for full size</figcaption>
</figure>
<p>Either we made a big mistake, or there’s behavior in the real channel that a convolution with the estimated channel is failing to capture.</p>
<h2 id="the-fake-in-its-attempt-to-be-real">the fake, in its attempt to be real <a href="#the-fake-in-its-attempt-to-be-real" class="section">#</a></h2>
<p>We try and plot the difference, praying that there might be something interesting there…and get an error.</p>
<div class="sourceCode" id="cb4"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb4-1"><a href="#cb4-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">received</span><span class="op">-</span><span class="va">fake_received_signal</span>))</span>
<span id="cb4-2"><a href="#cb4-2" aria-hidden="true" tabindex="-1"></a><span class="va">Arrays</span> <span class="va">have</span> <span class="va">incompatible</span> <span class="va">sizes</span> <span class="kw">for</span> <span class="va">this</span> <span class="va">operation</span>.</span></code></pre></div>
<p>This leads us to look at the sizes, and more specifically, the difference in sizes:</p>
<div class="sourceCode" id="cb5"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb5-1"><a href="#cb5-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">size</span>(<span class="va">fake_received_signal</span>)</span>
<span id="cb5-2"><a href="#cb5-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-3"><a href="#cb5-3" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb5-4"><a href="#cb5-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-5"><a href="#cb5-5" aria-hidden="true" tabindex="-1"></a>   <span class="fl">225</span>     <span class="fl">1</span></span>
<span id="cb5-6"><a href="#cb5-6" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-7"><a href="#cb5-7" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">size</span>(<span class="va">received</span>)</span>
<span id="cb5-8"><a href="#cb5-8" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-9"><a href="#cb5-9" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb5-10"><a href="#cb5-10" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-11"><a href="#cb5-11" aria-hidden="true" tabindex="-1"></a>   <span class="fl">218</span>     <span class="fl">1</span></span>
<span id="cb5-12"><a href="#cb5-12" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-13"><a href="#cb5-13" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="fl">218</span><span class="op">-</span><span class="fl">225</span></span>
<span id="cb5-14"><a href="#cb5-14" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-15"><a href="#cb5-15" aria-hidden="true" tabindex="-1"></a><span class="va">ans</span> <span class="op">=</span></span>
<span id="cb5-16"><a href="#cb5-16" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb5-17"><a href="#cb5-17" aria-hidden="true" tabindex="-1"></a>    <span class="op">-</span><span class="fl">7</span></span></code></pre></div>
<p>7 is sus because it’s almost 8, the putative channel size in GSM. We look at the plots again, and we observe that the actual received signal is preceded by samples that look…zero-ish, and exactly 7 of them at that:</p>
<div class="sourceCode" id="cb6"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb6-1"><a href="#cb6-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">received</span></span>
<span id="cb6-2"><a href="#cb6-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb6-3"><a href="#cb6-3" aria-hidden="true" tabindex="-1"></a><span class="va">received</span> <span class="op">=</span></span>
<span id="cb6-4"><a href="#cb6-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb6-5"><a href="#cb6-5" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">0.0000</span> <span class="op">+</span> <span class="fl">0.0001i</span> <span class="co">% 1</span></span>
<span id="cb6-6"><a href="#cb6-6" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">0.0014</span> <span class="op">-</span> <span class="fl">0.0006i</span> <span class="co">% 2</span></span>
<span id="cb6-7"><a href="#cb6-7" aria-hidden="true" tabindex="-1"></a>   <span class="fl">0.0027</span> <span class="op">+</span> <span class="fl">0.0010i</span> <span class="co">% 3</span></span>
<span id="cb6-8"><a href="#cb6-8" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">0.0003</span> <span class="op">-</span> <span class="fl">0.0022i</span> <span class="co">% 4</span></span>
<span id="cb6-9"><a href="#cb6-9" aria-hidden="true" tabindex="-1"></a>   <span class="fl">0.0019</span> <span class="op">+</span> <span class="fl">0.0056i</span> <span class="co">% 5</span></span>
<span id="cb6-10"><a href="#cb6-10" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">0.0040</span> <span class="op">-</span> <span class="fl">0.0044i</span> <span class="co">% 6</span></span>
<span id="cb6-11"><a href="#cb6-11" aria-hidden="true" tabindex="-1"></a>   <span class="fl">0.0018</span> <span class="op">+</span> <span class="fl">0.0033i</span> <span class="co">% 7</span></span>
<span id="cb6-12"><a href="#cb6-12" aria-hidden="true" tabindex="-1"></a>   <span class="fl">0.1531</span> <span class="op">+</span> <span class="fl">0.2801i</span></span>
<span id="cb6-13"><a href="#cb6-13" aria-hidden="true" tabindex="-1"></a>   <span class="fl">0.2313</span> <span class="op">+</span> <span class="fl">0.2729i</span></span>
<span id="cb6-14"><a href="#cb6-14" aria-hidden="true" tabindex="-1"></a>   <span class="fl">0.3761</span> <span class="op">-</span> <span class="fl">0.1057i</span></span>
<span id="cb6-15"><a href="#cb6-15" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">0.1923</span> <span class="op">-</span> <span class="fl">0.1956i</span></span>
<span id="cb6-16"><a href="#cb6-16" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">0.7524</span> <span class="op">-</span> <span class="fl">0.6256i</span></span></code></pre></div>
<p>This hasn’t had AWGN added – this is just from the effect of <code>stdchan("gsmEQx6", nominal_sample_rate, 0)</code>. It looks like this Matlab channel simulation is flushing the channel with some noise, since the modulated signal doesn’t look like this at all:</p>
<div class="sourceCode" id="cb7"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb7-1"><a href="#cb7-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">modulated</span></span>
<span id="cb7-2"><a href="#cb7-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb7-3"><a href="#cb7-3" aria-hidden="true" tabindex="-1"></a><span class="va">modulated</span> <span class="op">=</span></span>
<span id="cb7-4"><a href="#cb7-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb7-5"><a href="#cb7-5" aria-hidden="true" tabindex="-1"></a>   <span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-6"><a href="#cb7-6" aria-hidden="true" tabindex="-1"></a>   <span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-7"><a href="#cb7-7" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-8"><a href="#cb7-8" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-9"><a href="#cb7-9" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-10"><a href="#cb7-10" aria-hidden="true" tabindex="-1"></a>   <span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-11"><a href="#cb7-11" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-12"><a href="#cb7-12" aria-hidden="true" tabindex="-1"></a>  <span class="op">-</span><span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-13"><a href="#cb7-13" aria-hidden="true" tabindex="-1"></a>   <span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span>
<span id="cb7-14"><a href="#cb7-14" aria-hidden="true" tabindex="-1"></a>   <span class="fl">1.0000</span> <span class="op">+</span> <span class="fl">0.0000i</span></span></code></pre></div>
<p>If we run a cross-correlation between this “fake” received signal (generated by convolving the original modulated signal with the estimated channel) and the actual received signal, we get something remarkably disappointing:</p>
<div class="sourceCode" id="cb8"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb8-1"><a href="#cb8-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">fake_received_signal</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">best_estimated_chan</span><span class="op">,</span> <span class="va">modulated</span>)<span class="op">;</span></span>
<span id="cb8-2"><a href="#cb8-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> [<span class="va">c</span><span class="op">,</span> <span class="va">lagz</span>] <span class="op">=</span> <span class="va">xcorr</span>(<span class="va">received</span><span class="op">,</span> <span class="va">fake_received_signal</span>)<span class="op">;</span></span>
<span id="cb8-3"><a href="#cb8-3" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">stem</span>(<span class="va">lagz</span><span class="op">,</span><span class="va">abs</span>(<span class="va">c</span>))</span></code></pre></div>
<figure>
<img src="../images/time-sync-part-1/xcorr-fake-vs-real.png" alt="stem(lagz,abs(c)); click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/xcorr-fake-vs-real.png">stem(lagz,abs(c))</a>; click for full size</figcaption>
</figure>
<p>If we zoom in on the center, we see it’s unfortunately nowhere near sharp:</p>
<figure>
<img src="../images/time-sync-part-1/zoomed-xcorr.png" alt="stem(lagz,abs(c)); click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/zoomed-xcorr.png">stem(lagz,abs(c))</a>; click for full size</figcaption>
</figure>
<p>It’s still unclear exactly what is going on – the behavior differences at the beginning/end of the channel simulation fail to explain the catastrophic lack of similarity.</p>
<h2 id="return-to-a-simpler-channel">return to a simpler channel <a href="#return-to-a-simpler-channel" class="section">#</a></h2>
<p>We go back to our contrived, integer-valued channel:</p>
<div class="sourceCode" id="cb9"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb9-1"><a href="#cb9-1" aria-hidden="true" tabindex="-1"></a><span class="va">received</span> <span class="op">=</span>  <span class="va">conv</span>(<span class="va">modulated</span><span class="op">,</span> [<span class="fl">1</span><span class="op">,</span><span class="fl">2</span><span class="op">,</span><span class="fl">3</span><span class="op">,</span><span class="fl">4</span><span class="op">,</span><span class="fl">5</span><span class="op">,</span><span class="fl">4</span><span class="op">,</span><span class="fl">3</span><span class="op">,</span><span class="fl">2</span>])<span class="op">;</span></span></code></pre></div>
<p>and run this again. To make things really simple, we turn off the noise:</p>
<div class="sourceCode" id="cb10"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb10-1"><a href="#cb10-1" aria-hidden="true" tabindex="-1"></a><span class="va">awgned</span> <span class="op">=</span> <span class="va">received</span><span class="op">;</span></span></code></pre></div>
<p>We plot <code>TS_loss</code> and see a perfect zero loss at an offset of 72 (64 + 8):</p>
<figure>
<img src="../images/time-sync-part-1/perfect-zero-loss.png" alt="plot(TS_loss); click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/perfect-zero-loss.png">plot(TS_loss)</a>; click for full size</figcaption>
</figure>
<p>but the best estimated channel is nowhere near the actual channel, which is <code>[1,2,3,4,5,4,3,2]</code>:</p>
<div class="sourceCode" id="cb11"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb11-1"><a href="#cb11-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">best_estimated_chan</span></span>
<span id="cb11-2"><a href="#cb11-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-3"><a href="#cb11-3" aria-hidden="true" tabindex="-1"></a><span class="va">best_estimated_chan</span> <span class="op">=</span></span>
<span id="cb11-4"><a href="#cb11-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-5"><a href="#cb11-5" aria-hidden="true" tabindex="-1"></a>    <span class="fl">1.2873</span></span>
<span id="cb11-6"><a href="#cb11-6" aria-hidden="true" tabindex="-1"></a>    <span class="fl">0.3579</span></span>
<span id="cb11-7"><a href="#cb11-7" aria-hidden="true" tabindex="-1"></a>   <span class="op">-</span><span class="fl">1.0171</span></span>
<span id="cb11-8"><a href="#cb11-8" aria-hidden="true" tabindex="-1"></a>   <span class="op">-</span><span class="fl">0.6468</span></span>
<span id="cb11-9"><a href="#cb11-9" aria-hidden="true" tabindex="-1"></a>   <span class="op">-</span><span class="fl">0.5164</span></span>
<span id="cb11-10"><a href="#cb11-10" aria-hidden="true" tabindex="-1"></a>   <span class="op">-</span><span class="fl">0.3579</span></span>
<span id="cb11-11"><a href="#cb11-11" aria-hidden="true" tabindex="-1"></a>   <span class="op">-</span><span class="fl">3.1032</span></span>
<span id="cb11-12"><a href="#cb11-12" aria-hidden="true" tabindex="-1"></a>   <span class="op">-</span><span class="fl">2.9164</span></span>
<span id="cb11-13"><a href="#cb11-13" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb11-14"><a href="#cb11-14" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> </span></code></pre></div>
<h3 id="its-a-bug">it’s a bug <a href="#its-a-bug" class="section">#</a></h3>
<p>So we take a look at our code again, and we find a plain old bug:</p>
<div class="sourceCode" id="cb12"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb12-1"><a href="#cb12-1" aria-hidden="true" tabindex="-1"></a><span class="kw">for</span> <span class="va">offset</span> <span class="op">=</span> <span class="fl">1</span><span class="op">:</span>(<span class="va">length</span>(<span class="va">received</span>)<span class="op">-</span><span class="va">clean_part_of_training_sequence</span>)</span>
<span id="cb12-2"><a href="#cb12-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb12-3"><a href="#cb12-3" aria-hidden="true" tabindex="-1"></a>	<span class="va">interesting_part_of_received_signal</span> <span class="op">=</span> <span class="va">awgned</span>(<span class="va">offset</span><span class="op">:</span><span class="va">offset</span><span class="op">+</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb12-4"><a href="#cb12-4" aria-hidden="true" tabindex="-1"></a>	<span class="va">estimated_chan</span> <span class="op">=</span> <span class="va">lsqminnorm</span>(<span class="va">T</span><span class="op">,</span> <span class="va">interesting_part_of_received_signal</span>)</span>
<span id="cb12-5"><a href="#cb12-5" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb12-6"><a href="#cb12-6" aria-hidden="true" tabindex="-1"></a>	<span class="va">loss_vector</span> <span class="op">=</span> <span class="va">T</span><span class="op">*</span> <span class="va">estimated_chan</span> <span class="op">-</span> <span class="va">interesting_part_of_received_signal</span><span class="op">;</span></span>
<span id="cb12-7"><a href="#cb12-7" aria-hidden="true" tabindex="-1"></a>	<span class="va">TS_losses</span>(<span class="va">offset</span>) <span class="op">=</span> <span class="va">norm</span>(<span class="va">loss_vector</span>)<span class="op">;</span></span>
<span id="cb12-8"><a href="#cb12-8" aria-hidden="true" tabindex="-1"></a><span class="kw">end</span></span>
<span id="cb12-9"><a href="#cb12-9" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb12-10"><a href="#cb12-10" aria-hidden="true" tabindex="-1"></a>[<span class="va">val</span><span class="op">,</span> <span class="va">best_offset</span>] <span class="op">=</span> <span class="va">min</span>(<span class="va">TS_losses</span>)</span>
<span id="cb12-11"><a href="#cb12-11" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb12-12"><a href="#cb12-12" aria-hidden="true" tabindex="-1"></a><span class="va">interesting_part_of_received_signal</span> <span class="op">=</span> <span class="va">awgned</span>(<span class="va">offset</span><span class="op">:</span><span class="va">offset</span><span class="op">+</span><span class="va">clean_part_of_training_sequence</span>)<span class="op">;</span></span>
<span id="cb12-13"><a href="#cb12-13" aria-hidden="true" tabindex="-1"></a><span class="va">best_estimated_chan</span> <span class="op">=</span> <span class="va">lsqminnorm</span>(<span class="va">T</span><span class="op">,</span> <span class="va">interesting_part_of_received_signal</span>)</span></code></pre></div>
<p>In the penultimate line, where we slice out the part of the received signal we’ll run a least-squares on, the indices for the slice are<code>(</code><strong><code>offset</code></strong><code>:</code><strong><code>offset</code></strong><code>+clean_part_of_training_sequence)</code>.</p>
<p><code>offset</code> is the loop variable, and its value there is quite simply the offset of the <em>last</em> least-squares computed in the loop. It is not <code>best_offset</code>, which is the index of the minimum loss.</p>
<p>We fix this, and now the best estimated channel is indeed what we expect it to be:</p>
<div class="sourceCode" id="cb13"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb13-1"><a href="#cb13-1" aria-hidden="true" tabindex="-1"></a><span class="va">best_estimated_chan</span> <span class="op">=</span></span>
<span id="cb13-2"><a href="#cb13-2" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb13-3"><a href="#cb13-3" aria-hidden="true" tabindex="-1"></a>    <span class="fl">1.0000</span></span>
<span id="cb13-4"><a href="#cb13-4" aria-hidden="true" tabindex="-1"></a>    <span class="fl">2.0000</span></span>
<span id="cb13-5"><a href="#cb13-5" aria-hidden="true" tabindex="-1"></a>    <span class="fl">3.0000</span></span>
<span id="cb13-6"><a href="#cb13-6" aria-hidden="true" tabindex="-1"></a>    <span class="fl">4.0000</span></span>
<span id="cb13-7"><a href="#cb13-7" aria-hidden="true" tabindex="-1"></a>    <span class="fl">5.0000</span></span>
<span id="cb13-8"><a href="#cb13-8" aria-hidden="true" tabindex="-1"></a>    <span class="fl">4.0000</span></span>
<span id="cb13-9"><a href="#cb13-9" aria-hidden="true" tabindex="-1"></a>    <span class="fl">3.0000</span></span>
<span id="cb13-10"><a href="#cb13-10" aria-hidden="true" tabindex="-1"></a>    <span class="fl">2.0000</span></span></code></pre></div>
<h2 id="a-brief-detour-in-shoggoth-land">a brief detour in <a href="https://knowyourmeme.com/memes/shoggoth-with-smiley-face-artificial-intelligence">shoggoth</a>-land <a href="#a-brief-detour-in-shoggoth-land" class="section">#</a></h2>
<p>Out of curiosity, I gave the above excerpt to ChatGPT-4 preceded by the prompt “find the bug:”, and it figures it out perfectly!</p>
<figure>
<img src="../images/time-sync-part-1/gpt-4-is-all-you-need.png" alt="😊" />
<figcaption aria-hidden="true">😊</figcaption>
</figure>
<p>GPT-3.5 didn’t clue in on it, and even GPT-4 didn’t clue in on it when fed the whole file’s contents rather than the excerpt.</p>
<h2 id="validating-the-fix">validating the fix <a href="#validating-the-fix" class="section">#</a></h2>
<p>With this fix in place, we see that the fake received signal (generated by convolving the transmitted signal with the best estimated channel) is indeed identical to the original received signal, at least with the contrived channel:</p>
<figure>
<img src="../images/time-sync-part-1/contrived-match.png" alt="contrived channel matches; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/contrived-match.png">contrived channel matches</a>; click for full size</figcaption>
</figure>
<h2 id="looking-at-real-channels-again">looking at real channels again <a href="#looking-at-real-channels-again" class="section">#</a></h2>
<p>We go back to the real channel (well, it’s not an actual IRL channel but it’s a simulation of an IRL channel), and see how much better our “fake” (generated by convolving the transmitted signal with the best estimated channel) received signal is:</p>
<figure>
<img src="../images/time-sync-part-1/fake-vs-real-with-real-channel.png" alt="real channel almost perfectly matches; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/fake-vs-real-with-real-channel.png">real channel almost perfectly matches</a>; click for full size</figcaption>
</figure>
<p>Now <em>this</em> is a specimen!</p>
<p>This is, effectively, <strong>the same signal</strong>, except for subtleties in how the beginning and end are handled. It looks like the channel simulator flushes (seasons?) the beginning of the channel with very low-amplitude noise, and handles the end by “cutting off” the simulation before letting the channel “drain”, whereas the simplistic convolution doesn’t prepend low-amplitude noise at the beginning and lets the channel completely drain out.</p>
<p>If we add sufficient zeros to the beginning and end of the modulated signal, and feed it in both the channel simulation and the convolution:</p>
<div class="sourceCode" id="cb14"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb14-1"><a href="#cb14-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">received</span> <span class="op">=</span> <span class="va">interference_channel</span>([<span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span><span class="va">modulated</span><span class="op">;</span><span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)])<span class="op">;</span></span>
<span id="cb14-2"><a href="#cb14-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">tiledlayout</span>(<span class="fl">2</span><span class="op">,</span><span class="fl">1</span>)</span>
<span id="cb14-3"><a href="#cb14-3" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb14-4"><a href="#cb14-4" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">received</span>))</span>
<span id="cb14-5"><a href="#cb14-5" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;actual received signal&quot;</span>)</span>
<span id="cb14-6"><a href="#cb14-6" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">fake_received_signal</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">best_estimated_chan</span><span class="op">,</span> [<span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span><span class="va">modulated</span><span class="op">;</span><span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)])<span class="op">;</span></span>
<span id="cb14-7"><a href="#cb14-7" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb14-8"><a href="#cb14-8" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">abs</span>(<span class="va">fake_received_signal</span>))</span>
<span id="cb14-9"><a href="#cb14-9" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;fake received signal&quot;</span>)</span>
<span id="cb14-10"><a href="#cb14-10" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">copygraphics</span>(<span class="va">gcf</span>)</span></code></pre></div>
<figure>
<img src="../images/time-sync-part-1/with-zeros.png" alt="comparison with zeros; click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/with-zeros.png">comparison with zeros</a>; click for full size</figcaption>
</figure>
<p>Since these are complex signals, we should be sure that the real/imaginary parts match, and not just the magnitudes:</p>
<div class="sourceCode" id="cb15"><pre class="sourceCode matlab"><code class="sourceCode matlab"><span id="cb15-1"><a href="#cb15-1" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">received</span> <span class="op">=</span> <span class="va">interference_channel</span>([<span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span><span class="va">modulated</span><span class="op">;</span><span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)])<span class="op">;</span></span>
<span id="cb15-2"><a href="#cb15-2" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">fake_received_signal</span> <span class="op">=</span> <span class="va">conv</span>(<span class="va">best_estimated_chan</span><span class="op">,</span> [<span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)<span class="op">;</span><span class="va">modulated</span><span class="op">;</span><span class="va">zeros</span>(<span class="fl">16</span><span class="op">,</span><span class="fl">1</span>)])<span class="op">;</span></span>
<span id="cb15-3"><a href="#cb15-3" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">tiledlayout</span>(<span class="fl">2</span><span class="op">,</span><span class="fl">2</span>)</span>
<span id="cb15-4"><a href="#cb15-4" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb15-5"><a href="#cb15-5" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">real</span>(<span class="va">received</span>))</span>
<span id="cb15-6"><a href="#cb15-6" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;received signal, real&quot;</span>)</span>
<span id="cb15-7"><a href="#cb15-7" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb15-8"><a href="#cb15-8" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">imag</span>(<span class="va">received</span>))</span>
<span id="cb15-9"><a href="#cb15-9" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;received signal, imag&quot;</span>)</span>
<span id="cb15-10"><a href="#cb15-10" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb15-11"><a href="#cb15-11" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">real</span>(<span class="va">fake_received_signal</span>))</span>
<span id="cb15-12"><a href="#cb15-12" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;fake received signal, real&quot;</span>)</span>
<span id="cb15-13"><a href="#cb15-13" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">nexttile</span></span>
<span id="cb15-14"><a href="#cb15-14" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">plot</span>(<span class="va">imag</span>(<span class="va">fake_received_signal</span>))</span>
<span id="cb15-15"><a href="#cb15-15" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">title</span>(<span class="st">&quot;fake received signal, imag&quot;</span>)</span>
<span id="cb15-16"><a href="#cb15-16" aria-hidden="true" tabindex="-1"></a><span class="op">&gt;&gt;</span> <span class="va">copygraphics</span>(<span class="va">gcf</span>)</span></code></pre></div>
<figure>
<img src="../images/time-sync-part-1/real-and-imag.png" alt="real and imaginary (with zero padding); click for full size" />
<figcaption aria-hidden="true"><a href="../images/time-sync-part-1/real-and-imag.png">real and imaginary (with zero padding)</a>; click for full size</figcaption>
</figure>
<p>Looks good!</p>
<h2 id="a-simpler-method-will-wait-for-next-time">a simpler method will wait for next time <a href="#a-simpler-method-will-wait-for-next-time" class="section">#</a></h2>
<p>We’ve actually made a working time synchronization estimator! Unfortunately it’s incredibly inefficient – requiring a whole least-squares estimate for every possible offset. However, it will serve as an ironclad gold standard<a href="#fn1" class="footnote-ref" id="fnref1" role="doc-noteref"><sup>1</sup></a> and help us build a more efficient synchronization estimator next time.</p>
<section id="footnotes" class="footnotes footnotes-end-of-document" role="doc-endnotes">
<hr />
<ol>
<li id="fn1"><p>“ironclad gold standard” is funny if you take it literally (usually you plate cheap metals with gold, not the other way around :D)<a href="#fnref1" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
</ol>
</section>]]></summary>
</entry>
<entry>
    <title>GSM receiver blocks: least-squares channel estimation part 3: thinking about model mismatch</title>
    <link href="https://softminus.org/posts/bigger-channel.html" />
    <id>https://softminus.org/posts/bigger-channel.html</id>
    <published>2023-04-13</published>
    <updated>2023-04-13T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-least-squares-channel-estimation-part-3-thinking-about-model-mismatch">GSM receiver blocks: least-squares channel estimation part 3: thinking about model mismatch</h1>
<p>Let’s look at the case when the actual channel is slightly longer than the model. If the channel is <strong>much</strong> longer than the model, then the model will be unable to capture most of the channel’s properties, and the channel estimation will probably be nonsense. But if the channel is only <em>slightly</em> longer than the model, then the model will be able to capture most of the channel’s information (with some inherent inaccuracy). In this case, the channel estimation might be good enough for practical purposes.</p>
<p>For a practical example, let’s say that we have a training sequence of length 10, and an assumed channel of length 4. As usual, the training sequence is sandwiched between unknown data symbols.</p>
<p>We call the training sequence symbols <span class="math inline">\(TS = t_{1}, \cdots, t_{10}\)</span>, the data symbols (presumed unknown here) <span class="math inline">\(d_{i}\)</span> (for <span class="math inline">\(i&lt;1\)</span> or <span class="math inline">\(i&gt;10\)</span>), and the channel coefficients <span class="math inline">\(chan = c_1,\cdots,c_4\)</span>. The channel is assumed to be causal, so the channel output is given by convolving the channel coefficients with the transmitted symbols <span class="math inline">\(d_{-1}, d_{0}, t_{1}, \cdots, t_{10}, d_{11}, d_{12}\)</span>.</p>
<h2 id="observation-model-and-least-squares">observation model and least squares <a href="#observation-model-and-least-squares" class="section">#</a></h2>
<p>The observation model is a convolution of the signal against the channel and looks like this (we draw the matrices aligned that way to make it clear how the multiplication works):
<span class="math display">\[\begin{align*}
&amp; \begin{bmatrix}
  c_{1}\\
  c_{2}\\
  c_{3}\\
  c_{4}
  \end{bmatrix}
&amp; \\
 \begin{bmatrix}
  t_{1} &amp; d_{0} &amp; d_{-1} &amp; d_{-2} \\
  t_{2} &amp; d_{1} &amp; d_{0} &amp; d_{-1} \\
  t_{3} &amp; t_{2} &amp; t_{1} &amp; d_{0} \\
  \hdashline
  t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} \\
  t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2} \\
  t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3} \\
  t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4} \\
  t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5} \\
  t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6} \\
  t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7} \\
  \hdashline
  d_{11} &amp; t_{10} &amp; t_{9} &amp; t_{8} \\
  d_{12} &amp; d_{11} &amp; t_{10} &amp; t_{9} \\
  d_{13} &amp; d_{12} &amp; d_{11} &amp; t_{10} \\
  \end{bmatrix}
\ast&amp;&amp;  =
\begin{bmatrix}
{r_{2}} \\
{r_{3}} \\
{r_{4}} \\
\hdashline
{r_{5}} \\
{r_{6}} \\
{r_{7}} \\
{r_{8}} \\
{r_{9}} \\
{r_{10}} \\
{r_{11}} \\
\hdashline
{r_{12}} \\
{r_{13}} \\
{r_{14}} \\
\end{bmatrix}
\end{align*}\]</span></p>
<p>Everything above and below the dashed lines is influenced by unknown data symbols, so we focus on the middle section of the matrix and the corresponding produced received symbols.</p>
<p>We notice that the least squares process “tries to” estimate the received symbols as a linear combination of the four columns of this matrix:</p>
<p><span class="math display">\[\begin{bmatrix}
  t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} \\
  t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2} \\
  t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3} \\
  t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4} \\
  t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5} \\
  t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6} \\
  t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7} \\
  \end{bmatrix}\]</span></p>
<p>The least squares process will try to find coefficients <span class="math inline">\([\hat{c}_{1}, \hat{c}_{2}, \hat{c}_{3}, \hat{c}_{4}]\)</span> such that the received symbols are well approximated by the linear combination of the four columns. The first received symbol not affected by unknown data – the first received symbol we ingest for the least-squares – is <span class="math inline">\(r_5 = c_1 \cdot t_4 + c_2 \cdot t_3 + c_3 \cdot t_2 + c_4 \cdot t_1\)</span>, and this makes sense since the first row of the observation matrix is <span class="math inline">\([t_4, t_3, t_2, t_1]\)</span>.</p>
<h2 id="more-channel-coefficients-more-problems">more channel coefficients, more problems <a href="#more-channel-coefficients-more-problems" class="section">#</a></h2>
<p>If we add an extra channel coefficient <span class="math inline">\(c_5\)</span> , then the observation model looks like this. We bold the <span class="math inline">\(\mathbf{d_{0}}\)</span> in the fifth column since it is between the dashed lines but is an unknown data symbol. The red terms are the terms added by the extra channel coefficient.</p>
<p><span class="math display">\[\begin{align*}
&amp; \begin{bmatrix}
  c_{1}\\
  c_{2}\\
  c_{3}\\
  c_{4} \\
  \color{red}c_{5}
  \end{bmatrix}
&amp; \\
 \begin{bmatrix}
  t_{1} &amp; d_{0} &amp; d_{-1} &amp; d_{-2} &amp; \color{red}  d_{-3} \\
  t_{2} &amp; d_{1} &amp; d_{0} &amp; d_{-1} &amp; \color{red}   d_{-2} \\
  t_{3} &amp; t_{2} &amp; t_{1} &amp; d_{0} &amp; \color{red}    d_{-1}\\
  \hdashline
  t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} &amp; \color{red}    \mathbf{d_{0}}\\
  t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2} &amp; \color{red}    t_{1} \\
  t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3} &amp; \color{red}    t_{2}\\
  t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4} &amp; \color{red}    t_{3}\\
  t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5} &amp; \color{red}t_{4}\\
  t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6} &amp; \color{red}t_{5}\\
  t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7} &amp; \color{red}t_{6}\\
  \hdashline
  d_{11} &amp; t_{10} &amp; t_{9} &amp; t_{8} &amp; \color{red}t_{7}\\
  d_{12} &amp; d_{11} &amp; t_{10} &amp; t_{9} &amp; \color{red}t_{8}\\
  d_{13} &amp; d_{12} &amp; d_{11} &amp; t_{10} &amp; \color{red}t_{9}\\
  \end{bmatrix}
\ast&amp;&amp;  =
\begin{bmatrix}
{r_{2}} \\
{r_{3}} \\
{r_{4}} \\
\hdashline
{r_{5}} \\
{r_{6}} \\
{r_{7}} \\
{r_{8}} \\
{r_{9}} \\
{r_{10}} \\
{r_{11}} \\
\hdashline
{r_{12}} \\
{r_{13}} \\
{r_{14}} \\
\end{bmatrix}
+ c_{5}
\begin{bmatrix}
\color{red}d_{-3} \\
\color{red}d_{-2} \\
\color{red}d_{-1}\\
\hdashline
\color{red}\mathbf{d_{0}}\\
\color{red}t_{1} \\
\color{red}t_{2}\\
\color{red}t_{3}\\
\color{red}t_{4}\\
\color{red}t_{5}\\
\color{red}t_{6}\\
\hdashline
\color{red}t_{7}\\
\color{red}t_{8}\\
\color{red}t_{9}
\end{bmatrix}
\end{align*}\]</span></p>
<p>If <span class="math inline">\(c_5\)</span> is significantly less than the other coefficients, we can treat its contribution (the new vector on the right) to the received symbols like noise (and hope that it won’t mess up the estimation too much).</p>
<p>If the energy is distributed pretty evenly across all five channel coefficients, we can’t do this, since it’ll significantly worsen the fit. However, if we have the opposite case – <span class="math inline">\(c_1\)</span> significantly less than the other coefficients – we can do something similar to the previous case. We can treat the <em>first</em> column of the observation matrix as noise, and try to estimate the other four columns.</p>
<h2 id="its-all-off-by-ones-always-was">it’s all off-by-ones? always was! <a href="#its-all-off-by-ones-always-was" class="section">#</a></h2>
<p>Here’s the observation model if we’re trying to treat <span class="math inline">\(c_1\)</span> as negligible:</p>
<p><span class="math display">\[\begin{align*}
&amp; \begin{bmatrix}
  \color{red}c_{1}\\
  c_{2}\\
  c_{3}\\
  c_{4} \\
  c_{5}
  \end{bmatrix}
&amp; \\
\left[ \begin{array}{c|cccc}
  \color{red}t_{1} &amp; d_{0} &amp; d_{-1} &amp; d_{-2} &amp; d_{-3} \\
  \color{red}t_{2} &amp; d_{1} &amp; d_{0} &amp; d_{-1}  &amp; d_{-2} \\
  \color{red}t_{3} &amp; t_{2} &amp; t_{1} &amp; d_{0}   &amp; d_{-1}\\
  \hdashline
  \color{red}t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} &amp; \mathbf{d_{0}}\\
  \color{red}t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} \\
  \color{red}t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2}\\
  \color{red}t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3}\\
  \color{red}t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4}\\
  \color{red}t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5}\\
  \color{red}t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6}\\
  \hdashline
  \color{red}d_{11} &amp; t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7}\\
  \color{red}d_{12} &amp; d_{11} &amp; t_{10} &amp; t_{9} &amp; t_{8}\\
  \color{red}d_{13} &amp; d_{12} &amp; d_{11} &amp; t_{10} &amp; t_{9}\\
  \end{array}\right]
\ast&amp;&amp;  =
c_{1}
\begin{bmatrix}
\color{red}t_{1} \\
\color{red}t_{2} \\
\color{red}t_{3} \\
\hdashline
\color{red}t_{4} \\
\color{red}t_{5} \\
\color{red}t_{6} \\
\color{red}t_{7} \\
\color{red}t_{8} \\
\color{red}t_{9} \\
\color{red}t_{10} \\
\hdashline
\color{red}d_{11} \\
\color{red}d_{12} \\
\color{red}d_{13} \\
\end{bmatrix}
+
\begin{bmatrix}
{r_{2}} \\
{r_{3}} \\
{r_{4}} \\
\hdashline
{r_{5}} \\
{r_{6}} \\
{r_{7}} \\
{r_{8}} \\
{r_{9}} \\
{r_{10}} \\
{r_{11}} \\
\hdashline
{r_{12}} \\
{r_{13}} \\
{r_{14}} \\
\end{bmatrix}
\end{align*}\]</span></p>
<p>However, we need to be careful with indices when we do this! Note that if we ignore the stuff in red, the submatrix in between the horizontal dashed lines is <strong>not</strong> the same column vectors as previously! This will cause trouble! In order to get the <strong>same column vectors</strong> (those only containing known training symbols and spanning the maximum possible length) as before <em>and</em> have them multiplied with the correct subset of the channel <span class="math inline">\([c_2,\cdots,c_5]\)</span>, we need to shift the indices by one.</p>
<p>Indeed, to have a least-squares that generates a sensible output, the first received symbol we use needs to be <span class="math inline">\(\textrm{noise} + c_2 \cdot t_4 + c_3 \cdot t_3 + c_4 \cdot t_2 + c_5 \cdot t_1\)</span> (with the “noise” being the contribution from the first channel tap, which we are assuming is negligible). We need this since the first row of the least-squares matrix <em>still</em> is <span class="math inline">\([t_4, t_3, t_2, t_1]\)</span>. Looking at the indices of this desired received symbol, we see that this would be <span class="math inline">\(r_6\)</span>, not <span class="math inline">\(r_5\)</span> in the previous case.</p>
<p>To write the correct observation model (which highlights the matrix we’ll use for least-squares), we simply move the horizontal dashed lines one row down!</p>
<p><span class="math display">\[\begin{align*}
&amp; \begin{bmatrix}
  \color{red}c_{1}\\
  c_{2}\\
  c_{3}\\
  c_{4} \\
  c_{5}
  \end{bmatrix}
&amp; \\
\left[ \begin{array}{c|cccc}
  \color{red}t_{1} &amp; d_{0} &amp; d_{-1} &amp; d_{-2} &amp; d_{-3} \\
  \color{red}t_{2} &amp; d_{1} &amp; d_{0} &amp; d_{-1}  &amp; d_{-2} \\
  \color{red}t_{3} &amp; t_{2} &amp; t_{1} &amp; d_{0}   &amp; d_{-1}\\
  \color{red}t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} &amp; \mathbf{d_{0}}\\
  \hdashline
  \color{red}t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2} &amp; t_{1} \\
  \color{red}t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3} &amp; t_{2}\\
  \color{red}t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4} &amp; t_{3}\\
  \color{red}t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5} &amp; t_{4}\\
  \color{red}t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6} &amp; t_{5}\\
  \color{red}t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7} &amp; t_{6}\\
  \color{red}d_{11} &amp; t_{10} &amp; t_{9} &amp; t_{8} &amp; t_{7}\\
  \hdashline
  \color{red}d_{12} &amp; d_{11} &amp; t_{10} &amp; t_{9} &amp; t_{8}\\
  \color{red}d_{13} &amp; d_{12} &amp; d_{11} &amp; t_{10} &amp; t_{9}\\
  \end{array}\right]
\ast&amp;&amp;  =
c_{1}
\begin{bmatrix}
\color{red}t_{1} \\
\color{red}t_{2} \\
\color{red}t_{3} \\
\color{red}t_{4} \\
\hdashline
\color{red}t_{5} \\
\color{red}t_{6} \\
\color{red}t_{7} \\
\color{red}t_{8} \\
\color{red}t_{9} \\
\color{red}t_{10} \\
\color{red}d_{11} \\
\hdashline
\color{red}d_{12} \\
\color{red}d_{13} \\
\end{bmatrix}
+
\begin{bmatrix}
{r_{2}} \\
{r_{3}} \\
{r_{4}} \\
{r_{5}} \\
\hdashline
{r_{6}} \\
{r_{7}} \\
{r_{8}} \\
{r_{9}} \\
{r_{10}} \\
{r_{11}} \\
{r_{12}} \\
\hdashline
{r_{13}} \\
{r_{14}} \\
\end{bmatrix}
\end{align*}\]</span></p>
<p>This makes sense. If most of the energy was in the later channel taps and the real channel is bigger than the model, we’ll indeed want to use a slightly later slice of the received symbols!</p>
<h2 id="conclusions">conclusions <a href="#conclusions" class="section">#</a></h2>
<p>If we have a slightly larger channel than the model, we can use the energy distribution – which we can find out via a simple correlation, if our training sequences are reasonable (its autocorrelation “sharp”, mostly zero except at zero delay <a href="#fn1" class="footnote-ref" id="fnref1" role="doc-noteref"><sup>1</sup></a>) – to figure out where on the signal to run the least-squares estimation. The amount of error presumably depends on the characteristics of the channel itself. Also, there are more advanced methods for channel estimation, most notably MMSE, which requires knowledge (or estimation) of noise and channel statistics. I can understand how one could estimate the noise statistics (if we have strong enough symbols we can wipe off the noise), but it’s slightly unclear to me how one estimates the channel statistics….if one’s trying to…estimate the channel? If you want to explain how this gets done in real-world systems, I would be delighted to hear about it!</p>
<p>I think what I’ll do next is try to formalize and write code for the time/frequency offset estimation, and get that correctly cueing the channel estimation on the right part of the signal. The goal of this series is to do a survey of the <em>all</em> the necessary “minimally viable” signal processing elements that compose a reasonable (similar data rates, similar channel properties, similar performance) GSM-ish receiver, not to explore <em>all</em> the possible methods (there are many of them, and people keep coming up with more!) for each signal processing block.</p>
<section id="footnotes" class="footnotes footnotes-end-of-document" role="doc-endnotes">
<hr />
<ol>
<li id="fn1"><p>We send <span class="math inline">\(TS\)</span>, and receive <span class="math inline">\(TS \ast chan\)</span> (<span class="math inline">\(TS\)</span> convolved with the channel impulse response). If we want to estimate the channel with a simple correlation, the receiver computes <span class="math inline">\((TS \ast chan) \star TS\)</span>, where <span class="math inline">\(\star\)</span> is the <em>correlation</em> operator. The properties of convolution and correlation let us rewrite that as <span class="math inline">\(chan \ast (TS \star TS)\)</span> – the channel impulse response itself, correlated with the autocorrelation of the training sequence. The closer the training sequence autocorrelation is to zero (besides at zero delay), the more accurate the simple correlation method’s estimate of the impulse response.<a href="#fnref1" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
</ol>
</section>]]></summary>
</entry>
<entry>
    <title>I have the power of equations!</title>
    <link href="https://softminus.org/posts/equations.html" />
    <id>https://softminus.org/posts/equations.html</id>
    <published>2023-04-12</published>
    <updated>2023-04-12T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="i-have-the-power-of-equations">I have the power of equations!</h1>
<p>we use the code from <a href="https://rebeccaskinner.net/posts/2021-01-31-hakyll-syntax-highlighting.html">these</a> two <a href="https://laurentrdc.xyz/posts/making-this-website.html">posts</a> to enable mathjax and syntax highlighting with hakyll (errors, omissions, and indentation butchery below are my own, I am not (yet?) a professional haskell programmer)</p>
<div class="sourceCode" id="cb1"><pre class="sourceCode haskell"><code class="sourceCode haskell"><span id="cb1-1"><a href="#cb1-1" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-2"><a href="#cb1-2" aria-hidden="true" tabindex="-1"></a><span class="ot">syntaxHighlightingStyle ::</span> <span class="dt">Style</span></span>
<span id="cb1-3"><a href="#cb1-3" aria-hidden="true" tabindex="-1"></a>syntaxHighlightingStyle <span class="ot">=</span> haddock</span>
<span id="cb1-4"><a href="#cb1-4" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-5"><a href="#cb1-5" aria-hidden="true" tabindex="-1"></a>mathExtensions <span class="ot">=</span> </span>
<span id="cb1-6"><a href="#cb1-6" aria-hidden="true" tabindex="-1"></a>  [ <span class="dt">Ext_tex_math_dollars</span></span>
<span id="cb1-7"><a href="#cb1-7" aria-hidden="true" tabindex="-1"></a>  , <span class="dt">Ext_tex_math_double_backslash</span></span>
<span id="cb1-8"><a href="#cb1-8" aria-hidden="true" tabindex="-1"></a>  , <span class="dt">Ext_latex_macros</span></span>
<span id="cb1-9"><a href="#cb1-9" aria-hidden="true" tabindex="-1"></a>  ]</span>
<span id="cb1-10"><a href="#cb1-10" aria-hidden="true" tabindex="-1"></a>codeExtensions <span class="ot">=</span> </span>
<span id="cb1-11"><a href="#cb1-11" aria-hidden="true" tabindex="-1"></a>  [ <span class="dt">Ext_fenced_code_blocks</span></span>
<span id="cb1-12"><a href="#cb1-12" aria-hidden="true" tabindex="-1"></a>  , <span class="dt">Ext_backtick_code_blocks</span></span>
<span id="cb1-13"><a href="#cb1-13" aria-hidden="true" tabindex="-1"></a>  , <span class="dt">Ext_fenced_code_attributes</span></span>
<span id="cb1-14"><a href="#cb1-14" aria-hidden="true" tabindex="-1"></a>  ]</span>
<span id="cb1-15"><a href="#cb1-15" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-16"><a href="#cb1-16" aria-hidden="true" tabindex="-1"></a>defaultExtensions <span class="ot">=</span> writerExtensions defaultHakyllWriterOptions</span>
<span id="cb1-17"><a href="#cb1-17" aria-hidden="true" tabindex="-1"></a>newExtensions <span class="ot">=</span> <span class="fu">foldr</span> enableExtension defaultExtensions (mathExtensions <span class="op">&lt;&gt;</span> codeExtensions)</span>
<span id="cb1-18"><a href="#cb1-18" aria-hidden="true" tabindex="-1"></a></span>
<span id="cb1-19"><a href="#cb1-19" aria-hidden="true" tabindex="-1"></a>pandocWriterSoupedUpOptions <span class="ot">=</span> defaultHakyllWriterOptions {</span>
<span id="cb1-20"><a href="#cb1-20" aria-hidden="true" tabindex="-1"></a>                            writerHTMLMathMethod <span class="ot">=</span> <span class="dt">MathJax</span> <span class="st">&quot;&quot;</span>, </span>
<span id="cb1-21"><a href="#cb1-21" aria-hidden="true" tabindex="-1"></a>                            writerExtensions <span class="ot">=</span> newExtensions, </span>
<span id="cb1-22"><a href="#cb1-22" aria-hidden="true" tabindex="-1"></a>                            writerH</span>
<span id="cb1-23"><a href="#cb1-23" aria-hidden="true" tabindex="-1"></a><span class="co">-- [...]           </span></span>
<span id="cb1-24"><a href="#cb1-24" aria-hidden="true" tabindex="-1"></a>  create [<span class="st">&quot;css/syntax.css&quot;</span>] <span class="op">$</span> <span class="kw">do</span></span>
<span id="cb1-25"><a href="#cb1-25" aria-hidden="true" tabindex="-1"></a>    route idRoute</span>
<span id="cb1-26"><a href="#cb1-26" aria-hidden="true" tabindex="-1"></a>    compile <span class="op">$</span> <span class="kw">do</span></span>
<span id="cb1-27"><a href="#cb1-27" aria-hidden="true" tabindex="-1"></a>      makeItem <span class="op">$</span> styleToCss syntaxHighlightingStyle</span></code></pre></div>
<p>and without further ado, we have</p>
<h3 id="the-equations">the equations! <a href="#the-equations" class="section">#</a></h3>
<p><span class="math display">\[\begin{eqnarray}
    x+1 = 2 \\
    y+2 = 3 
\end{eqnarray}\]</span></p>
<h3 id="matrices">matrices! <a href="#matrices" class="section">#</a></h3>
<p><span class="math display">\[\begin{bmatrix}
1 &amp; 2 &amp; 3\\
a &amp; b &amp; c
\end{bmatrix}\]</span></p>
<h3 id="and-even-extremely-fancy-matrices">and even extremely fancy matrices! <a href="#and-even-extremely-fancy-matrices" class="section">#</a></h3>
<p>the code for this was inspired from <a href="https://tex.stackexchange.com/a/423536">this</a> stackexchange post:</p>
<p><span class="math display">\[\begin{align*}
&amp; \begin{bmatrix}
  m_{0} &amp; m_{1} &amp; m_{2} &amp; m_{3} \\
  m_{4} &amp; m_{5} &amp; m_{6} &amp; m_{7} \\
  m_{8} &amp; m_{9} &amp; m_{10} &amp; m_{11} \\
  m_{12} &amp; m_{13} &amp; m_{14} &amp; m_{15}
  \end{bmatrix}
\\
  \begin{bmatrix}
  v_{0} &amp; v_{1} &amp; v_{2} &amp; v_{3}
  \end{bmatrix}
&amp; \mspace{5mu}
  \bigl[\begin{matrix}
{r_{0}} &amp;
  \mspace{15mu}
{r_{1}} &amp;
  \mspace{15mu}
{r_{2}} &amp;
  \mspace{15mu}
{r_{3}}
  \end{matrix}
  \mspace{15mu}
  \bigr]
\end{align*}\]</span></p>]]></summary>
</entry>
<entry>
    <title>Sunday linkpost</title>
    <link href="https://softminus.org/posts/linkpost-15-Jan-2023.html" />
    <id>https://softminus.org/posts/linkpost-15-Jan-2023.html</id>
    <published>2023-01-15</published>
    <updated>2023-01-15T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="sunday-linkpost">Sunday linkpost</h1>
<p><span class="abstract">Here’s some interesting papers and webpages that I have hanging around in open browser tabs.</span> Better to have them here than languishing in browser tabs/history/bookmarks!</p>
<h2 id="signal-processing-stuff">signal processing stuff <a href="#signal-processing-stuff" class="section">#</a></h2>
<h3 id="array-and-spatial-processing">array and spatial processing <a href="#array-and-spatial-processing" class="section">#</a></h3>
<ul>
<li>two sets of lecture notes on spatial/array processing that look at different criteria (zero forcing vs error minimization) and deterministic vs stochastic (which I think is a synonym for Bayesian) approaches
<ul>
<li>course: <a href="https://www.es.ele.tue.nl/education/5me00/handouts/5me00_04_spatialprocessing.pdf">5ME00</a></li>
<li>course: <a href="https://sps.ewi.tudelft.nl/Education/courses/et4147/sheets/beam_leus2.pdf">ET4147</a></li>
</ul></li>
<li><a href="https://sps.ewi.tudelft.nl/Education/courses/et4147/buckley.pdf">“Beamforming: a versatile approach to spatial filtering” by B.D. Van Veen; K.M. Buckley</a></li>
<li>The entire set of notes from the NATO “Advanced Radar Systems, Signal and Data Processing” (<a href="https://www.sto.nato.int/publications/STO%20Educational%20Notes/Forms/Educational%20Notes%20Document%20Set/docsethomepage.aspx?ID=2052&amp;FolderCTID=0x0120D5200078F9E87043356C409A0D30823AFA16F60300099FA443AE6E08499A57A0FBE0134F20&amp;List=44a8f49d-e481-458a-91b4-212a9605bd9e&amp;RootFolder=%2Fpublications%2FSTO%20Educational%20Notes%2FRTO%2DEN%2DSET%2D086bis">RTO-EN-SET-086bis</a>) lecture series</li>
</ul>
<h3 id="spicy-signal-processing-beyond-circularity-and-linearity">spicy signal processing: beyond circularity and linearity <a href="#spicy-signal-processing-beyond-circularity-and-linearity" class="section">#</a></h3>
<ul>
<li><p><a href="https://cyclostationarity.com/wp-content/uploads/2021/08/Cyclic-Wiener-Filtering.pdf">“Cyclic Wiener filtering: Theory and Model”</a> by Gardner</p>
<ul>
<li>normal filters add up multiple copies of the same signal, but time-offset</li>
<li>array processing adds up multiple copies of the same signal, but <em>space</em>-offset</li>
<li>FRESH (FREquency SHift) filters add up multiple copies of the same signal, but <em>frequency</em>-offset</li>
<li>this is useful because many signals (like communication/radar RF signals) have redundancy/correlation in their frequency domain (a property called cyclostationarity)</li>
</ul></li>
<li><p><a href="https://hal.science/hal-02469905/document">“Noncircularity exploitation in Signal Processing Overview and Application to Radar”</a> by F. Barbaresco, Pascal Chevalier; about widely linear processing/filtering/estimation</p>
<ul>
<li>a lot of time it’s justified to assume that complex-valued signals through complex-valued systems behave the same as real valued signals and systems (and using the same sort of filters / estimators you’d use for real-valued everythings)</li>
<li>pretending that complex signals work just like real signals depends on an assumption called “second-order circularity”</li>
<li>second-order circularity doesn’t always hold!</li>
<li>for instance if the signal (prior to passing through the channel) only takes a real value (like -1 or 1, like with a BPSK), then there’s a <em>fundamental asymmetry</em> between the inphase and quadrature channels, and that violates the second-order circularity assumption.</li>
<li>note: a symmetric QAM signal (modulated with random data, as always) is itself not circularly symmetric (add a phase offset and the little square lattice gets tilted) but it <em>is</em> second-order circular</li>
<li>if second-order circularity doesn’t hold and you process the received signal in a way that can’t tease apart the asymmetry then you are leaving signal on the table.</li>
<li>in the case where the modulated signal is only real-valued (or can be transformed to be only real-valued) that special signal structure morally lets you get a sort of <em>processing gain</em> because you know that any variation in the complex axis is noise/interference/etc:
<img src="../images/linkpost-15-Jan-2023/saic.png" alt="processing gain" /></li>
<li>a linear filter looks like <span class="math inline">\(y = h\cdot x\)</span> (<span class="math inline">\(y\)</span> output, <span class="math inline">\(h\)</span> coefficients, <span class="math inline">\(x\)</span> input), the <em>widely-linear</em> model looks like <span class="math inline">\(y = g \cdot x + h \cdot x^*\)</span> (<span class="math inline">\(y\)</span> output, <span class="math inline">\(h\)</span> and <span class="math inline">\(g\)</span> coefficients, <span class="math inline">\(x\)</span> input, and <span class="math inline">\(x^*\)</span> the complex conjugate of <span class="math inline">\(x\)</span>) – so it’s linear in both <span class="math inline">\(x\)</span> and its complex conjugate <span class="math inline">\(x^*\)</span></li>
<li>as i understand it, this lets the system do stuff like “take only the real part of the signal” (because the noise all lives in the imaginary axis) but in a principled way</li>
</ul></li>
<li><p><a href="https://hal.science/hal-01756249/document">“Widely Linear Estimation with Complex Data”</a>, by Bernard Picinbono, Pascal Chevalier, also about widely linear processing</p></li>
<li><p><a href="https://ieeexplore.ieee.org/document/1231649">“Receivers with widely linear processing for frequency-selective channels”</a> by H. Gerstacker; R. Schober; A. Lampe: more about widely linear processing</p></li>
<li><p>Widely linear filtering isn’t new: <a href="https://ieeexplore.ieee.org/document/1054330">“Conjugate linear filtering”</a> by W. Brown; R. Crane is from 1969!</p></li>
<li><p><a href="https://hal.science/hal-01702741/document">“Enhanced widely linear filtering to make quasi-rectilinear signals almost equivalent to rectilinear ones for SAIC/MAIC”</a> by Pascal Chevalier, Rémi Chauvat, Jean-Pierre Delmas</p>
<ul>
<li>we saw earlier that if a signal (as transmitted) has a special form and only lives in the reals (like BPSK or a PAM), this allows for a form of processing gain at the receiver</li>
<li>even more interestingly, this allows for <em>signal separation</em> / <em>interference cancellation</em> (if both the desired and interfering signal are of this form): the receiver can adjust the phase of the received signal until the desired signal lives only on the reals (this is a linear operation), and <em>trash</em> the imaginary component of the signal altogether</li>
<li>the real-world realization is more complex since there are two channels (desired signal channel, interferer signal channel) that need to be taken into account, but this actually works: it’s called “single antenna interference cancellation” (SAIC)</li>
<li>some papers about SAIC:
<ul>
<li><a href="https://www.sciencedirect.com/science/article/abs/pii/S0165168400000402">“Performance bounds for cochannel interference cancellation within the current GSM standard”</a></li>
<li>“A Single Antenna Interference Cancellation Algorithm for Increased GSM Capacity”</li>
<li>“Single antenna interference cancellation (SAIC) for GSM networks”</li>
</ul></li>
<li>the titles of those papers implies that this is deployed for GSM networks, which notably uses GMSK, which is definitely not BPSK nor a PAM</li>
<li>however, it turns out we can use this “single antenna interference cancellation” for certain modulations that aren’t BPSK or a PAM, with an additional step: the infamous “derotation”, which converts an MSK into BPSK, and converts GMSK into an almost-BPSK (“almost” because of the second Laurent pulse)</li>
<li>this paper goes well beyond the standard SAIC; looking into both widely-linear filtering <em>and</em> FRESH filtering, in order to exploit the spectral structure of the signal of interest</li>
</ul></li>
<li><p>two books i found that might be useful later</p>
<ul>
<li><a href="https://onlinelibrary.wiley.com/doi/book/10.1002/9780470742624">“Complex Valued Nonlinear Adaptive Filters: Noncircularity, Widely Linear and Neural Models”</a></li>
<li><a href="https://onlinelibrary.wiley.com/doi/book/10.1002/9780470575758">“Adaptive Signal Processing: Next Generation Solutions”</a></li>
</ul></li>
</ul>
<h2 id="hardware">hardware <a href="#hardware" class="section">#</a></h2>
<ul>
<li><a href="https://old.reddit.com/r/RTLSDR/comments/s5k4ey/wideband_sdr_platform_on_a_budget_update_2/">Wideband SDR Platform on a Budget, Update # 2, Observations of Starlink Downlink w/ Software Defined Radio</a> by reddit user <a href="https://old.reddit.com/user/christianhahn09">christianhahn09</a>: amazing SDR built with devboards for:
<ul>
<li>TI ADC16DX370 dual-channel, 370 Msps, 16-bit ADC</li>
<li>ADI LTC5594 wideband I/Q demodulator</li>
<li>Xilinx Kintex-7 KC705 FPGA</li>
</ul>
and for the local oscillator:
<ul>
<li>a Windfreak SynthHD PRO v2, dual channel RF signal generator</li>
</ul>
I love the use of an SFX (it’s like ATX but smaller) power supply along with a DC/DC and low-noise LDOs to power all the other hardware, it’s a very elegant solution, and apparently the noise isn’t much of an issue.</li>
</ul>
<h2 id="software-engineering-stuff">software engineering stuff <a href="#software-engineering-stuff" class="section">#</a></h2>
<ul>
<li><p>the reduceron reconfigured and re-evaluated (<a href="https://www.cs.york.ac.uk/fp/reduceron/jfp-reduceron.pdf">paper</a> and <a href="https://www.cs.york.ac.uk/fp/reduceron/icfp2010talk.pdf">slides</a>) and <a href="https://www-users.york.ac.uk/~mt540/graceful-ws/slides/Stewart.pdf">Graph Reduction Hardware Revisited</a>: a microarchitecture that does graph reduction</p></li>
<li><p>some stuff about haskell’s STG-machine and execution model:</p>
<ul>
<li><a href="http://www.scs.stanford.edu/11au-cs240h/notes/ghc-slides.html">“A Haskell Compiler”</a> by David Terei</li>
<li>SPJ’s <a href="https://www.microsoft.com/en-us/research/wp-content/uploads/1992/04/spineless-tagless-gmachine.pdf">Implementing Lazy Functional Languages on Stock Hardware: The Spineless Tagless G-machine</a></li>
<li><a href="https://takenobu-hs.github.io/downloads/haskell_lazy_evaluation.pdf">“Lazy evaluation illustrated for Haskell divers”</a> by <a href="https://takenobu-hs.github.io/downloads/">Takenobu Tani</a>: “The STG-machine is the marriage of Lambda calculus and Turing machine”</li>
</ul></li>
</ul>
<h3 id="parsing">parsing <a href="#parsing" class="section">#</a></h3>
<ul>
<li><a href="https://www.chajed.io/papers/everparse:usenix-sec2019.pdf">“EverParse: Verified Secure Zero-Copy Parsers for Authenticated Message Formats”</a>:
<ul>
<li>real-world data formats are rife with protocol-meaningful numbers (indices/offsets/counts/lengths/ranges), and therefore context-sensitive</li>
<li>trying to parse them with hand-written code often leads to parsing/semantic validation/action code being blended together in unprincipled and insecure ways (“shotgun parsers”)</li>
<li>using parsers generated from language descriptions would improve the situation; except that most parser generators are meant for context-free grammars (stuff that looks like a programming language, not an IP packet or a PDF file)</li>
<li><a href="https://project-everest.github.io/everparse/3d.html">EverParse</a> addresses this task for TLVish (tag length value) formats</li>
</ul></li>
<li><a href="https://arxiv.org/pdf/1902.08272.pdf">The computational power of Parsing Expression Grammars</a></li>
<li><a href="https://digitalcommons.dartmouth.edu/cgi/viewcontent.cgi?article=1222&amp;context=senior_theses">Implementation and Optimization of PEG Parsers for Use on FPGAs</a></li>
<li><a href="http://spw20.langsec.org/papers/parsley-langsec2020.pdf">Research Report: The Parsley Data Format Definition Language</a></li>
<li><a href="https://arxiv.org/pdf/2001.04457.pdf">A Verified Packrat Parser Interpreter for Parsing Expression Grammars</a></li>
</ul>
<h2 id="random-stuff">random stuff <a href="#random-stuff" class="section">#</a></h2>
<ul>
<li><a href="https://www.overleaf.com">overleaf</a>: in-browser LaTeX editor/typesetter</li>
<li><a href="https://cohost.org/0xabad1dea/post/532407-div-aria-describedb">0xabadidea’s backlog post</a> – which inspired me to do this poast</li>
<li><a href="https://vitabenes.com/ask-questions">ask useful questions</a></li>
<li><a href="https://mathstodon.xyz/@tao/109451634735720062">some math tricks, poasted by Terence Tao</a></li>
<li><a href="https://tbenthompson.com/post/maintaining_momentum/">maintaining momentum</a></li>
<li><a href="https://www.benkuhn.net/writing/">Why and how to write things on the Internet</a></li>
<li><a href="https://e2eml.school/transformers.html">Transformers from scratch</a></li>
<li><a href="https://www.perplexity.ai/sql">bird SQL</a></li>
<li><a href="https://vaughntan.org/notknowing">not knowing</a></li>
</ul>
<h2 id="other-peoples-websites-i-liked-its-nice-seeing-what-other-people-get-up-to-with-static-site-generators">other people’s websites i liked (it’s nice seeing what other people get up to with static site generators) <a href="#other-peoples-websites-i-liked-its-nice-seeing-what-other-people-get-up-to-with-static-site-generators" class="section">#</a></h2>
<ul>
<li><a href="https://reflexive.space/about/">reflexive.space</a></li>
<li><a href="https://susam.net/about.html">susam.net</a></li>
<li><a href="https://laurentrdc.xyz/posts/making-this-website.html">laurentrdc.xyz</a></li>
</ul>]]></summary>
</entry>
<entry>
    <title>GSM receiver blocks: rough notes on coarse timing estimation</title>
    <link href="https://softminus.org/posts/coarse-timing-notes.html" />
    <id>https://softminus.org/posts/coarse-timing-notes.html</id>
    <published>2023-01-05</published>
    <updated>2023-01-05T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-rough-notes-on-coarse-timing-estimation">GSM receiver blocks: rough notes on coarse timing estimation</h1>
<p>In this GSMish scenario we don’t actually need pinpoint/“fine” timing/phase accuracy, since a good enough Viterbi demodulator effectively “cleans up” remaining timing/phase offset as long as it’s fed with an accurate enough channel estimate (especially if it’s able to <em>update</em> its channel estimate).</p>
<h3 id="small-timing-offsets-dont-matter-too-much-for-this-demodulator">small timing offsets don’t matter too much for this demodulator <a href="#small-timing-offsets-dont-matter-too-much-for-this-demodulator" class="section">#</a></h3>
<p>In a simplistic scenario, if our channel looks like <span class="math inline">\([1,1]\)</span>, it doesn’t matter if the channel estimator outputs <span class="math inline">\([1,1,0,0,0,0,0,0]\)</span> or <span class="math inline">\([0,1,1,0,0,0,0,0]\)</span> (here we are using the classic GSM design choice of making our channel estimator handle channels of length 8) or anything up to <span class="math inline">\([0,0,0,0,0,0,1,1]\)</span> – we get the same results at the end. If we’re misaligned enough to get <span class="math inline">\([0,0,0,0,0,0,0,1]\)</span> we <em>are</em> leaving half the energy in the received signal on the table, so we do want as much energy possible in the actual channel’s impulse response to appear within the channel estimate the demodulator is given.</p>
<p>Of course, with a more realistic case, the actual channel won’t be just two symbols long, this <em>is</em> terrestrial radio, not a PCB trace / transmission line nor an airplane-to-satellite radio channel :p</p>
<h3 id="coarse-timing-offsets-matter-a-lot-to-the-channel-estimator">coarse timing offsets matter a lot to the channel estimator <a href="#coarse-timing-offsets-matter-a-lot-to-the-channel-estimator" class="section">#</a></h3>
<p>In the case where the physical channel has a length commensurate with the channel length designed in the channel estimator / demodulator, we want to make sure that our <a href="least-squares.html">least-squares channel estimator</a> gets aimed at the <a href="least-squares-indices.html">right place</a> in the burst – if it ingests lots of signal affected by unknown data (as opposed to known training sequence data affected by an unknown channel), its output will be kinda garbage.</p>
<h3 id="form-is-emptiness-cross-correlation-is-matched-filtering">form is emptiness, cross-correlation is matched filtering <a href="#form-is-emptiness-cross-correlation-is-matched-filtering" class="section">#</a></h3>
<p>We’d be at an impasse<a href="#fn1" class="footnote-ref" id="fnref1" role="doc-noteref"><sup>1</sup></a> if the least squares estimator was our only tool here, but we have a simpler tool that’s more forgiving of misalignments: cross-correlating the received signal against the modulated training sequence. Another way of thinking of this is that we’re running our received signal through a matched filter (with the reference/template signal the modulated training sequence) – it’s literally the same convolution.</p>
<p>Doing this gives us something that looks like this:</p>
<p><img src="../images/coarse-timing-notes/cross-correlation.png" /></p>
<p>Using the <a href="https://en.wikipedia.org/wiki/Visual_inspection#Humorous_terminology">Mk I eyeball</a>, it’s pretty clear where the training sequence lives – at the tallest peak.</p>
<p>For implementation in software or gateware, we can encode this logic pretty easily: calculate the correlation, then iterate and look for the biggest peak. However, we notice that there’s a bunch of spurious peaks all around, and it’d be quite bad if we accidentally matched on a spurious peak: the channel estimate would be garbage, and the output of the demodulator would be beyond useless, since it wouldn’t even be starting off at the right spot in the signal.</p>
<p>We can avoid this failure case by running the correlation on a smaller window, which reduces the chances of hitting a false correlation peak. We determine the position of the smaller window using our prior knowledge of the transmitted signal structure – where the training sequence lives relative to the start of the signal – and an estimator to determine when the start of the signal happens.</p>
<p>It’s pretty easy to determine when the start of the signal happens: square/sum each incoming I/Q pair to get a magnitude, and keep a little window of those magnitudes and when their sum exceeds a threshold, well, that’s when the signal started.</p>
<p>We use this to narrow down the possible locations for the training sequence in the received signal. However, we still should run the correlation since this energy-detection start-of-signal estimator has more variance than the correlation-based timing offset estimator.</p>
<h3 id="why-training-sequences-are-like-that">why training sequences are like that <a href="#why-training-sequences-are-like-that" class="section">#</a></h3>
<p>Incidentally, the GSM training sequences (and lots of training sequences in other well-designed wireless communications systems) have interesting properties:</p>
<ul>
<li>their power spectra are approximately flat</li>
<li>their autocorrelation have a tall narrow peak that approximates an impulse, and has much less energy elsewhere</li>
</ul>
<p>The former is a desired property since we want to evenly probe the frequency response of the bandpass channel. Spreading the training sequence’s power unevenly (lots of power in one part of the passband and much less in another part of the passband) causes a worse signal-to-noise<a href="#fn2" class="footnote-ref" id="fnref2" role="doc-noteref"><sup>2</sup></a> ratio in the parts of the passband with less training sequence power. It’s a zero-sum affair since the transmitter has finite transmit power.</p>
<p>The autocorrelation property not only lets us use these training sequences for time synchronization, but it lets us use correlation as a rough channel impulse response estimate. If we’re satisfied with a very suboptimal receiver, we can just use the correlation as our channel estimate. However, least-squares generally will give us a more accurate channel impulse response, since the autocorrelation of the training sequence is not 1 at zero lag and 0 elsewhere – there’s little sidelobes:</p>
<p><img src="../images/coarse-timing-notes/autocorrelation-TS.png" /></p>
<h3 id="truck-correlation-its-like-auto-correlation-but-with-18-wheels">truck-correlation (it’s like auto-correlation but with 18 wheels) <a href="#truck-correlation-its-like-auto-correlation-but-with-18-wheels" class="section">#</a></h3>
<p>If you don’t have a good intuition for what a narrow autocorrelation does here, you can develop one by going to a loading dock or a construction site and paying attention when big trucks or earthmoving equipment back up. See, those big rigs are required to have a <a href="https://en.wikipedia.org/wiki/Back-up_beeper">back-up beeper</a> to warn bystanders that the driver is backing up and can’t see well what’s behind the vehicle.</p>
<h4 id="pure-tone-easy-to-detect-hard-to-localize">pure tone: easy to detect, hard to localize <a href="#pure-tone-easy-to-detect-hard-to-localize" class="section">#</a></h4>
<p>There’s two common types of back-up beeper, and unfortunately the more common kind outputs a series of beeps of a single pure tone (without changing frequency between beeps). If you close your eyes and only use that sound to determine where the truck is, you’ll find it’s quite a difficult task: it seems like the sound is coming from <em>everywhere</em>! The brain has a <a href="https://en.wikipedia.org/wiki/Sound_localization#Sound_localization_by_the_human_auditory_system">variety of mechanisms to localize sources of sound</a>, and besides the ultra-basic “find which ear is receiving the loudest signal” method many of them kinda boil down to doing cross-correlations of variously-delayed versions of the left ear’s signal against variously-delayed versions of the right ear’s signal, and looking for correlation peaks. Seems familiar!</p>
<p>Unfortunately, the pure sine tone is the <em>worst</em> possible signal for this, since there’ll be tons of correlation peaks (each oscillation of the sine wave is identical to its precursor and successor), and if there’s audio-reflective surfaces around you and the truck, there’ll be tons of echoes too. Ambiguities galore! More spurs than a cowboy convention!</p>
<p>Ironically, <strong>the most useful</strong> (for angle-of-arrival localization) <strong>part of the pure-tone truck beeper’s signal is the moment the beep starts</strong><a href="#fn3" class="footnote-ref" id="fnref3" role="doc-noteref"><sup>3</sup></a>, since the precursor is <em>zero</em> – the rest of the beep is comparatively useless for localization (an estimation task) but extremely useful for knowing that there’s indeed a truck <strong>somewhere in the neighborhood</strong> backing up (a detection task). The start and end of the beep are the most spectrally rich part of the beeper’s output, and <a href="https://en.wikipedia.org/wiki/Fourier_transform#Uncertainty_principle">this is indeed what we expect</a>.</p>
<p>The pure sine wave is the <em>easiest</em> possible signal to detect (with our friend the matched filter), but the <em>worst</em> possible signal for localization; and this irony is why you can hear truck back-up beepers from <em>uselessly</em> far away but can’t easily tell which truck is backing up.</p>
<h4 id="white-noise-hard-to-detect-easy-to-localize">white noise: hard to detect, easy to localize <a href="#white-noise-hard-to-detect-easy-to-localize" class="section">#</a></h4>
<p>Fortunately, there’s truck back-up beepers that output sounds far more amenable to localization: little bursts of white noise. If you haven’t heard those, you can find a youtube video of those in action, play it on your computer, and try and localize your <em>computer’s speakers</em> with your eyes closed.</p>
<p>You’ll notice that this is basically the optimal signal if you want to do angle-of-arrival estimation with delays and correlations – there’s only one correlation peak, and it’s exactly where you want it. It’s also <a href="https://en.wikipedia.org/wiki/Fourier_transform#Uncertainty_principle">extremely spectrally rich</a>, and it has to be, since spectrally poor signals have worse autocorrelation properties. It also has the advantage of “blending in” with other noise: on-and-off bursts of white noise get “covered up” by white noise (and become indistinguishable from white noise) very quickly, a pure tone is much more difficult to cover up with white noise.</p>
<p>This is what a good training sequence looks like: simple correlation gets you a passable estimate for the channel impulse response along with the timing offset, since the autocorrelation approximates an impulse. Also, the spectral richness ensures that all the frequency response of the bandpass channel is probed.</p>
<h3 id="a-viterbi-style-demodulator-is-a-controlled-combinatorial-explosion">A Viterbi-style demodulator is a controlled <a href="https://en.wikipedia.org/wiki/Combinatorial_explosion#Computing">combinatorial explosion</a> <a href="#a-viterbi-style-demodulator-is-a-controlled-combinatorial-explosion" class="section">#</a></h3>
<p>I don’t think there’s too much useful we can do with the coarse correlation-based channel estimation to enable a more accurate channel estimation with more advanced (least-squares) methods – I had imagined looking at the coarse correlation-based channel estimate and looking for a window with the most energy and then doing a least-squares channel estimate only on that window, but I don’t think that actually has realistic benefits.</p>
<p>However, that idea (focusing on where energy is concentrated in the channel impulse response) <em>does</em> point to a more fructuous<a href="#fn4" class="footnote-ref" id="fnref4" role="doc-noteref"><sup>4</sup></a> game we can play with channel impulse response: transforming the channel to <em>squash</em> the channel’s energy <a href="https://en.wikipedia.org/wiki/Minimum_phase#Minimum_phase_in_the_time_domain">as much as possible into the earlier channel coefficients</a>, and this is called “channel shortening”. Channel shortening is interesting because rather than having to <a href="gmsk-and-laurent.html#you-are-the-third-eye">delay decisions until the last possible moment</a>, we can commit to decisions earlier, which reduces the computational burden (and area/power requirements) on a Viterbi-style demodulator pretty significantly.</p>
<p>If the impulse of the channel is highly front-loaded into, say, the first 3 symbols, we force a decision after only 3 symbol periods, since the likelihood of something <em>after that</em> making us change our mind is very unlikely. We still keep track of the <em>effect</em> of our decisions for as long as the channel lasts, since otherwise we’ll be introducing actual error (even if we make all the right decisions) that’d be pretty harmless to avoid: once we made the decisions, figuring out their effect is as simple as feeding them through a channel-length FIR filter.</p>
<section id="footnotes" class="footnotes footnotes-end-of-document" role="doc-endnotes">
<hr />
<ol>
<li id="fn1"><p>maybe not, i am unsure if looking at the least square residuals would be enough to determine lack of time synchronization<a href="#fnref1" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn2"><p>which I am assuming to be distributed evenly across the passband<a href="#fnref2" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn3"><p>the moment the beep ends is theoretically the same but your ears are more desensed than when the beep <em>starts</em><a href="#fnref3" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn4"><p>I’ve <em>always</em> wanted to use that word (or rather, its French cognate <a href="https://en.wiktionary.org/wiki/fructueux#French">“fructueux”</a>) in writing.<a href="#fnref4" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
</ol>
</section>]]></summary>
</entry>
<entry>
    <title>GSM receiver blocks: least-squares channel estimation part 2: working out indices and lengths</title>
    <link href="https://softminus.org/posts/least-squares-indices.html" />
    <id>https://softminus.org/posts/least-squares-indices.html</id>
    <published>2022-12-19</published>
    <updated>2022-12-19T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-least-squares-channel-estimation-part-2-working-out-indices-and-lengths">GSM receiver blocks: least-squares channel estimation part 2: working out indices and lengths</h1>
<p>In <a href="least-squares.html">my post on least-squares channel estimation</a>, I had done some reasoning about which received samples can be safely (they’re not affected by unknown data) used for a least-squares channel estimation:</p>
<blockquote>
<p>The simple way to cope with this is to refuse to touch the first <span class="math inline">\(L-1\)</span> samples, and run our channel impulse response estimate over the <span class="math inline">\(M-L+1\)</span> samples after those. In GSM, this still gives us good performance, since for <span class="math inline">\(M=26\)</span>, <span class="math inline">\(L=8\)</span> we have 19 samples to estimate 8 channel coefficients. Note that we also can’t use the trailing (in the scan, the last 4 rows) received symbols, since those <em>also</em> are affected by unknown data.</p>
</blockquote>
<blockquote>
<p>Now, our convolution matrix has dimensions <span class="math inline">\(M-L+1\)</span> by <span class="math inline">\(L\)</span>, which makes sense, the only “trustworthy” (unaffected by unknown data) symbols are <span class="math inline">\(M-L+1\)</span> long, and we are convolving by a channel of length <span class="math inline">\(L\)</span>.</p>
</blockquote>
<blockquote>
<p>Figuring out the exact offset for <code>interference_rx_downsampled</code> has been a bit tricky, and I haven’t yet dived into writing the right correlation to estimate the exact timing offset required.</p>
</blockquote>
<p>From playing around some more in MATLAB with my source code, I realized I still don’t have a strong understanding of the exact offsets/indices/lengths at play here.</p>
<h2 id="lets-think-step-by-step-and-draw-pictures">let’s think step by step (and draw pictures) <a href="#lets-think-step-by-step-and-draw-pictures" class="section">#</a></h2>
<p>Rather than stare at algebraic expressions, we will draw pictures that speak to the physical meaning of the problem to help us reach expressions we actually <em>understand</em>.</p>
<p>We’ll take a generic GSM-like<a href="#fn1" class="footnote-ref" id="fnref1" role="doc-noteref"><sup>1</sup></a> transmitted burst that is composed of <span class="math inline">\(D_1\)</span> data bits, followed by a <em>midamble</em> of <span class="math inline">\(TS\)</span> training symbol bits, and <span class="math inline">\(D_2\)</span> data bits.</p>
<p>Here’s what the burst looks like. I’ve written down the indices (starting at 1) for the first and last bit in each section.</p>
<p><img src="../images/LS-indices/burst-structure.png" /></p>
<p>We note that all the lengths are correct:</p>
<ul>
<li>First data section is from <span class="math inline">\(1\)</span> to <span class="math inline">\(D_1\)</span> so its length is <span class="math inline">\(D_1-1+1 = D_1\)</span></li>
<li>Midamble is from <span class="math inline">\(D_1+1\)</span> to <span class="math inline">\(D_1 + TS\)</span> so its length is <span class="math inline">\(D_1+TS-(D_1+1)+1 = TS-1+1 = TS\)</span></li>
<li>Second data section is from <span class="math inline">\(D_1+TS+1\)</span> to <span class="math inline">\(D_1+TS+D_2\)</span> so its length is <span class="math inline">\(D_1 + TS + D_2 - (D_1 + TS + 1) + 1 = D_1-D_1 + TS - TS + D_2 - 1 + 1 = D_2\)</span>.</li>
<li>Total burst is from <span class="math inline">\(1\)</span> to <span class="math inline">\(D_1+TS+D_2\)</span> so its length is <span class="math inline">\(D_1 + TS + D_2 - 1 + 1 = D_1 + TS + D_2\)</span>.</li>
</ul>
<p>It’s clear how we can isolate any particular section of this burst before it has passed through a dispersive channel.</p>
<h3 id="notation-review-for-intervals-of-integers">notation review for <a href="https://en.wikipedia.org/wiki/Interval_(mathematics)#Integer_intervals">intervals of integers</a> <a href="#notation-review-for-intervals-of-integers" class="section">#</a></h3>
<ul>
<li><span class="math inline">\([1,5]\)</span> means “1 to 5, inclusive of the bounds (”closed”) on both sides”, and represents <span class="math inline">\({1,2,3,4,5}\)</span></li>
<li><span class="math inline">\((1,5)\)</span> means “1 to 5, non-inclusive of the bounds (”open”) on both sides”, and represents <span class="math inline">\({2,3,4}\)</span></li>
<li>We also can have left-closed right-open: <span class="math inline">\([1,5)\)</span> is inclusive of the <span class="math inline">\(1\)</span> but not of the <span class="math inline">\(5\)</span> so we have: <span class="math inline">\({1,2,3,4}\)</span></li>
<li>And likewise with left-open right-closed: <span class="math inline">\((1,5]\)</span> represents <span class="math inline">\({2,3,4,5}\)</span></li>
</ul>
<h2 id="addingb-channel-effects">adding<a href="#fn2" class="footnote-ref" id="fnref2" role="doc-noteref"><sup>2</sup></a> channel effects <a href="#addingb-channel-effects" class="section">#</a></h2>
<p>As the subtitle in the header insinuates, a dispersive channel is represented by a convolution. The structure of convolution tells us that each transmitted sample will affect multiple received samples, and the channel vector’s finite length tells us it’s not gonna be all of them.</p>
<p>We note that a single sample will be “smeared out” by a channel of length <span class="math inline">\(L\)</span> onto a span that’s <span class="math inline">\(L\)</span> long:</p>
<figure>
<img src="../images/LS-indices/single%20element%20convolution.png" alt="single element convolution, channel length L=5" />
<figcaption aria-hidden="true">single element convolution, channel length <span class="math inline">\(L=5\)</span></figcaption>
</figure>
<p>As for the indices, if this sample lives at index <span class="math inline">\(n\)</span>, the index of this little “span of influence” will be <span class="math inline">\([n, n+L-1]\)</span>. Why these indices?</p>
<ul>
<li>the starting index: We currently don’t care<a href="#fn3" class="footnote-ref" id="fnref3" role="doc-noteref"><sup>3</sup></a> about <em>absolute delays</em>, just what happens <em>inside the delay spread</em>. Remember the “ideal coaxial cable” thought experiment from <a href="gmsk-and-laurent.html#in-which-we-ignore-doppler">our last post</a>: the problem remains identical no matter how much ideal coaxial cable lives between our receiver antenna and our receiver frontend. We can therefore say that the input sample at index <span class="math inline">\(n\)</span> gets transmogrified by an “identity channel” (impulse response of <span class="math inline">\([1]\)</span>, it doesn’t change the signal at all) to be an output sample at index <span class="math inline">\(n\)</span> – no need to add any offset.</li>
</ul>
<ul>
<li><p>This means that the <strong>first</strong> output sample to be affected by our input sample will be at index <span class="math inline">\(n\)</span>, which justifies the left-closed (includes its boundary): <span class="math inline">\([n,\)</span></p></li>
<li><p>the ending index: If the “span of influence” is <span class="math inline">\(L\)</span> long, the last sample that is affected by our input sample will be at index <span class="math inline">\(n+L-1\)</span>. This justifies the right-closed (includes the boundary): <span class="math inline">\(,n+L-1]\)</span></p></li>
</ul>
<p>Going back to our “single element convolution” example, if the <span class="math inline">\(x\)</span> input sample lives at index <span class="math inline">\(10\)</span>, the first nonzero output sample lives at index <span class="math inline">\(10\)</span> by fiat. We observe nonzero output samples at <span class="math inline">\(11, 12, 13, 14\)</span> as well. Output sample <span class="math inline">\(15\)</span> and beyond are zero, as are samples <span class="math inline">\(9\)</span> and lower. This means that we have nonzero output at <span class="math inline">\([10, 14]\)</span>, and if we let <span class="math inline">\(n=10\)</span> and <span class="math inline">\(L=5\)</span> we get <span class="math inline">\([10, 10+5-1]=[10,14]\)</span>, which matches up with what we see.</p>
<h2 id="how-the-burst-structure-gets-preserved-by-the-convolution">how the burst structure gets preserved by the convolution <a href="#how-the-burst-structure-gets-preserved-by-the-convolution" class="section">#</a></h2>
<p>There is a definite structure to the transmitted burst: known data (the training sequence) sandwiched by unknown data. In realistic systems, the designers will select a training sequence length longer than any reasonable channel they expect to contend with, and so we expect:</p>
<ul>
<li>some received samples will be a function only of unknown data</li>
<li>some received samples will be a function of unknown data and training sequence bits</li>
<li>some received samples will be a function only of training sequence bits</li>
</ul>
<p>To figure out which received samples are which, let’s draw out what happens when our burst gets convolved with a channel of length <span class="math inline">\(L\)</span>. Each transmitted symbol will get “smeared out” onto an <span class="math inline">\(L\)</span>-long span, and we focus on the symbols at the boundaries of each section.</p>
<p>The center line represents what the receiver hears, and for clarity, we draw the unknown data sections above the center line and the training sequence below the center line.</p>
<figure>
<img src="../images/LS-indices/convolution%20parts.png" alt="D_1 = 11, TS=13, D_2=14, channel length L=5 case, full resolution here. The samples live on the lines of the graph paper, not in the spaces" />
<figcaption aria-hidden="true"><span class="math inline">\(D_1 = 11\)</span>, <span class="math inline">\(TS=13\)</span>, <span class="math inline">\(D_2=14\)</span>, channel length <span class="math inline">\(L=5\)</span> case, full resolution <a href="../images/LS-indices/convolution%20parts%20full%20res.png">here</a>. <strong>The samples live on the lines of the graph paper, not in the spaces</strong></figcaption>
</figure>
<p>Things are much more clear now!</p>
<ul>
<li><span class="math inline">\([1, D_1]\)</span>, with length <span class="math inline">\((D_1)-(1)+1=D_1\)</span>: the output’s only affected by the first data section</li>
<li><span class="math inline">\([D_1+1, D_1+L-1]\)</span> with length <span class="math inline">\((D_1+L-1)-(D_1+1)+1=L-1\)</span>: the output is affected by the first data section <em>and</em> the training sequence</li>
<li><span class="math inline">\([D_1+L, D_1+TS\)</span> with length <span class="math inline">\((D_1+TS)-(D_1+L)+1=D_1+TS-D_1-L+1=TS-L+1\)</span>: the output is only affected by the training sequence. <strong>This is the section we use for a least-squares channel estimate!</strong></li>
<li>[<span class="math inline">\(D_1+TS+1, D_1+TS+L-1]\)</span> with length <span class="math inline">\((D_1+TS+L-1) - (D_1+TS+1) + 1= D_1 + TS +L -1 -D_1 -TS -1 +1= L-1\)</span>: the output is affected by the training sequence <em>and</em> the second data section</li>
<li><span class="math inline">\([D_1+TS+L, D_1+TS+D_2+L-1]\)</span> with length <span class="math inline">\((D_1+TS+D_2+L-1) - (D_1+TS+L) + 1= D_1 +TS + D_2+L - 1 -D_1 -TS -L +1 = D_2\)</span>. This part is only affected by the second data section.</li>
</ul>
<p>Now let’s sum<a href="#fn4" class="footnote-ref" id="fnref4" role="doc-noteref"><sup>4</sup></a> up all those lengths to see if our work checks out: <span class="math inline">\((D_1) + (L-1) + (TS-L+1) + (L-1) + (D_2) = D_1 + L -1 +TS -L +1 +L -1 +D_2 = D_1 +D_2 +TS +L -1\)</span>. This is indeed what we get when we convolve a vector with length <span class="math inline">\(D_1+D_2+TS\)</span> (the total length of the burst as it’s transmitted) by a vector with length <span class="math inline">\(L\)</span> (the channel)!</p>
<p>As usual, if you notice an error in my work, I’d be very grateful if you could point it out to me.</p>
<section id="footnotes" class="footnotes footnotes-end-of-document" role="doc-endnotes">
<hr />
<ol>
<li id="fn1"><p>GSM’s “stealing bits” act like regular bits for modulation/demodulation, and the tail bit structure is not relevant for channel estimation (it will be relevant when we look at trellises).<a href="#fnref1" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn2"><p>or rather, convolving in<a href="#fnref2" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn3"><p>We will soon need to care about absolute delays to solve the <em>time synchronization</em> problem. Not the question of how to get synchronized to UTC or TAI, but rather figuring out when exactly we receive each burst. This is critical since for instance, if the time sync is incorrect, the channel estimator could end up being fed <em>modulated unknown data</em> rather than the midamble!<a href="#fnref3" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn4"><p>a sum to check our work, call that a check-sum :p<a href="#fnref4" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
</ol>
</section>]]></summary>
</entry>
<entry>
    <title>probability review problems</title>
    <link href="https://softminus.org/posts/problem-set-0.html" />
    <id>https://softminus.org/posts/problem-set-0.html</id>
    <published>2022-12-18</published>
    <updated>2022-12-18T00:00:00Z</updated>
    <summary type="html"><![CDATA[<p><a href="https://twitter.com/edgar_z_lin">Edgar Lin</a> wrote up some probability review problems for me to work through, and here they are (along with my solutions so far).</p>
<h2 id="probability-review-problems">probability review problems <a href="#probability-review-problems" class="section">#</a></h2>
<p><img src="../images/pset0/problems%201%20to%208.png" alt="problems 1 to 8" />
<img src="../images/pset0/problems%209%20to%2011.png" alt="problems 9 to 11" />
<img src="../images/pset0/problems%2012%20to%2013.png" alt="problems 12 to 13" />
<img src="../images/pset0/problems%2014.png" alt="problem 14" />
<img src="../images/pset0/problems%2015%20to%2016.png" alt="problems 15 to 16" />
<img src="../images/pset0/problems%2017%20to%2019.png" alt="problems 17 to 19" /></p>
<h2 id="my-solutions-so-far-ive-got-a-few-problems-left">my solutions (so far, i’ve got a few problems left) <a href="#my-solutions-so-far-ive-got-a-few-problems-left" class="section">#</a></h2>
<p><img src="../images/pset0/solution%201.png" alt="solution 1" />
<img src="../images/pset0/solution%202%203%204%207.png" alt="solution 2 3 4 7" />
<img src="../images/pset0/solution%205.png" alt="solution 5" />
<img src="../images/pset0/solution%206.png" alt="solution 6" />
<img src="../images/pset0/solution%208%209%20start.png" alt="solution 8 9 start" />
<img src="../images/pset0/solution%209%20continued.png" alt="solution 9 continued" />
<img src="../images/pset0/solution%2010%2011.png" alt="solution 10 11" />
<img src="../images/pset0/solution%2012%2013.png" alt="solution 13, 12 start" />
<img src="../images/pset0/solution%2012%202.png" alt="solution 12 2" />
<img src="../images/pset0/solution%2012%203.png" alt="solution 12 3" />
<img src="../images/pset0/solution%2012%204.png" alt="solution 12 4" />
<img src="../images/pset0/solution%2012%205.png" alt="solution 12 5" /></p>]]></summary>
</entry>
<entry>
    <title>GSM receiver blocks: GMSK and Laurent</title>
    <link href="https://softminus.org/posts/gmsk-and-laurent.html" />
    <id>https://softminus.org/posts/gmsk-and-laurent.html</id>
    <published>2022-12-08</published>
    <updated>2022-12-08T00:00:00Z</updated>
    <summary type="html"><![CDATA[<h1 id="gsm-receiver-blocks-gmsk-and-laurent">GSM receiver blocks: GMSK and Laurent</h1>
<p><span class="abstract">Not all modulation schemes have the zero-ISI property that RRC-filtered <a href="#fn1" class="footnote-ref" id="fnref1" role="doc-noteref"><sup>1</sup></a> linear modulations have. Continuous-phase modulations (like GMSK, which we’ll be looking at) generally introduce inter-symbol interference: if your receiver recovers symbols by slicing-and-thresholding the received-and-filtered signal, it will have degraded performance – even if its timing is perfect.</span></p>
<p>This doesn’t prevent us from making high-performance (approaching optimal) receivers for GMSK. If the transmitter has a direct line-of-sight to the receiver and there’s not much else in the physical environment to allow for alternate paths, the channel won’t have much dispersive effect. This lets us approximate the channel as an non-frequency-selective attenuation followed by additive white Gaussian noise. In this case, you can use the Laurent decomposition of the GMSK amplitude-domain waveform to make a more complex receiver that’s quite close to optimal.</p>
<p>The former case is common in aerospace applications: if an airplane/satellite is transmitting a signal to an airplane/satellite or to a ground station, there usually is a quite good line of sight between the two – with not many radio-reflective objects in between that could create alternate paths. The received signal will look very much like the transmitted signal, only much weaker.</p>
<p>If your transmitter and receiver antennae aren’t in the sky or in space, they’re probably surrounded by objects that can reflect radio waves. In fact, they might not even have <em>any</em> line of sight to each other at all! You can use your cell phone anywhere with service, not just anywhere you have a cellular base station within line of sight.</p>
<p>If you’ve ever spoken loudly in a quiet tunnel/cave/parking garage, you hear echoes – replicas of your voice, except delayed and attenuated. A similar phenomenon occurs when there’s multiple paths the radio waves can take from the transmitter to the receiver. Think of the channel as a tapped delay line: the receiver receives multiple copies of the signal superimposed on each other, with each copy delayed by the corresponding path delay and attenuated by the corresponding path loss.</p>
<h3 id="in-which-we-ignore-doppler">in which we ignore doppler <a href="#in-which-we-ignore-doppler" class="section">#</a></h3>
<p>Imagine an extreme case: sending symbols at <span class="math inline">\(1\)</span> symbol per second, and leaving the channel silent for <span class="math inline">\(1\)</span> second between each symbol. Let’s say we have four fixed paths with equal attenuation, with delays <span class="math inline">\(50\)</span>ms, <span class="math inline">\(100\)</span>ms, <span class="math inline">\(150\)</span>ms, and <span class="math inline">\(210\)</span>ms. The difference between the shortest path (the path that will start contributing its effect at the receiver the earliest) and the longest path (the path that takes the longest time to start contributing its effect at the receiver) is known as the “delay spread” and here, it’s <span class="math inline">\(210-50\)</span>ms<span class="math inline">\(=160\)</span>ms. Initially, receiver gets something very much non-constant: after each of the paths “get filled up”, they appear at the receiver, but only happens in the first <span class="math inline">\(160\)</span>ms of the symbol. However, after that <span class="math inline">\(160\)</span>ms, the channel reach equilibrium, and for the remaining <span class="math inline">\(1000\)</span>ms<span class="math inline">\(-160\)</span>ms<span class="math inline">\(=840\)</span>ms, the receiver receives a constant signal. If the receiver ignores the first <span class="math inline">\(160\)</span>ms of each symbol, it can ignore the multipath altogether!</p>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-delay-spread.png" alt="big T is the symbol length, small t is the delay spread" />
<figcaption aria-hidden="true">big <span class="math inline">\(T\)</span> is the symbol length, small <span class="math inline">\(t\)</span> is the delay spread</figcaption>
</figure>
<p>Note that the <em>absolute delay</em> of the paths does impacts the latency of the system, but it doesn’t impact how the channel corrupts the signal. You could imagine the same system, except that there’s 3,000,000 kilometers of ideal (doesn’t attenuate or change the signal, just delays it) coaxial cable between the transmitter and the transmit antenna. That’s gonna add 10 seconds<a href="#fn2" class="footnote-ref" id="fnref2" role="doc-noteref"><sup>2</sup></a> of delay, but it won’t alter the received signal at all.</p>
<p>This dynamic (symbol time much greater than delay spread) is why analog voice modulation doesn’t need fancy signal processing to cope with multipath. The limit of human hearing is 20 kilohertz, and <span class="math inline">\(c/(20kHz)=15\)</span> kilometers, which is pretty big – paths with multiple kilometers of additional distance are gonna be pretty attenuated and won’t be very significant to the receiver<a href="#fn3" class="footnote-ref" id="fnref3" role="doc-noteref"><sup>3</sup></a>.</p>
<p>The higher the data rate compared to the delay spread, the less you can ignore multipath. Increase the symbol rate to GSM’s <span class="math inline">\(270\)</span> kilosymbols per second, and we get <span class="math inline">\(c/(270kHz)=1\)</span> kilometer. Paths with hundreds of meters of additional distance aren’t negligible in lots of circumstances!</p>
<p>A high-performance demodulator has to function<a href="#fn4" class="footnote-ref" id="fnref4" role="doc-noteref"><sup>4</sup></a> despite this channel-induced ISI. It turns out that the same mechanism that needs to handle the channel-induced ISI (which changes based on the physical arrangement of the scatterers in the environment, and is estimated by the receiver, often <a href="least-squares.html">using known symbols</a>) can also handle the modulation-induced ISI as well.</p>
<h2 id="the-laurent-decomposition">the Laurent decomposition <a href="#the-laurent-decomposition" class="section">#</a></h2>
<p>The “Gaussian” in “GMSK” isn’t a filter that gets applied to the <em>time-domain</em> samples. Rather, it’s a filter that gets applied in the <em>frequency-domain</em>, and this frequency-domain signal gets used to feed an oscillator – and it’s that oscillator that generates the time-domain baseband signal.</p>
<p>The following 3 diagrams are from the wonderful <a href="https://descanso.jpl.nasa.gov/monograph/series3_chapter.html">Chapter 2 of Volume 3</a> of the <a href="https://descanso.jpl.nasa.gov/monograph/mono.html">JPL DESCANSO Book Series</a>.</p>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-diagram.png" alt="How GMSK gets made. Source: Page 65, Chapter 2, Volume 3, JPL DESCANSO Book Series" />
<figcaption aria-hidden="true">How GMSK gets made. Source: <a href="https://descanso.jpl.nasa.gov/monograph/series3_chapter.html">Page 65, Chapter 2, Volume 3, JPL DESCANSO Book Series</a></figcaption>
</figure>
<p>The Laurent decomposition tells us that the Gaussian-shaped GMSK frequency-domain pulse, after it gets digested by an oscillator, ends up being equivalent to two time-domain pulses (there are more but they are truly negligible), <span class="math inline">\(C_0\)</span> (the big one) and <span class="math inline">\(C_1\)</span> (the small one):</p>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-pulses.png" alt="The two Laurent decomposition pulses for GMSK. Source: Page 74, Chapter 2, Volume 3, JPL DESCANSO Book Series" />
<figcaption aria-hidden="true">The two Laurent decomposition pulses for GMSK. Source: <a href="https://descanso.jpl.nasa.gov/monograph/series3_chapter.html">Page 74, Chapter 2, Volume 3, JPL DESCANSO Book Series</a></figcaption>
</figure>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-modulator.png" alt="How to use the two Laurent pulses to produce a GMSK waveform. Source: Page 79, Chapter 2, Volume 3, JPL DESCANSO Book Series" />
<figcaption aria-hidden="true">How to use the two Laurent pulses to produce a GMSK waveform. Source: <a href="https://descanso.jpl.nasa.gov/monograph/series3_chapter.html">Page 79, Chapter 2, Volume 3, JPL DESCANSO Book Series</a></figcaption>
</figure>
<p>The first Laurent pulse is excited by a function of the current data symbol<a href="#fn5" class="footnote-ref" id="fnref5" role="doc-noteref"><sup>5</sup></a>. So far, so good. A suboptimal receiver can pretend that a GMSK waveform is only made of <span class="math inline">\(C_0\)</span> Laurent pulses. If you ignore the <span class="math inline">\(C_1\)</span> pulse, this reduces GMSK to MSK. <strong>MSK is not a linear modulation, and has nonzero ISI</strong>: the amplitude-domain pulse doesn’t have the zero-ISI property that RRC has.</p>
<p>However, if we have a good phase estimate, we can separate the MSK signal into in-phase (<span class="math inline">\(I\)</span>) and quadrature (<span class="math inline">\(Q\)</span>) signals. MSK<a href="#fn6" class="footnote-ref" id="fnref6" role="doc-noteref"><sup>6</sup></a> has a wonderful property once we’ve decomposed it this way: The “useful channel” alternates between <span class="math inline">\(I\)</span> and <span class="math inline">\(Q\)</span> for every symbol and contains no ISI, and the “other channel” (which alternates between <span class="math inline">\(Q\)</span> and <span class="math inline">\(I\)</span>) contains all the ISI.</p>
<p>To phrase it another way, on even symbols, the information needed to estimate the symbol is all in <span class="math inline">\(I\)</span>, and the ISI is all in <span class="math inline">\(Q\)</span>, and on odd symbols, the information needed to estimate the symbol is all in <span class="math inline">\(Q\)</span>, and the ISI is all in <span class="math inline">\(I\)</span>. Looking at <span class="math inline">\(I\)</span> and <span class="math inline">\(Q\)</span> separately eliminates the ISI, and this lets us make a receiver that looks much like a linear modulation receiver (integrate-and-dumps, comparators, etc) with close to ideal performance.</p>
<h2 id="the-modulator-has-memory">the modulator has memory <a href="#the-modulator-has-memory" class="section">#</a></h2>
<p>Stuff gets more interesting if you don’t ignore the second Laurent pulse. What’s that one excited by? Well, it’s a function of the current bit, the previous bit, <strong>and the bit before that</strong>! There’s even a little shift register on the bottom left!</p>
<p>Incidentally, that shift register isn’t just theoretical. If you implement a GMSK modulator with precomputed waveforms in a ROM (as opposed to using a Gaussian filter / integrator / NCO), there’s gonna be a shift register that looks much like that, which helps you index the ROM and postprocess the ROM output. I implemented a GMSK modulator in Verilog that uses precomputed waveforms, with the paper “Efficient implementation of an I-Q GMSK modulator” (doi://10.1109/82.481470 by Alfredo Linz and Alan Hendrickson) as a guide.</p>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-Linz1996-architecture.png" alt="GMSK modulator architecture. Source: Linz1996 (doi://10.1109/82.481470)" />
<figcaption aria-hidden="true">GMSK modulator architecture. Source: Linz1996 (doi://10.1109/82.481470)</figcaption>
</figure>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-defining-shift-reg.png" alt="I define that shift register in my Verilog. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)" />
<figcaption aria-hidden="true">I define that shift register in my Verilog. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)</figcaption>
</figure>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-shifting-in.png" alt="Shifting in new data symbols into the shift register. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)" />
<figcaption aria-hidden="true">Shifting in new data symbols into the shift register. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)</figcaption>
</figure>
<p>There’s 16 possible waveforms you need to be able to generate (8 possible values of the shift register; I and Q for each), but the structure of the modulation lets you cut down on ROM required: if you can time-reverse (index the ROM backwards) and/or sign-reverse (flip the sign of the samples coming <em>out</em> of the ROM), you can store just 4 basic curves in the ROM and generate all 16 waveforms that way.</p>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-which-ROM.png" alt="The shift register determines which basic curves get used. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)" />
<figcaption aria-hidden="true">The shift register determines which basic curves get used. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)</figcaption>
</figure>
<figure>
<img src="../images/GMSK-Laurent/8Dec2022-GMSK-Laurent-postprocessing.png" alt="One bit of the shift register, along with another bit of state (accumulated phase quadrant), determines how we post-process the output of the ROM. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)" />
<figcaption aria-hidden="true">One bit of the shift register, along with another bit of state (accumulated phase quadrant), determines how we post-process the output of the ROM. Source: a GMSK modulator I wrote a while ago, based on the design in Linz1996 (doi://10.1109/82.481470)</figcaption>
</figure>
<p>Unlike with RRC, there’s no magic filter that nulls out GMSK’s ISI/memory. Unlike with MSK, separating <span class="math inline">\(I\)</span> and <span class="math inline">\(Q\)</span> doesn’t neatly separate the data and the ISI.</p>
<h2 id="detection-theory-tldr">detection theory tl;dr <a href="#detection-theory-tldr" class="section">#</a></h2>
<p>Every time a demodulator receives a new sample (or receives <span class="math inline">\(n\)</span> new samples if there are <span class="math inline">\(n\)</span> samples per symbol), it needs to decide what symbol was most likely to generate that sample. If it didn’t do something like that, it wouldn’t be much of a demodulator.</p>
<p>If the modulator has no memory, this task is pretty simple: we look at the sample values <strong>each possible</strong> symbol would have generated, and we compare each of those gold-standard values against the value we <em>actually received</em>. Which symbol was most likely to have been sent? The symbol whose value is the closest to what was actually received.</p>
<p>How accurate is this? Depends on how many possible symbols there are! Increase the number of possible symbols (“bits per symbol”, “modulation order”), and this decreases the amplitude of noise necessary to sufficiently shift the received sample such that the closest symbol is incorrect.</p>
<h2 id="the-third-eye-of-the-demodulator">the third eye of the demodulator <a href="#the-third-eye-of-the-demodulator" class="section">#</a></h2>
<p>If the modulator has memory, this task is more complicated. The signal that the modulator generates for a symbol don’t just depend on the current symbol, but on a certain number of past symbols as well.</p>
<p>If the demodulator wants to extract the most possible information from the received signal, it needs to read the modulator’s mind.</p>
<p>Assume the demodulator has access to a perfect mind-reading channel: we can see into all of the modulator’s state – except for what’s affected by the current symbol. The latter proviso prevents the demodulator’s task from becoming trivial. Via the mind-reading channel, the demodulator knows the last two bits the modulator sent: call them <span class="math inline">\(b_1\)</span> and <span class="math inline">\(b_2\)</span>. There’s a standard assumption that the transmitted signal is a random bitstream, so knowing <span class="math inline">\(b_1\)</span> and <span class="math inline">\(b_2\)</span> gives the demodulator strictly zero information about <span class="math inline">\(b_3\)</span>.</p>
<p>The demodulator actually has to estimate <span class="math inline">\(b_3\)</span> from the noisy received signal, like usual. However, that task is actually solvable now! We have a local copy of a GMSK modulator, and we generate two candidate signals: one with the sequence <span class="math inline">\((b_1, b_2, 0)\)</span>, and one with the sequence <span class="math inline">\((b_1, b_2, 1)\)</span>. If what was actually received is closer to the former, we decide a <span class="math inline">\(0\)</span> was sent, if the latter is closer, we decide a <span class="math inline">\(1\)</span> was sent.</p>
<p>You see where this is going! We estimated a value for <span class="math inline">\(b_3\)</span> – call it <span class="math inline">\({b\_estimated}_3\)</span> – by comparing the two possible alternatives. Now, when the modulator sends <span class="math inline">\(b_4\)</span>, we don’t need the mind-reading channel anymore! <strong>We already have our best estimate for what <span class="math inline">\(b_3\)</span> was, and we can use that <span class="math inline">\({b\_estimated}_3\)</span> to find <span class="math inline">\(b_4\)</span>!</strong> Indeed, we use our local GMSK modulator to modulate <span class="math inline">\((b_2, {b\_estimated}_3, 0)\)</span>, and <span class="math inline">\((b_2, {b\_estimated}_3, 1)\)</span> and use that to determine what <span class="math inline">\(b_4\)</span> likely is.</p>
<h2 id="third-eye-closed">third eye closed <a href="#third-eye-closed" class="section">#</a></h2>
<p>Unfortunately, eschewing the mind-reading channel isn’t free. The clunky <span class="math inline">\({b\_estimated}_3\)</span> notation foreshadowed that <span class="math inline">\({b\_estimated}_3\)</span> and <span class="math inline">\(b_3\)</span> aren’t guaranteed to be equal. <span class="math inline">\({b\_estimated}_3\)</span> might be the best possible estimate we can make but it still can be incorrect!</p>
<p>If <span class="math inline">\({b\_estimated}_3 \neq b_3\)</span> and we try and guess what <span class="math inline">\(b_4\)</span> is by using <span class="math inline">\((b_2, {b\_estimated}_3, 0)\)</span> and <span class="math inline">\((b_2, {b\_estimated}_3, 1)\)</span> as references, we’re in for a world of hurt. The error with <span class="math inline">\({b\_estimated}_3\)</span> is forgivable (there’s noise, errors happen), but using an incorrect value of <span class="math inline">\(b_3\)</span> to estimate <span class="math inline">\(b_4\)</span> <strong>propagates that error into <span class="math inline">\({b\_estimated}_4\)</span></strong>…which will propagate into <span class="math inline">\({b\_estimated}_5\)</span>, and so on.</p>
<p>We want to <em>average</em> out errors, not <em>propagate</em> them!</p>
<p>If we still had our mind-reading channel, we would know the true value of <span class="math inline">\(b_3\)</span> was (of course, only after we commit ourselves to <span class="math inline">\({b\_estimated}_3\)</span>, otherwise the game is trivial), and use that to estimate <span class="math inline">\(b_4\)</span>, by using <span class="math inline">\((b_2, b_3, 0)\)</span> and <span class="math inline">\((b_2, b_3, 1)\)</span> for comparison against our received signal.</p>
<p>We’re at a loss here, because mind-reading channels don’t exist, but if we don’t use the mind-reading channel, our uncertain guesses can amplify errors.</p>
<h2 id="you-are-the-third-eye">you are the third eye <a href="#you-are-the-third-eye" class="section">#</a></h2>
<p>It turns out we were almost on the right track. We can turn this error-amplification<a href="#fn7" class="footnote-ref" id="fnref7" role="doc-noteref"><sup>7</sup></a> scheme into something truly magical (a sort of magic that actually exists) if we</p>
<h1 id="avoid-making-decisions-until-the-last-possible-moment.">avoid making decisions until the last possible moment.</h1>
<p>We have to make decisions on uncertain data. However, this doesn’t oblige us to make a decision for <span class="math inline">\(b_i\)</span> <em>as soon as it is possible to make a better-than-chance decision</em> for <span class="math inline">\(b_i\)</span>! If there’s useful data that arrives <em>after</em> we have committed to a decision on <span class="math inline">\(b_i\)</span>, we’re throwing that data away – at least when it comes to estimating <span class="math inline">\(b_i\)</span>.</p>
<p>In fact, if we want to do the best job we can, we’ll keep accumulating incoming data until the incoming data tells us <em>nothing</em> about <span class="math inline">\(b_i\)</span>. Only then will we make a decision for <span class="math inline">\(b_i\)</span>, since we’ve collected all the relevant data that could possibly be useful for its estimation.</p>
<p>But how do we add up all that information? What metrics get used to compare different possibilities? How will this series of selections estimate the sequence of symbols that most likely entered the modulator? And how do we avoid a combinatorial explosion?</p>
<h2 id="further-reading">further reading <a href="#further-reading" class="section">#</a></h2>
<ul>
<li><a href="https://people.kth.se/~e95_abr/filer/efficient_IQ_GMSK.pdf">“Efficient implementation of an I-Q GMSK modulator”</a> (doi://10.1109/82.481470 by Alfredo Linz and Alan Hendrickson)</li>
<li><a href="https://www.ice.rwth-aachen.de/fileadmin/Publications/Attachments/Lambrette95TIRR.pdf">“Comparison of Demodulation Techniques for MSK”</a> by Uwe Lambrette, Ralf Mehlan, and Heinrich Meyr</li>
<li><a href="https://ieeexplore.ieee.org/document/4390045">“GMSK Demodulator Implementation for ESA Deep-Space Missions”</a>, by Gunther M. A. Sessler; Ricard Abello; Nick James; Roberto Madde; Enrico Vassallo</li>
<li><a href="https://descanso.jpl.nasa.gov/monograph/series3_chapter.html">Chapter 2 of Volume 3</a> (“Bandwidth-Efficient Digital Modulation with Application to Deep-Space Communications”) of the <a href="https://descanso.jpl.nasa.gov/monograph/mono.html">JPL DESCANSO Book Series</a>, by Marvin K. Simon</li>
</ul>
<section id="footnotes" class="footnotes footnotes-end-of-document" role="doc-endnotes">
<hr />
<ol>
<li id="fn1"><p>(with an RRC receive filter at the receiver)<a href="#fnref1" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn2"><p>ideal coaxial cable has a velocity factor of 1<a href="#fnref2" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn3"><p>unless you’re on shortwave/HF, where it <em>is</em> possible to get echoes since the ionosphere sometimes <em>does</em> give rise to paths with drastically different distances and without catastrophic attenuation<a href="#fnref3" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn4"><p>The equalization task with OFDM is greatly simplified: orthogonal frequency-domain subcarriers + circular prefixes create a circulant matrix. The receiver does a big FFT, and the properties of the circulant matrix means the effect of a dispersive channel is limited to multiplying the output of each subcarrier by a complex coefficient. That complex coefficient is merely the amplitude/phase response of the channel, measured at that subcarrier’s frequency. In real-world systems you need a way to estimate those complex coefficients for each subcarrier (symbols with known/fixed values are useful for this), a way to adapt them as the channel changes over time, and a way to cope with Doppler.<a href="#fnref4" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn5"><p>This figure says “precoded” which means that if you want to get the same result, you need to put a differential encoder in front of the bitstream input; but using this diagram (instead of “Fig. 2-33” in the same chapter) more clearly demonstrates that GSM has a 3-symbol memory.<a href="#fnref5" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn6"><p>for <span class="math inline">\(h=0.5\)</span> full-response continuous-phase modulations more generally<a href="#fnref6" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
<li id="fn7"><p>This scheme actually works fine if most of the energy in the channel/modulator impulse response lives in the earliest coefficient; since the guesses will just…tend to be right most of the time! However, that’s not generally the case, RF channels are rarely this friendly, unless line of sight dominates. You can shorten an unfriendly channel by decomposing its impulse response into an all-pass filter and a minimum-phase filter (whose energy will indeed be front-loaded), but it probably won’t guarantee you a channel that lets you get away with avoiding a trellis altogether…<a href="#fnref7" class="footnote-back" role="doc-backlink">↩︎</a></p></li>
</ol>
</section>]]></summary>
</entry>

</feed>